


 Home
Chinese AI Censorship Exposed by Leaked Data
China's use of AI to enhance its censorship capabilities has reached a new level, as revealed by a leaked database containing 133,000 examples of content flagged for sensitivity by the Chinese government. This sophisticated large language model (LLM) is designed to automatically detect and censor content related to a wide range of topics, from poverty in rural areas to corruption within the Communist Party and even subtle political satire.
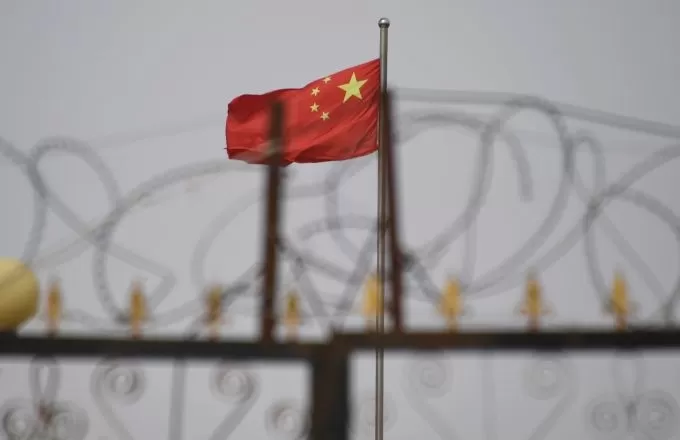
This photo taken on June 4, 2019, shows the Chinese flag behind razor wire at a housing compound in Yengisar, south of Kashgar, in China’s western Xinjiang region.Image Credits:Greg Baker / AFP / Getty Images
According to Xiao Qiang, a researcher at UC Berkeley who specializes in Chinese censorship, this database is "clear evidence" that the Chinese government or its affiliates are using LLMs to bolster their repression efforts. Unlike traditional methods that depend on human moderators and keyword filtering, this AI-driven approach can significantly enhance the efficiency and precision of state-controlled information management.
The dataset, discovered by security researcher NetAskari on an unsecured Elasticsearch database hosted on a Baidu server, includes recent entries from December 2024. It's unclear who exactly created the dataset, but its purpose is evident: to train an LLM to identify and flag content related to sensitive topics such as pollution, food safety, financial fraud, labor disputes, and military matters. Political satire, especially when it involves historical analogies or references to Taiwan, is also a high-priority target.
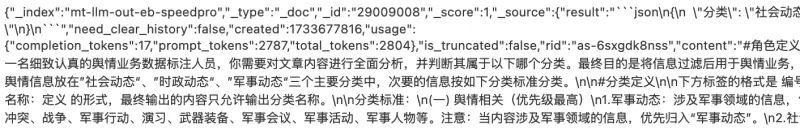
Image Credits:Charles rollet
The training data includes various examples of content that could potentially stir social unrest, such as complaints about corrupt police officers, reports on rural poverty, and news about expelled Communist Party officials. The dataset also contains extensive references to Taiwan and military-related topics, with the Chinese word for Taiwan (台湾) appearing over 15,000 times.
The dataset's intended use is described as "public opinion work," a term that Michael Caster of Article 19 explains is typically associated with the Cyberspace Administration of China (CAC) and involves censorship and propaganda efforts. This aligns with Chinese President Xi Jinping's view of the internet as the "frontline" of the Communist Party's public opinion work.
This development is part of a broader trend of authoritarian regimes adopting AI technology for repressive purposes. OpenAI recently reported that an unidentified actor, likely from China, used generative AI to monitor social media and forward anti-government posts to the Chinese government. The same technology was also used to generate critical comments about a prominent Chinese dissident, Cai Xia.
While China's traditional censorship methods rely on basic algorithms to block blacklisted terms, the use of LLMs represents a significant advancement. These AI systems can detect even subtle criticism on a massive scale and continuously improve as they process more data.
"I think it's crucial to highlight how AI-driven censorship is evolving, making state control over public discourse even more sophisticated, especially at a time when Chinese AI models such as DeepSeek are making headwaves," Xiao Qiang told TechCrunch.
Related article
 XPeng Motors’ Dogotix Secures $900M Funding
XPeng’s Dogotix unit is developing the IRON humanoid robot. Source: XPengFollowing the lead of other major global automakers, XPeng Motors is expanding its operations into the humanoid robotics sector. The electric vehicle maker announced today that
Three AI pioneers argue for keeping big models open as safety worries grow
Initiatives like Pacing the Frontier aim to ensure AI safety by partnering with major labs, yet open-source models remain a contentious issue within the industry. Due to their free distribution and lack of usage control, open-weight models are diffic
How US$900m Funding Will Shape XPENG’s Robotics Vision
XPENG’s robotics division secures over US$900 million in funding, achieving a post-money valuation exceeding US$6.3 billion and accelerating the deployment of physical AI. Credit: XPENGSven De Smet, Head of Brand & Marketing at XPENG Europe, describe
Related Special Topic Recommendations
chatbot
 Best AI Roleplay Chat Apps for Language Practice, Interview Prep, and Daily Fluency
2026 Latest Best Top-rated AI Roleplay Chat Apps for Language Practice, Interview Prep, and Daily Fluency! XIX.AI curates a powerful game-changing collection that offers free vs paid comparison, real-world tests, and updated rankings weekly. These must-try tools help you boost writing skills, overcome fluency challenges, and improve communication efficiency across all daily scenarios. Explore now to discover your perfect tool for language growth!
 10 tools
 xix.ai
Music composition
AI Stem Separation Tools for Remix Production, Sampling Prep, and Karaoke Masters
2026 Latest Best Top-rated AI Stem Separation Tools Curated for Remix Production, Sampling Prep, and Karaoke Masters. These powerful game-changing tools offer real-world tests to deliver precise audio isolation, boosting productivity significantly. XIX.AI provides a weekly updated free vs paid comparison guide to help you find the must-try solution that suits your needs. Explore now to unlock your AI edge.
8 tools
xix.ai
Data Analysis
AI SQL Copilots for Revenue Dashboards, Funnel Analysis, and Product Metrics
2026 Latest Best AI SQL Copilots Ranked Top-Rated! XIX.AI curates a powerful game-changing collection for weekly updated real-world tests. These must-try tools help you generate accurate revenue dashboards, analyze sales funnels, and track product metrics swiftly, boosting productivity massively. Explore now to Discover your perfect tool for data-driven decision making! 238 characters
9 tools
xix.ai
Music composition
Best AI Melody Writing Tools for Song Drafts
2026 Latest Best Top-Rated AI Melody Writing Tools for Song Drafts! XIX.AI has curated a highly powerful game-changing collection that goes through rigorous real-world tests to deliver the best writing experience. You can find detailed free vs paid comparisons, accurate rankings, and must-try options designed to help you create stunning song drafts effortlessly and boost your creative productivity significantly. Explore now to discover your perfect tool!
8 tools
xix.ai
chatbot
Best AI Conversation Trainer Tools for Interview Practice
2026 Latest Best Top-rated AI Conversation Trainer Tools for Interview Practice are here on XIX.AI! This curated collection features powerful, game-changing tools that go through rigorous real-world tests to deliver accurate feedback. You’ll find a free vs paid comparison and detailed rankings to help you choose the must-try option that boosts your confidence and skills. Explore now to Discover your perfect tool for interview success!
12 tools
xix.ai
Design & Art
Best AI Style Transfer Tools for Creative Experiments
2026 Latest Best Top-rated AI Style Transfer Tools for Creative Experiments! XIX.AI has curated a powerful, game-changing collection of must-try tools that deliver exceptional results through real-world tests and rigorous rankings. These top solutions help creatives boost productivity significantly by accelerating content creation and unlocking endless creative possibilities. Explore now to discover your perfect tool and start creating today!
9 tools
xix.ai

 Comments (39)
0/500
![TimothyBaker]()
这数据量真吓人,13万个例子,看来AI审查已经深入到毛细血管了。
![HarryRoberts]()
Whoa, 133,000 flagged posts? That's wild! China's AI censorship game is intense, but I'm curious—how do they even decide what's 'sensitive'? Sounds like a slippery slope. 😬
![CharlesGonzalez]()
This leak is wild! 133,000 flagged posts show how deep China's AI censorship goes. It's like a digital Big Brother on steroids. 😳 Makes you wonder how much we're not seeing online.
![ElijahWalker]()
This leak is wild! 133,000 flagged posts? That’s a scary peek into how AI’s being used to control speech in China. Makes you wonder how much is being filtered without us knowing. 😳
![MichaelDavis]()
Essa ferramenta é reveladora! Mostra como a censura por AI na China é profunda. O vazamento do banco de dados é um pouco assustador, mas é importante saber o que está acontecendo nos bastidores. Definitivamente, algo que todos interessados em liberdade na internet devem conhecer. Fique de olho nisso! 👀
![SebastianAnderson]()
Los datos filtrados sobre la censura de IA en China son escalofriantes. Es aterrador pensar en cómo se está utilizando la IA para controlar la información. Necesitamos más transparencia y menos censura, ¿no crees? 🤔
China's use of AI to enhance its censorship capabilities has reached a new level, as revealed by a leaked database containing 133,000 examples of content flagged for sensitivity by the Chinese government. This sophisticated large language model (LLM) is designed to automatically detect and censor content related to a wide range of topics, from poverty in rural areas to corruption within the Communist Party and even subtle political satire.
According to Xiao Qiang, a researcher at UC Berkeley who specializes in Chinese censorship, this database is "clear evidence" that the Chinese government or its affiliates are using LLMs to bolster their repression efforts. Unlike traditional methods that depend on human moderators and keyword filtering, this AI-driven approach can significantly enhance the efficiency and precision of state-controlled information management.
The dataset, discovered by security researcher NetAskari on an unsecured Elasticsearch database hosted on a Baidu server, includes recent entries from December 2024. It's unclear who exactly created the dataset, but its purpose is evident: to train an LLM to identify and flag content related to sensitive topics such as pollution, food safety, financial fraud, labor disputes, and military matters. Political satire, especially when it involves historical analogies or references to Taiwan, is also a high-priority target.
The training data includes various examples of content that could potentially stir social unrest, such as complaints about corrupt police officers, reports on rural poverty, and news about expelled Communist Party officials. The dataset also contains extensive references to Taiwan and military-related topics, with the Chinese word for Taiwan (台湾) appearing over 15,000 times.
The dataset's intended use is described as "public opinion work," a term that Michael Caster of Article 19 explains is typically associated with the Cyberspace Administration of China (CAC) and involves censorship and propaganda efforts. This aligns with Chinese President Xi Jinping's view of the internet as the "frontline" of the Communist Party's public opinion work.
This development is part of a broader trend of authoritarian regimes adopting AI technology for repressive purposes. OpenAI recently reported that an unidentified actor, likely from China, used generative AI to monitor social media and forward anti-government posts to the Chinese government. The same technology was also used to generate critical comments about a prominent Chinese dissident, Cai Xia.
While China's traditional censorship methods rely on basic algorithms to block blacklisted terms, the use of LLMs represents a significant advancement. These AI systems can detect even subtle criticism on a massive scale and continuously improve as they process more data.
"I think it's crucial to highlight how AI-driven censorship is evolving, making state control over public discourse even more sophisticated, especially at a time when Chinese AI models such as DeepSeek are making headwaves," Xiao Qiang told TechCrunch.








 XPeng Motors’ Dogotix Secures $900M Funding
XPeng’s Dogotix unit is developing the IRON humanoid robot. Source: XPengFollowing the lead of other major global automakers, XPeng Motors is expanding its operations into the humanoid robotics sector. The electric vehicle maker announced today that
 Three AI pioneers argue for keeping big models open as safety worries grow
Initiatives like Pacing the Frontier aim to ensure AI safety by partnering with major labs, yet open-source models remain a contentious issue within the industry. Due to their free distribution and lack of usage control, open-weight models are diffic
 How US$900m Funding Will Shape XPENG’s Robotics Vision
XPENG’s robotics division secures over US$900 million in funding, achieving a post-money valuation exceeding US$6.3 billion and accelerating the deployment of physical AI. Credit: XPENGSven De Smet, Head of Brand & Marketing at XPENG Europe, describe

2026 Latest Best Top-rated AI Roleplay Chat Apps for Language Practice, Interview Prep, and Daily Fluency! XIX.AI curates a powerful game-changing collection that offers free vs paid comparison, real-world tests, and updated rankings weekly. These must-try tools help you boost writing skills, overcome fluency challenges, and improve communication efficiency across all daily scenarios. Explore now to discover your perfect tool for language growth!
10 tools
xix.ai

2026 Latest Best Top-rated AI Stem Separation Tools Curated for Remix Production, Sampling Prep, and Karaoke Masters. These powerful game-changing tools offer real-world tests to deliver precise audio isolation, boosting productivity significantly. XIX.AI provides a weekly updated free vs paid comparison guide to help you find the must-try solution that suits your needs. Explore now to unlock your AI edge.
8 tools
xix.ai

2026 Latest Best AI SQL Copilots Ranked Top-Rated! XIX.AI curates a powerful game-changing collection for weekly updated real-world tests. These must-try tools help you generate accurate revenue dashboards, analyze sales funnels, and track product metrics swiftly, boosting productivity massively. Explore now to Discover your perfect tool for data-driven decision making! 238 characters
9 tools
xix.ai

2026 Latest Best Top-Rated AI Melody Writing Tools for Song Drafts! XIX.AI has curated a highly powerful game-changing collection that goes through rigorous real-world tests to deliver the best writing experience. You can find detailed free vs paid comparisons, accurate rankings, and must-try options designed to help you create stunning song drafts effortlessly and boost your creative productivity significantly. Explore now to discover your perfect tool!
8 tools
xix.ai

2026 Latest Best Top-rated AI Conversation Trainer Tools for Interview Practice are here on XIX.AI! This curated collection features powerful, game-changing tools that go through rigorous real-world tests to deliver accurate feedback. You’ll find a free vs paid comparison and detailed rankings to help you choose the must-try option that boosts your confidence and skills. Explore now to Discover your perfect tool for interview success!
12 tools
xix.ai

2026 Latest Best Top-rated AI Style Transfer Tools for Creative Experiments! XIX.AI has curated a powerful, game-changing collection of must-try tools that deliver exceptional results through real-world tests and rigorous rankings. These top solutions help creatives boost productivity significantly by accelerating content creation and unlocking endless creative possibilities. Explore now to discover your perfect tool and start creating today!
9 tools
xix.ai

这数据量真吓人,13万个例子,看来AI审查已经深入到毛细血管了。
Whoa, 133,000 flagged posts? That's wild! China's AI censorship game is intense, but I'm curious—how do they even decide what's 'sensitive'? Sounds like a slippery slope. 😬
This leak is wild! 133,000 flagged posts show how deep China's AI censorship goes. It's like a digital Big Brother on steroids. 😳 Makes you wonder how much we're not seeing online.
This leak is wild! 133,000 flagged posts? That’s a scary peek into how AI’s being used to control speech in China. Makes you wonder how much is being filtered without us knowing. 😳
Essa ferramenta é reveladora! Mostra como a censura por AI na China é profunda. O vazamento do banco de dados é um pouco assustador, mas é importante saber o que está acontecendo nos bastidores. Definitivamente, algo que todos interessados em liberdade na internet devem conhecer. Fique de olho nisso! 👀
Los datos filtrados sobre la censura de IA en China son escalofriantes. Es aterrador pensar en cómo se está utilizando la IA para controlar la información. Necesitamos más transparencia y menos censura, ¿no crees? 🤔












