


 Home
Meta's AI Model Benchmarks: Misleading?
So, Meta dropped their new AI model, Maverick, over the weekend, and it's already making waves by snagging second place on LM Arena. You know, that's the place where humans get to play judge and jury, comparing different AI models and picking their favorites. But, hold up, there's a twist! It turns out the Maverick version strutting its stuff on LM Arena isn't quite the same as the one you can download and play with as a developer.
Some eagle-eyed AI researchers on X (yeah, the platform formerly known as Twitter) spotted that Meta called the LM Arena version an "experimental chat version." And if you peek at the Llama website, there's a chart that spills the beans, saying the testing was done with "Llama 4 Maverick optimized for conversationality." Now, we've talked about this before, but LM Arena isn't exactly the gold standard for measuring AI performance. Most AI companies don't mess with their models just to score better on this test—or at least, they don't admit to it.
The thing is, when you tweak a model to ace a benchmark but then release a different "vanilla" version to the public, it's tough for developers to figure out how well the model will actually perform in real-world scenarios. Plus, it's kinda misleading, right? Benchmarks, flawed as they are, should give us a clear picture of what a model can and can't do across different tasks.
Researchers on X have been quick to notice some big differences between the Maverick you can download and the one on LM Arena. The Arena version is apparently all about emojis and loves to give you long, drawn-out answers.
Okay Llama 4 is def a littled cooked lol, what is this yap city pic.twitter.com/y3GvhbVz65
— Nathan Lambert (@natolambert) April 6, 2025
for some reason, the Llama 4 model in Arena uses a lot more Emojis
on together . ai, it seems better: pic.twitter.com/f74ODX4zTt
— Tech Dev Notes (@techdevnotes) April 6, 2025
We've reached out to Meta and the folks at Chatbot Arena, who run LM Arena, to see what they have to say about all this. Stay tuned!
Related article
 Meta's Muse outpaces ChatGPT in early mobile launch
New data suggests Meta’s latest AI app, Muse, could become the social giant’s next major success. According to recent estimates from Appfigures, Muse has been downloaded on mobile devices more times in its first twelve days than ChatGPT did in the tw
Meta’s Muse arrives on Mac, enabling AI to perform actions on your computer
Meta’s latest AI assistant, Muse, is now live on Mac.On macOS, Muse integrates with your files, messages, calendar, notes, and mail, operating directly within their native apps.This desktop release follows Muse’s mobile and web debut earlier this mon
Zuckerberg expands Meta’s enterprise AI vision beyond agents
In June, Meta launched a new AI agent for enterprises, designed to assist with customer service, support, and daily operations. However, CEO Mark Zuckerberg revealed to investors on Wednesday’s second-quarter earnings call that the company’s enterpri
Related Special Topic Recommendations
Design & Art
 Top AI Illustration Tools: Create Editorial Scenes and Cover Art Faster
2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
 10 tools
 xix.ai
Education and Learning
Top AI Tutors for Exam Prep: Practice Math, Science, and English
2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai
Finance
AI Budget Planning Tools for Personal Money Management
2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai
Health & Wellness
AI Sleep Tracking Assistants: Improve Recovery with Better Bedtime Habits
2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai
Data Analysis
AI SQL Copilots for Product and Revenue Analytics
2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai
Education and Learning
Best AI Homework Helpers That Teach: Learn Concepts, Not Just Answers
2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai

 Comments (37)
0/500
![RalphGarcia]()
メタのAIベンチマークって怪しくない?🤔 人間が好みで評価するランダムなランキングより、実用的なテストの方が信用できると思う。結局ベンチマークゲームに夢中になる企業より、実際に役立つAIを作ってる会社の方が価値あるよね。 #AIベンチマーク
![ScottWalker]()
Meta's Maverick hitting second on LM Arena? Impressive, but I'm skeptical about those benchmarks. Feels like a hype train—wonder if it’s more flash than substance. 🤔 Anyone tested it in real-world tasks yet?
![KennethMartin]()
Meta's Maverick AI model is impressive, snagging second place on LM Arena! But are the benchmarks really telling the whole story? It's cool to see AI models go head-to-head, but I'm not sure if it's all fair play. Makes you wonder, right? 🤔 Maybe we need a more transparent way to judge these models!
![WalterThomas]()
मेटा का नया AI मॉडल, मैवरिक, LM एरिना में दूसरे स्थान पर पहुंचा! यह प्रभावशाली है, लेकिन क्या बेंचमार्क वास्तव में पूरी कहानी बता रहे हैं? AI मॉडल्स को आपस में प्रतिस्पर्धा करते देखना मजेदार है, लेकिन मुझे नहीं पता कि यह निष्पक्ष है या नहीं। आपको सोचने पर मजबूर करता है, है ना? 🤔 शायद हमें इन मॉडल्स को जज करने का एक और पारदर्शी तरीका चाहिए!
![JohnYoung]()
메타의 새로운 AI 모델, 마브릭이 LM Arena에서 2위를 차지하다니 대단해요! 하지만 벤치마크가 정말 모든 것을 말해주고 있는지 궁금해요. AI 모델 간의 경쟁은 재미있지만, 공정한지 확신할 수 없네요. 더 투명한 평가 방법이 필요할 것 같아요 🤔
![JohnHernández]()
Meta's Maverick AI model snagging second place on LM Arena is pretty cool, but the benchmarks might be a bit off! 🤔 It's fun to see these models go head-to-head, but I'm not sure if the results are totally fair. Worth keeping an eye on! 👀
So, Meta dropped their new AI model, Maverick, over the weekend, and it's already making waves by snagging second place on LM Arena. You know, that's the place where humans get to play judge and jury, comparing different AI models and picking their favorites. But, hold up, there's a twist! It turns out the Maverick version strutting its stuff on LM Arena isn't quite the same as the one you can download and play with as a developer.
Some eagle-eyed AI researchers on X (yeah, the platform formerly known as Twitter) spotted that Meta called the LM Arena version an "experimental chat version." And if you peek at the Llama website, there's a chart that spills the beans, saying the testing was done with "Llama 4 Maverick optimized for conversationality." Now, we've talked about this before, but LM Arena isn't exactly the gold standard for measuring AI performance. Most AI companies don't mess with their models just to score better on this test—or at least, they don't admit to it.
The thing is, when you tweak a model to ace a benchmark but then release a different "vanilla" version to the public, it's tough for developers to figure out how well the model will actually perform in real-world scenarios. Plus, it's kinda misleading, right? Benchmarks, flawed as they are, should give us a clear picture of what a model can and can't do across different tasks.
Researchers on X have been quick to notice some big differences between the Maverick you can download and the one on LM Arena. The Arena version is apparently all about emojis and loves to give you long, drawn-out answers.
Okay Llama 4 is def a littled cooked lol, what is this yap city pic.twitter.com/y3GvhbVz65
— Nathan Lambert (@natolambert) April 6, 2025
for some reason, the Llama 4 model in Arena uses a lot more Emojis
— Tech Dev Notes (@techdevnotes) April 6, 2025
on together . ai, it seems better: pic.twitter.com/f74ODX4zTt
We've reached out to Meta and the folks at Chatbot Arena, who run LM Arena, to see what they have to say about all this. Stay tuned!








 Meta's Muse outpaces ChatGPT in early mobile launch
New data suggests Meta’s latest AI app, Muse, could become the social giant’s next major success. According to recent estimates from Appfigures, Muse has been downloaded on mobile devices more times in its first twelve days than ChatGPT did in the tw
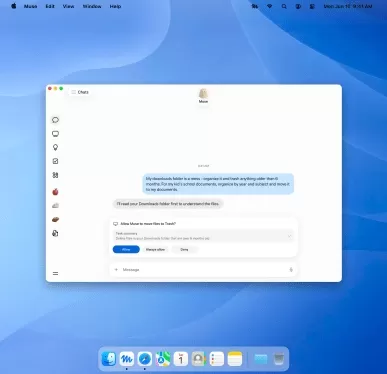 Meta’s Muse arrives on Mac, enabling AI to perform actions on your computer
Meta’s latest AI assistant, Muse, is now live on Mac.On macOS, Muse integrates with your files, messages, calendar, notes, and mail, operating directly within their native apps.This desktop release follows Muse’s mobile and web debut earlier this mon
 Zuckerberg expands Meta’s enterprise AI vision beyond agents
In June, Meta launched a new AI agent for enterprises, designed to assist with customer service, support, and daily operations. However, CEO Mark Zuckerberg revealed to investors on Wednesday’s second-quarter earnings call that the company’s enterpri

2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
10 tools
xix.ai

2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai

2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai

2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai

メタのAIベンチマークって怪しくない?🤔 人間が好みで評価するランダムなランキングより、実用的なテストの方が信用できると思う。結局ベンチマークゲームに夢中になる企業より、実際に役立つAIを作ってる会社の方が価値あるよね。 #AIベンチマーク
Meta's Maverick hitting second on LM Arena? Impressive, but I'm skeptical about those benchmarks. Feels like a hype train—wonder if it’s more flash than substance. 🤔 Anyone tested it in real-world tasks yet?
Meta's Maverick AI model is impressive, snagging second place on LM Arena! But are the benchmarks really telling the whole story? It's cool to see AI models go head-to-head, but I'm not sure if it's all fair play. Makes you wonder, right? 🤔 Maybe we need a more transparent way to judge these models!
मेटा का नया AI मॉडल, मैवरिक, LM एरिना में दूसरे स्थान पर पहुंचा! यह प्रभावशाली है, लेकिन क्या बेंचमार्क वास्तव में पूरी कहानी बता रहे हैं? AI मॉडल्स को आपस में प्रतिस्पर्धा करते देखना मजेदार है, लेकिन मुझे नहीं पता कि यह निष्पक्ष है या नहीं। आपको सोचने पर मजबूर करता है, है ना? 🤔 शायद हमें इन मॉडल्स को जज करने का एक और पारदर्शी तरीका चाहिए!
메타의 새로운 AI 모델, 마브릭이 LM Arena에서 2위를 차지하다니 대단해요! 하지만 벤치마크가 정말 모든 것을 말해주고 있는지 궁금해요. AI 모델 간의 경쟁은 재미있지만, 공정한지 확신할 수 없네요. 더 투명한 평가 방법이 필요할 것 같아요 🤔
Meta's Maverick AI model snagging second place on LM Arena is pretty cool, but the benchmarks might be a bit off! 🤔 It's fun to see these models go head-to-head, but I'm not sure if the results are totally fair. Worth keeping an eye on! 👀












