


 Home
GPT-5.6 IQ Breaks 130 Genius Line, Smarter Than 99% of Humans, Practical Work Ability Also Extraordinary
Tracking AI’s latest offline IQ assessment reveals that multiple iterations of OpenAI’s GPT-5.6 achieved a score of 136, marking the first instance of a large language model exceeding the 130 IQ benchmark. In standard human distribution, an IQ of 130 signifies the threshold for “genius,” a level attained by merely 1% of the global population, effectively positioning GPT-5.6 as more intelligent than 99% of people.
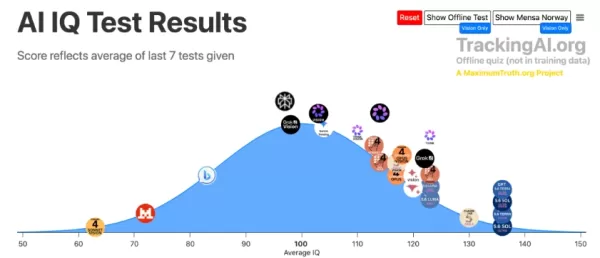
Scoring 136 on the most rigorous, anti-leakage question bank, GPT-5.6 significantly outperformed its competitors.
Tracking AI utilized two distinct testing frameworks: an open-source Mensa Norway-style exam, where models already exceeded 140 points, and a proprietary, undisclosed offline question bank designed to prevent pre-memorization. GPT-5.6 successfully navigated this challenging offline dataset, with the entire SOL and TERRA family scoring 136, including its visual variant. Claude-5 Fable followed with 130 points, while GPT-5.6 LUNA Max and Claude-4.8 Opus lagged between 117 and 123 points. While models ranging from o3 to various flagship systems have historically plateaued at the 130 threshold, GPT-5.6 has become the first to break through.
Beyond test scores, GPT-5.6 demonstrates exceptional performance in practical applications.
High test metrics alone do not guarantee utility. Developers evaluated GPT-5.6 in real-world scenarios with striking results. When developer Amir Bohlooli submitted an identical physical simulation prompt to both Fable5 and GPT-5.6 Sol, he anticipated Fable’s dominance. Instead, GPT-5.6 Sol executed a particle fluid simulation with real-time physics, encapsulating CSS, interface design, and rendering within a single HTML file. It automatically hosted the result as a shareable web page, delivering a complete product from a single prompt. Similarly, Ramanpal Singh developed a customer ticket system using RAG with one prompt, incorporating four distinct roles, a management backend, automated complaint classification, and emotion recognition. This complex setup required only a fraction of the cost associated with Fable5.
Claire Vo’s experience highlighted these practical advantages. After encountering a persistent bug that she believed had crashed her code, she switched to GPT-5.6 Sol, remarking, “I won’t let this beat me.” Sol resolved the issue immediately and assisted other models in running smoothly. Vo’s assessment was clear: Fable’s rigid focus on technical precision hindered its effectiveness, whereas Sol’s pragmatic approach delivered tangible results.
Related article
 How to check Google ranking for free?
A QR Code you cannot track is a guess. You print it, you hope, and you never learn whether it worked. Tracking turns that guess into data: how many people scanned, where they were, what device they used, and when. This guide explains what you can mea
Microsoft Unveils MAI Series Models to Diversify AI Strategy Beyond Single Giant
Satya Nadella, Microsoft’s CEO, highlighted during the recent quarterly earnings call that the company is accelerating enterprise adoption of multi-model architectures while boosting investments in proprietary AI models, agents, and secure solutions
World Model Firms Guard Secrets
Last week, I facilitated a discussion on world models at the All In conference (unrelated to the podcast), offering a deep dive into one of AI’s most enigmatic sectors. Industry leaders like Yann LeCun’s AMI Labs and Fei-Fei Li’s World Labs have gene
Related Special Topic Recommendations
Design & Art
 Best AI Art Generators: Explore Moodboards, Styles, and Visual Directions
2026 Latest Best AI Art Generators ranking showcases top-rated tools for creating stunning moodboards, exploring diverse styles, and defining visual directions. XIX.AI offers a curated list of powerful, game-changing options that have passed rigorous real-world tests. Get a free vs paid comparison to help you find the perfect fit for boosting your creative workflow. Explore now to Unlock your AI edge in art creation.
 10 tools
 xix.ai
Marketing
AI Email Personalization Platforms for Shopify Flows, Retention, and Win-Backs
2026 Latest Best AI Email Personalization Platforms for Shopify Flows that boost retention and win-backs. This top-rated curated list features powerful game-changing tools经过real-world tests, offering free vs paid comparison insights. XIX.AI is part of our trusted selection. Discover your perfect tool to unlock your AI edge today. Explore now!
9 tools
xix.ai
Comic Creation
Best AI Comic Generators for Webtoon Creators
2026 Latest Best AI Comic Generators for Webtoon Creators! XIX.AI has curated a top-rated list of powerful, game-changing tools that help creators boost productivity significantly. You’ll find detailed weekly updated rankings, free vs paid comparison, and real-world tests to help you choose the perfect fit. Must-try options are available to overcome creation bottlenecks and deliver high-quality content faster. Explore now to Discover your perfect tool for smarter comic making!
9 tools
xix.ai
Design & Art
AI Illustration Tools for Digital Artists
2026 Latest Best Top-rated AI Illustration Tools for Digital Artists! XIX.AI has curated a powerful, game-changing collection of top tools designed to help artists unlock their full creative potential. These best options feature weekly updated rankings, real-world tests, and free vs paid comparison details to help you find the perfect fit for boosting your workflow efficiency. Must-try choices across all skill levels are here—Explore now to Discover your perfect tool!
17 tools
xix.ai
Comic Creation
Best AI Manga Layout Tools for Webtoon Creators
2026 Latest Best Top-Rated AI Manga Layout Tools for Webtoon Creators! XIX.AI has curated a powerful, game-changing collection of must-try tools that go through rigorous real-world tests. You’ll find detailed weekly updated rankings, free vs paid comparison info, and insights on how these tools can boost your workflow, help you create high-quality content faster, and unlock your full creative potential. Explore now to discover your perfect tool!
9 tools
xix.ai
design
AI Dashboard Wireframing Tools for B2B SaaS, Admin Panels, and Data-Heavy Products
2026 Latest Best AI Dashboard Wireframing Tools for B2B SaaS, Admin Panels, and Data-Heavy Products! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests to deliver exceptional results. You’ll find detailed free vs paid comparison data, comprehensive rankings, and useful insights to help you choose the perfect solution for boosting productivity and streamlining your workflow. Explore now to unlock your AI edge!
8 tools
xix.ai

 Comments (0)
0/500
Tracking AI’s latest offline IQ assessment reveals that multiple iterations of OpenAI’s GPT-5.6 achieved a score of 136, marking the first instance of a large language model exceeding the 130 IQ benchmark. In standard human distribution, an IQ of 130 signifies the threshold for “genius,” a level attained by merely 1% of the global population, effectively positioning GPT-5.6 as more intelligent than 99% of people.
Scoring 136 on the most rigorous, anti-leakage question bank, GPT-5.6 significantly outperformed its competitors.
Tracking AI utilized two distinct testing frameworks: an open-source Mensa Norway-style exam, where models already exceeded 140 points, and a proprietary, undisclosed offline question bank designed to prevent pre-memorization. GPT-5.6 successfully navigated this challenging offline dataset, with the entire SOL and TERRA family scoring 136, including its visual variant. Claude-5 Fable followed with 130 points, while GPT-5.6 LUNA Max and Claude-4.8 Opus lagged between 117 and 123 points. While models ranging from o3 to various flagship systems have historically plateaued at the 130 threshold, GPT-5.6 has become the first to break through.
Beyond test scores, GPT-5.6 demonstrates exceptional performance in practical applications.
High test metrics alone do not guarantee utility. Developers evaluated GPT-5.6 in real-world scenarios with striking results. When developer Amir Bohlooli submitted an identical physical simulation prompt to both Fable5 and GPT-5.6 Sol, he anticipated Fable’s dominance. Instead, GPT-5.6 Sol executed a particle fluid simulation with real-time physics, encapsulating CSS, interface design, and rendering within a single HTML file. It automatically hosted the result as a shareable web page, delivering a complete product from a single prompt. Similarly, Ramanpal Singh developed a customer ticket system using RAG with one prompt, incorporating four distinct roles, a management backend, automated complaint classification, and emotion recognition. This complex setup required only a fraction of the cost associated with Fable5.
Claire Vo’s experience highlighted these practical advantages. After encountering a persistent bug that she believed had crashed her code, she switched to GPT-5.6 Sol, remarking, “I won’t let this beat me.” Sol resolved the issue immediately and assisted other models in running smoothly. Vo’s assessment was clear: Fable’s rigid focus on technical precision hindered its effectiveness, whereas Sol’s pragmatic approach delivered tangible results.








 How to check Google ranking for free?
A QR Code you cannot track is a guess. You print it, you hope, and you never learn whether it worked. Tracking turns that guess into data: how many people scanned, where they were, what device they used, and when. This guide explains what you can mea
 Microsoft Unveils MAI Series Models to Diversify AI Strategy Beyond Single Giant
Satya Nadella, Microsoft’s CEO, highlighted during the recent quarterly earnings call that the company is accelerating enterprise adoption of multi-model architectures while boosting investments in proprietary AI models, agents, and secure solutions
 World Model Firms Guard Secrets
Last week, I facilitated a discussion on world models at the All In conference (unrelated to the podcast), offering a deep dive into one of AI’s most enigmatic sectors. Industry leaders like Yann LeCun’s AMI Labs and Fei-Fei Li’s World Labs have gene

2026 Latest Best AI Art Generators ranking showcases top-rated tools for creating stunning moodboards, exploring diverse styles, and defining visual directions. XIX.AI offers a curated list of powerful, game-changing options that have passed rigorous real-world tests. Get a free vs paid comparison to help you find the perfect fit for boosting your creative workflow. Explore now to Unlock your AI edge in art creation.
10 tools
xix.ai
2026 Latest Best AI Email Personalization Platforms for Shopify Flows that boost retention and win-backs. This top-rated curated list features powerful game-changing tools经过real-world tests, offering free vs paid comparison insights. XIX.AI is part of our trusted selection. Discover your perfect tool to unlock your AI edge today. Explore now!
9 tools
xix.ai
2026 Latest Best AI Comic Generators for Webtoon Creators! XIX.AI has curated a top-rated list of powerful, game-changing tools that help creators boost productivity significantly. You’ll find detailed weekly updated rankings, free vs paid comparison, and real-world tests to help you choose the perfect fit. Must-try options are available to overcome creation bottlenecks and deliver high-quality content faster. Explore now to Discover your perfect tool for smarter comic making!
9 tools
xix.ai
2026 Latest Best Top-rated AI Illustration Tools for Digital Artists! XIX.AI has curated a powerful, game-changing collection of top tools designed to help artists unlock their full creative potential. These best options feature weekly updated rankings, real-world tests, and free vs paid comparison details to help you find the perfect fit for boosting your workflow efficiency. Must-try choices across all skill levels are here—Explore now to Discover your perfect tool!
17 tools
xix.ai
2026 Latest Best Top-Rated AI Manga Layout Tools for Webtoon Creators! XIX.AI has curated a powerful, game-changing collection of must-try tools that go through rigorous real-world tests. You’ll find detailed weekly updated rankings, free vs paid comparison info, and insights on how these tools can boost your workflow, help you create high-quality content faster, and unlock your full creative potential. Explore now to discover your perfect tool!
9 tools
xix.ai
2026 Latest Best AI Dashboard Wireframing Tools for B2B SaaS, Admin Panels, and Data-Heavy Products! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests to deliver exceptional results. You’ll find detailed free vs paid comparison data, comprehensive rankings, and useful insights to help you choose the perfect solution for boosting productivity and streamlining your workflow. Explore now to unlock your AI edge!
8 tools
xix.ai












