


 Home
DeepSeek V4.1 Flash Launches With Native Multimodal Vision, Outperforming Pro Version as Prices Fall
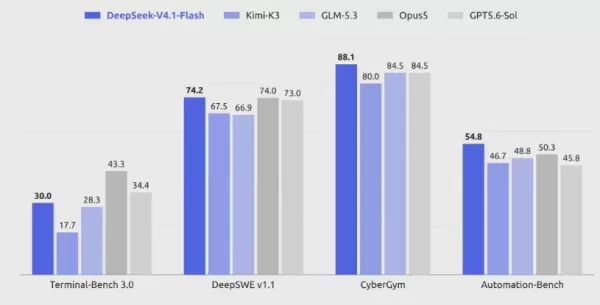
DeepSeek has officially launched the smallest model in its latest architecture series today: DeepSeek V4.1Flash. Designed as a lightweight model with native multi-modal visual understanding, it aims to deliver higher performance, faster inference, greater throughput, and scalability to larger parameter sizes.
At its core, DeepSeek V4.1Flash utilizes a 552B parameter Mixture of Experts (MoE) architecture, featuring an innovative Causal-Encoder-Decoder structure. Its asymmetric design results in only 8B input activations and 16B output activations, significantly lowering costs compared to similarly sized models. Enhanced by a new pre-training approach and large-scale reinforcement learning, this model outperforms flagship models like DeepSeek V4Pro across various benchmarks.
Regarding efficiency and cost control, the new model drastically reduces KV Cache size. Compared to its predecessor, V4.1Flash requires only 1/4 of the high-bandwidth memory (HBM) and 1/8 of the solid-state drive (SSD) capacity. This compression is particularly beneficial for Agent scenarios, where context storage and cache hit costs are high, significantly lowering operational expenses. Statistics show the KV Cache has shrunk to 1/437 of the initial model's size.
With the new model's release, DeepSeek has updated its product lineup and billing strategy. DeepSeek V4.1Flash is now available via the DeepSeek API under the model name deepseek-flash. Previous versions, V4Flash and V4Flash Vision Exp, have been discontinued, with old names (deepseek-v4-flash and deepseek-v4-flash-vision-exp) temporarily routing to V4.1Flash. Since V4.1Flash surpasses V4Pro in performance, cost, speed, and usage time, the company plans to phase out V4Pro: after 12:00 on September 14, 2026, requests to deepseek-v4-pro will be routed to V4.1Flash and billed at its rate. Official partners like WorkBuddy, CodeBuddy, and Tencent's OpenCode have already integrated this model.
Related article
 Aliyun Qwen Open Platform Launches, Enabling AI on Phones, PCs, and Glasses Across Renting, Shipping, and More
As AI applications expand rapidly, Qwen has significantly upgraded its ecosystem. Launched on August 10, the Qwen Open Platform now provides broad access for mobile phones, PCs, and AI glasses to ecosystem partners and developers.In its initial phase
Dou Bao Set to Launch Paid Tiers in Mid-June, E-Commerce Push Planned for Q3
Douyin, ByteDance’s flagship large model application, is set to roll out paid content features by late June, with updates scheduled for the Force conference. This move marks a major milestone in monetizing China’s largest large model.Reports indicate
CCTV Exposes AI Dating Scam Targeting Middle-Aged and Older Women, 28 Arrested
Recent reports from CCTV News highlight a new wave of AI-driven dating scams targeting middle-aged and elderly women. Criminals are leveraging AI-generated personas to lure victims into financial fraud. Authorities in Chengdu, Sichuan, recently buste
Related Special Topic Recommendations
design
 AI Dashboard Wireframing Tools for B2B SaaS, Admin Panels, and Data-Heavy Products
2026 Latest Best AI Dashboard Wireframing Tools for B2B SaaS, Admin Panels, and Data-Heavy Products! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests to deliver exceptional results. You’ll find detailed free vs paid comparison data, comprehensive rankings, and useful insights to help you choose the perfect solution for boosting productivity and streamlining your workflow. Explore now to unlock your AI edge!
 8 tools
 xix.ai
Health & Wellness
AI Sleep Insight Tools for Better Recovery Habits
2026 Latest Best AI Sleep Insight Tools for Better Recovery Habits are here on XIX.AI! This curated list features top-rated, powerful solutions that offer real-world tests and weekly updated rankings. You’ll find a free vs paid comparison to help you choose the must-try option that boosts productivity and helps you build consistent recovery habits. Explore now to unlock your AI edge!
7 tools
xix.ai
Academic Research
Best AI Research Assistants: Speed Up Literature Review and Citation Tracking
2026 Latest Best Top-rated AI Research Assistants for Streamlining Literature Reviews and Citation Tracking. XIX.AI curates a powerful game-changing selection, backed by rigorous real-world tests and weekly updated rankings. You’ll find must-try options that boost productivity significantly, helping you overcome research bottlenecks faster. Explore now to discover your perfect tool and unlock your AI edge in academic work.
10 tools
xix.ai
Health & Wellness
Best AI Meal Planning Apps: Build Smarter Nutrition Routines
2026 Latest Best Top-Rated AI meal planning apps for building smarter nutrition routines. This curated list includes powerful tools that offer real-world tests and weekly updated rankings. You can find a free vs paid comparison to help you choose the must-try solution that boosts productivity and helps you create balanced meals effortlessly. Explore now at XIX.AI to unlock your AI edge.
12 tools
xix.ai
SEO
Top AI SEO Auditors for Small Teams: Fix Issues Before Rankings Slip
2026 Latest Top-rated AI SEO Auditors for Small Teams are here on XIX.AI! Our curated list features powerful tools that help you fix hidden issues fast, boost your rankings, and save time. Get a free vs paid comparison along with real-world tests to choose the best option for your needs. Explore now to Discover your perfect tool and Unlock your AI edge.
11 tools
xix.ai
Text-to-speech
AI Podcast Voice Cloning Tools for Long-Form Narration
2026 Latest Best Top-Rated AI Podcast Voice Cloning Tools for Long-Form Narration are here on XIX.AI! This curated list features powerful, game-changing solutions that deliver professional-quality audio with zero effort. We conduct real-world tests and provide a free vs paid comparison along with weekly updated rankings to help you find the must-try tool that boosts your productivity significantly. Explore now to unlock your AI edge!
10 tools
xix.ai

 Comments (0)
0/500
DeepSeek has officially launched the smallest model in its latest architecture series today: DeepSeek V4.1Flash. Designed as a lightweight model with native multi-modal visual understanding, it aims to deliver higher performance, faster inference, greater throughput, and scalability to larger parameter sizes.
At its core, DeepSeek V4.1Flash utilizes a 552B parameter Mixture of Experts (MoE) architecture, featuring an innovative Causal-Encoder-Decoder structure. Its asymmetric design results in only 8B input activations and 16B output activations, significantly lowering costs compared to similarly sized models. Enhanced by a new pre-training approach and large-scale reinforcement learning, this model outperforms flagship models like DeepSeek V4Pro across various benchmarks.
Regarding efficiency and cost control, the new model drastically reduces KV Cache size. Compared to its predecessor, V4.1Flash requires only 1/4 of the high-bandwidth memory (HBM) and 1/8 of the solid-state drive (SSD) capacity. This compression is particularly beneficial for Agent scenarios, where context storage and cache hit costs are high, significantly lowering operational expenses. Statistics show the KV Cache has shrunk to 1/437 of the initial model's size.
With the new model's release, DeepSeek has updated its product lineup and billing strategy. DeepSeek V4.1Flash is now available via the DeepSeek API under the model name deepseek-flash. Previous versions, V4Flash and V4Flash Vision Exp, have been discontinued, with old names (deepseek-v4-flash and deepseek-v4-flash-vision-exp) temporarily routing to V4.1Flash. Since V4.1Flash surpasses V4Pro in performance, cost, speed, and usage time, the company plans to phase out V4Pro: after 12:00 on September 14, 2026, requests to deepseek-v4-pro will be routed to V4.1Flash and billed at its rate. Official partners like WorkBuddy, CodeBuddy, and Tencent's OpenCode have already integrated this model.








 Aliyun Qwen Open Platform Launches, Enabling AI on Phones, PCs, and Glasses Across Renting, Shipping, and More
As AI applications expand rapidly, Qwen has significantly upgraded its ecosystem. Launched on August 10, the Qwen Open Platform now provides broad access for mobile phones, PCs, and AI glasses to ecosystem partners and developers.In its initial phase
 Dou Bao Set to Launch Paid Tiers in Mid-June, E-Commerce Push Planned for Q3
Douyin, ByteDance’s flagship large model application, is set to roll out paid content features by late June, with updates scheduled for the Force conference. This move marks a major milestone in monetizing China’s largest large model.Reports indicate
 CCTV Exposes AI Dating Scam Targeting Middle-Aged and Older Women, 28 Arrested
Recent reports from CCTV News highlight a new wave of AI-driven dating scams targeting middle-aged and elderly women. Criminals are leveraging AI-generated personas to lure victims into financial fraud. Authorities in Chengdu, Sichuan, recently buste
2026 Latest Best AI Dashboard Wireframing Tools for B2B SaaS, Admin Panels, and Data-Heavy Products! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests to deliver exceptional results. You’ll find detailed free vs paid comparison data, comprehensive rankings, and useful insights to help you choose the perfect solution for boosting productivity and streamlining your workflow. Explore now to unlock your AI edge!
8 tools
xix.ai
2026 Latest Best AI Sleep Insight Tools for Better Recovery Habits are here on XIX.AI! This curated list features top-rated, powerful solutions that offer real-world tests and weekly updated rankings. You’ll find a free vs paid comparison to help you choose the must-try option that boosts productivity and helps you build consistent recovery habits. Explore now to unlock your AI edge!
7 tools
xix.ai
2026 Latest Best Top-rated AI Research Assistants for Streamlining Literature Reviews and Citation Tracking. XIX.AI curates a powerful game-changing selection, backed by rigorous real-world tests and weekly updated rankings. You’ll find must-try options that boost productivity significantly, helping you overcome research bottlenecks faster. Explore now to discover your perfect tool and unlock your AI edge in academic work.
10 tools
xix.ai
2026 Latest Best Top-Rated AI meal planning apps for building smarter nutrition routines. This curated list includes powerful tools that offer real-world tests and weekly updated rankings. You can find a free vs paid comparison to help you choose the must-try solution that boosts productivity and helps you create balanced meals effortlessly. Explore now at XIX.AI to unlock your AI edge.
12 tools
xix.ai
2026 Latest Top-rated AI SEO Auditors for Small Teams are here on XIX.AI! Our curated list features powerful tools that help you fix hidden issues fast, boost your rankings, and save time. Get a free vs paid comparison along with real-world tests to choose the best option for your needs. Explore now to Discover your perfect tool and Unlock your AI edge.
11 tools
xix.ai
2026 Latest Best Top-Rated AI Podcast Voice Cloning Tools for Long-Form Narration are here on XIX.AI! This curated list features powerful, game-changing solutions that deliver professional-quality audio with zero effort. We conduct real-world tests and provide a free vs paid comparison along with weekly updated rankings to help you find the must-try tool that boosts your productivity significantly. Explore now to unlock your AI edge!
10 tools
xix.ai












