


 Home
New Benchmark Questions Workplace Readiness of AI Agents
Nearly two years ago, Microsoft CEO Satya Nadella forecasted that AI would reshape knowledge work — the domain of lawyers, investment bankers, librarians, accountants, IT professionals, and similar white-collar roles.
However, despite significant advancements in foundation models, a transformation in knowledge work has been slow to materialize. While models excel at deep research and agentic planning, most white-collar professions have seen relatively little disruption for reasons that remain unclear.
This stands as one of AI's great puzzles. New research from training-data leader Mercor is now providing crucial insights.
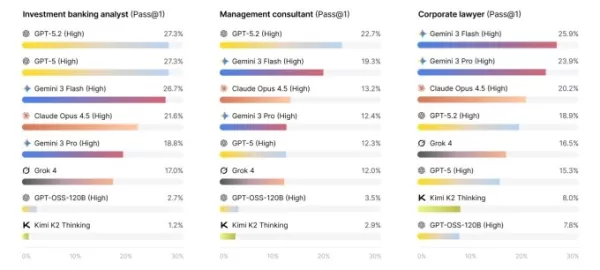
The study evaluates how top AI models handle genuine white-collar tasks from consulting, investment banking, and law. This led to the creation of the APEX-Agents benchmark — and currently, every AI lab is failing. When presented with queries from real professionals, even the best models correctly answered fewer than a quarter. Most often, they returned an incorrect response or none at all.
According to Mercor CEO Brendan Foody, who contributed to the research, the models' primary weakness was synthesizing information across multiple domains — a core component of human knowledge work.
"A key innovation in this benchmark is that we constructed a complete environment modeled on real professional services," Foody explained to TechCrunch. "Our work doesn't involve a single person handing us all the context in one place. In reality, you operate across Slack, Google Drive, and various other tools." For many agentic AI models, that type of cross-domain reasoning remains inconsistent.
Screenshot The test scenarios were sourced from actual professionals on Mercor's expert marketplace, who designed the queries and defined the criteria for a successful answer. Reviewing the publicly available questions on Hugging Face reveals the complexity of these tasks.
Techcrunch event Disrupt 2026 Tickets: One-time offer
Tickets are now available! Save up to $680 during this limited-time offer and be among the first 500 registrants to receive 50% off a +1 pass. TechCrunch Disrupt gathers top leaders from Google Cloud, Netflix, Microsoft, Box, a16z, Hugging Face, and more for 250+ sessions aimed at fueling growth and sharpening your competitive edge. Connect with hundreds of innovative startups and participate in curated networking that drives deals, insights, and inspiration.
Disrupt 2026 Tickets: One-time offer
Tickets are now available! Save up to $680 during this limited-time offer and be among the first 500 registrants to receive 50% off a +1 pass. TechCrunch Disrupt gathers top leaders from Google Cloud, Netflix, Microsoft, Box, a16z, Hugging Face, and more for 250+ sessions aimed at fueling growth and sharpening your competitive edge. Connect with hundreds of innovative startups and participate in curated networking that drives deals, insights, and inspiration.
San Francisco | October 13-15, 2026 REGISTER NOW One example from the "Law" section asks:
During the first 48 minutes of an EU production outage, Northstar's engineering team exported one or two bundled sets of EU production event logs containing personal data to a U.S. analytics vendor… According to Northstar's own policies, can it reasonably treat these one or two log exports as compliant with Article 49?
The correct answer is yes, but arriving at it requires a detailed analysis of both the company's internal policies and relevant EU privacy regulations.
Such a question could challenge even a knowledgeable human, but the researchers aimed to simulate real professional work. An LLM that can reliably answer these queries could potentially replace many practicing lawyers. "This is arguably the most significant economic topic today," Foody told TechCrunch. "The benchmark accurately reflects the actual work these professionals perform."
OpenAI previously attempted to gauge professional skills with its GDPval benchmark, but the APEX-Agents test differs meaningfully. While GDPval assesses broad general knowledge across many fields, APEX-Agents measures a system's capability to execute sustained tasks within a select few high-value professions. This makes it more challenging for models and more directly relevant to the potential for job automation.
Although no model is ready to step in as an investment banker, some clearly came closer than others. Gemini 3 Flash led the group with 24% one-shot accuracy, closely followed by GPT-5.2 at 23%. Opus 4.5, Gemini 3 Pro, and GPT-5 all scored around 18%.
While these initial results are underwhelming, the AI field has a track record of rapidly overcoming difficult benchmarks. With the APEX-Agents test now public, it poses an open challenge to AI labs confident they can improve — an outcome Foody fully anticipates in the coming months.
"The pace of improvement is remarkably fast," he told TechCrunch. "Currently, it's fair to compare the technology to an intern who gets it right a quarter of the time, but last year it was an intern who succeeded 5 or 10% of the time. That rate of year-over-year progress can create substantial impact very quickly."
Related article
 Ctrip Business Travel Unveils AI Ecosystem with 7 Industry Agents and 17 Core Capabilities
Ctrip Business Travel has officially unveiled the "Ctrip Business Travel AI Ecosystem," leveraging large language models to fundamentally restructure corporate travel management. This comprehensive ecosystem addresses four core scenarios: travel arra
Stripe to Acquire OpenRouter as AI Model Routing Gains Momentum
Stripe has agreed to acquire OpenRouter, an AI model-routing platform that gives developers access to hundreds of models through a single interface. The deal adds model selection and routing to Stripe’s existing work around AI usage and token-based b
Former OpenAI Researcher Barrett Zoph Returns to Google to Support Gemini Development
Barret Zoph, who previously abruptly left and joined OpenAI due to a disagreement with Thinking Machines Lab CEO Miriam Mularati, has once again changed employers. Alphabet's Google announced that Zoph will return as Vice President of Research, bring
Related Special Topic Recommendations
Design & Art
 Top AI Illustration Tools: Create Editorial Scenes and Cover Art Faster
2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
 10 tools
 xix.ai
Education and Learning
Top AI Tutors for Exam Prep: Practice Math, Science, and English
2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai
Finance
AI Budget Planning Tools for Personal Money Management
2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai
Health & Wellness
AI Sleep Tracking Assistants: Improve Recovery with Better Bedtime Habits
2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai
Data Analysis
AI SQL Copilots for Product and Revenue Analytics
2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai
Education and Learning
Best AI Homework Helpers That Teach: Learn Concepts, Not Just Answers
2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai

 Comments (0)
0/500
Nearly two years ago, Microsoft CEO Satya Nadella forecasted that AI would reshape knowledge work — the domain of lawyers, investment bankers, librarians, accountants, IT professionals, and similar white-collar roles.
However, despite significant advancements in foundation models, a transformation in knowledge work has been slow to materialize. While models excel at deep research and agentic planning, most white-collar professions have seen relatively little disruption for reasons that remain unclear.
This stands as one of AI's great puzzles. New research from training-data leader Mercor is now providing crucial insights.
The study evaluates how top AI models handle genuine white-collar tasks from consulting, investment banking, and law. This led to the creation of the APEX-Agents benchmark — and currently, every AI lab is failing. When presented with queries from real professionals, even the best models correctly answered fewer than a quarter. Most often, they returned an incorrect response or none at all.
According to Mercor CEO Brendan Foody, who contributed to the research, the models' primary weakness was synthesizing information across multiple domains — a core component of human knowledge work.
"A key innovation in this benchmark is that we constructed a complete environment modeled on real professional services," Foody explained to TechCrunch. "Our work doesn't involve a single person handing us all the context in one place. In reality, you operate across Slack, Google Drive, and various other tools." For many agentic AI models, that type of cross-domain reasoning remains inconsistent.
The test scenarios were sourced from actual professionals on Mercor's expert marketplace, who designed the queries and defined the criteria for a successful answer. Reviewing the publicly available questions on Hugging Face reveals the complexity of these tasks.
Techcrunch eventDisrupt 2026 Tickets: One-time offer
Tickets are now available! Save up to $680 during this limited-time offer and be among the first 500 registrants to receive 50% off a +1 pass. TechCrunch Disrupt gathers top leaders from Google Cloud, Netflix, Microsoft, Box, a16z, Hugging Face, and more for 250+ sessions aimed at fueling growth and sharpening your competitive edge. Connect with hundreds of innovative startups and participate in curated networking that drives deals, insights, and inspiration.
Disrupt 2026 Tickets: One-time offer
Tickets are now available! Save up to $680 during this limited-time offer and be among the first 500 registrants to receive 50% off a +1 pass. TechCrunch Disrupt gathers top leaders from Google Cloud, Netflix, Microsoft, Box, a16z, Hugging Face, and more for 250+ sessions aimed at fueling growth and sharpening your competitive edge. Connect with hundreds of innovative startups and participate in curated networking that drives deals, insights, and inspiration.
San Francisco | October 13-15, 2026 REGISTER NOWOne example from the "Law" section asks:
During the first 48 minutes of an EU production outage, Northstar's engineering team exported one or two bundled sets of EU production event logs containing personal data to a U.S. analytics vendor… According to Northstar's own policies, can it reasonably treat these one or two log exports as compliant with Article 49?
The correct answer is yes, but arriving at it requires a detailed analysis of both the company's internal policies and relevant EU privacy regulations.
Such a question could challenge even a knowledgeable human, but the researchers aimed to simulate real professional work. An LLM that can reliably answer these queries could potentially replace many practicing lawyers. "This is arguably the most significant economic topic today," Foody told TechCrunch. "The benchmark accurately reflects the actual work these professionals perform."
OpenAI previously attempted to gauge professional skills with its GDPval benchmark, but the APEX-Agents test differs meaningfully. While GDPval assesses broad general knowledge across many fields, APEX-Agents measures a system's capability to execute sustained tasks within a select few high-value professions. This makes it more challenging for models and more directly relevant to the potential for job automation.
Although no model is ready to step in as an investment banker, some clearly came closer than others. Gemini 3 Flash led the group with 24% one-shot accuracy, closely followed by GPT-5.2 at 23%. Opus 4.5, Gemini 3 Pro, and GPT-5 all scored around 18%.
While these initial results are underwhelming, the AI field has a track record of rapidly overcoming difficult benchmarks. With the APEX-Agents test now public, it poses an open challenge to AI labs confident they can improve — an outcome Foody fully anticipates in the coming months.
"The pace of improvement is remarkably fast," he told TechCrunch. "Currently, it's fair to compare the technology to an intern who gets it right a quarter of the time, but last year it was an intern who succeeded 5 or 10% of the time. That rate of year-over-year progress can create substantial impact very quickly."








 Ctrip Business Travel Unveils AI Ecosystem with 7 Industry Agents and 17 Core Capabilities
Ctrip Business Travel has officially unveiled the "Ctrip Business Travel AI Ecosystem," leveraging large language models to fundamentally restructure corporate travel management. This comprehensive ecosystem addresses four core scenarios: travel arra
 Stripe to Acquire OpenRouter as AI Model Routing Gains Momentum
Stripe has agreed to acquire OpenRouter, an AI model-routing platform that gives developers access to hundreds of models through a single interface. The deal adds model selection and routing to Stripe’s existing work around AI usage and token-based b
 Former OpenAI Researcher Barrett Zoph Returns to Google to Support Gemini Development
Barret Zoph, who previously abruptly left and joined OpenAI due to a disagreement with Thinking Machines Lab CEO Miriam Mularati, has once again changed employers. Alphabet's Google announced that Zoph will return as Vice President of Research, bring

2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
10 tools
xix.ai

2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai

2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai

2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai












