
option
Home
Flash News
Content
AlbertKing
AlbertKing
July 21, 2026

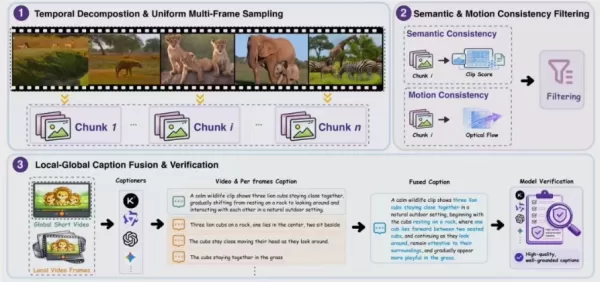
XPeng Group launched TuringViT, an efficient visual encoder that restructures architecture, data, and training for low-cost SOTA visual transformers. It supports intelligent driving, cockpits, and humanoid robots. Using only 0.85B image-text pairs, it achieves 83.6% zero-shot accuracy on six benchmarks, outperforming models trained on 10B data, with 3x inference throughput at high resolutions.
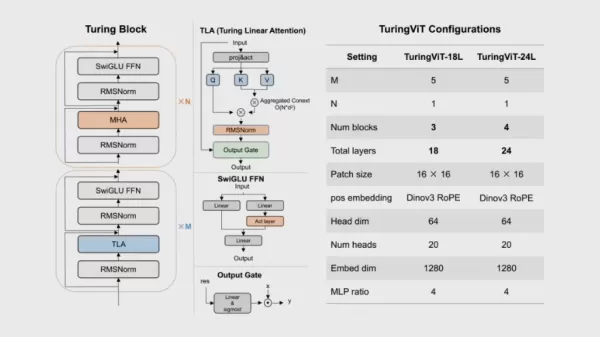
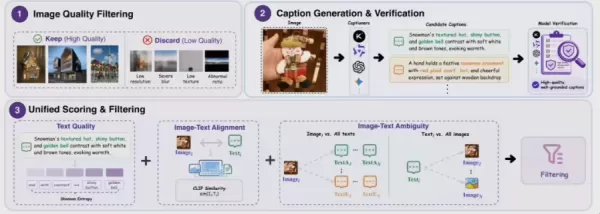
XPeng Group launched TuringViT, an efficient visual encoder that restructures architecture, data, and training for low-cost SOTA visual transformers. It supports intelligent driving, cockpits, and humanoid robots. Using only 0.85B image-text pairs, it achieves 83.6% zero-shot accuracy on six benchmarks, outperforming models trained on 10B data, with 3x inference throughput at high resolutions. XPeng Group launched TuringViT, an efficient visual encoder that restructures architecture, data, and training for low-cost SOTA visual transformers. It supports intelligent driving, cockpits, and humanoid robots. Using only 0.85B image-text pairs, it achieves 83.6% zero-shot accuracy on six benchmarks, outperforming models trained on 10B data, with 3x inference throughput at high resolutions. XPeng Group launched TuringViT, an efficient visual encoder that restructures architecture, data, and training for low-cost SOTA visual transformers. It supports intelligent driving, cockpits, and humanoid robots. Using only 0.85B image-text pairs, it achieves 83.6% zero-shot accuracy on six benchmarks, outperforming models trained on 10B data, with 3x inference throughput at high resolutions.
Comments (0)
0/300
OR