


 Home
Senspeech X2.5 Twin Stars: First Million-Token Context on the Edge, Fully Trained with Domestic Computing Power
On September 1st, iFLYTEK’s wholly-owned subsidiary, Ciyuan Xinghuo, officially launched and open-sourced two edge-side general large models: Xinghuo X2.5-4B and Xinghuo X2.5-1.7B. These models are the first of their kind to natively support a context length of up to 1 million Tokens, with full access to model weights, code repositories, and deployment documentation.
Million-level Context Support, Small Models Can "Read the Whole Book"
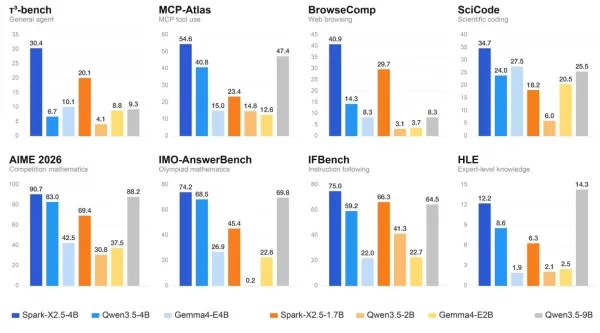
Both models utilize a hybrid attention architecture, optimized for core capabilities such as agents, code, mathematics, and instruction following, delivering comprehensive performance that leads among industry-class open-source models of similar size.
Regarding context capability, Xinghuo X2.5-4B and Xinghuo X2.5-1.7B are trained on high-quality data at the level of trillions of Tokens, covering scenarios such as long documents and technical materials. They natively support a context window of 1 million Tokens, allowing them to receive and understand larger-scale information at once.
For example, in product after-sales service: users can import the complete after-sales manual into Xinghuo X2.5-4B. The model first sorts out after-sales rules under different scenarios and marks corresponding chapters. When asked "Whether a device failure within 10 days of purchase and using third-party consumables qualifies for a replacement?", it can provide a comprehensive judgment by linking regulations on returns, fault handling, and exceptions across chapters. Even if new conditions such as remote areas or devices with family maps are added later, the model can maintain the previous context and continue to provide advice by combining logistics, data erasure, and cost-bearing rules.
The long context solves the issue of "whether information can be fully viewed," while the agent and tool calling capabilities solve "whether actions can be taken after viewing." Xinghuo X2.5 edge-side models provide localized intelligent capabilities for scenarios such as personal office, code development, smart hardware, and robotics. In code development scenarios, Xinghuo X2.5-4B can match cloud models with parameters 2 to 3 times larger in tasks such as algorithm implementation, code completion, and generation; on the Domux smart home test set, the end-to-end execution accuracy of Xinghuo X2.5-1.7B for control instructions reaches 90.3%, with an average response time of only 0.85 seconds; in robotics scenarios, both models can be deployed on robot bodies or edge devices, supporting tasks such as operation control, target tracking, and navigation decision-making, reducing dependency on cloud connections and fixed pre-set programs.
Entirely Domestic Computing Power Training, Instant Download and Experience
Xinghuo X2.5-4B and Xinghuo X2.5-1.7B were trained entirely on domestic computing platforms, using about 20 trillion diverse tokens of data for pre-training, and continuously improving performance through high-quality supervised fine-tuning and reinforcement learning.
In terms of deployment, both models support hardware platforms including NVIDIA, Huawei, Hai Guang, and Hemo, and are compatible with mainstream inference frameworks such as vLLM, SGLang, and llama.cpp. They can be quickly deployed through tools like Ollama and LM Studio, and support incremental training using LLaMA-Factory. Starting from today, model weights have been made available on platforms such as Hugging Face and GitHub, and corresponding model APIs have been launched on iFLYTEK's Starry MaaS platform, free of charge for a limited time. On September 7th, iFLYTEK will officially release the next-generation flagship general large model, Xinghuo X2.5, further upgrading core capabilities such as code and agents.
Related article
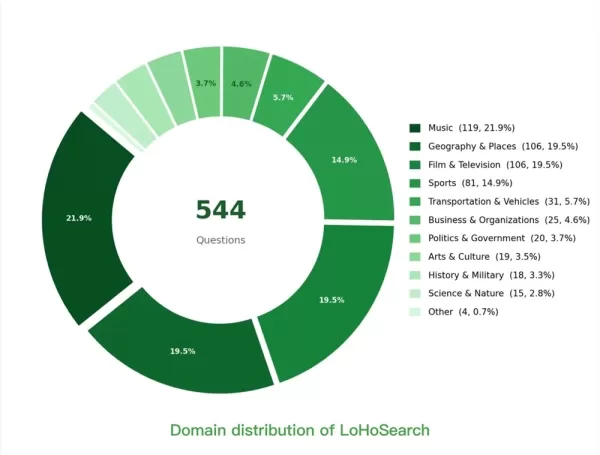
 Meitun LongCat Launches LoHoSearch as BrowseComp Scores Drop Below 30%
Search agent capabilities have been largely defined by BrowseComp over the last year. Yet, this benchmark is losing its relevance — it drove model performance from 30% to 90% in just ten months, and its value is rapidly diminishing. On July 17, Meitu
MiniMax Unveils M3, a Domestic AI Large Model That Surpasses GPT-5.5
China’s AI sector has witnessed a major technological leap with the official launch of Xiyu Technology’s latest large language model, MiniMax M3. This advanced system combines state-of-the-art coding proficiency with support for an ultra-long context
India mandates caller-ID apps to share spam data with telecom operators
India has expanded its anti-spam regulations to mandate that caller-ID and call-management applications share user spam reports with telecom operators, a move that has led Truecaller, a prominent spam-blocking app provider, to label the policy as ant
Related Special Topic Recommendations
Music composition
 AI Songwriting Tools for Lyrics and Melody Ideas
2026 Latest Best Top-Rated AI Songwriting Tools for Lyrics and Melody Ideas are here on XIX.AI! This curated collection features powerful, game-changing options that go through rigorous real-world tests to deliver accurate lyric and melody suggestions. Get a free vs paid comparison, see detailed rankings, and discover must-try tools that can boost your creative workflow significantly. Explore now to find the perfect fit for your needs!
 8 tools
 xix.ai
Health & Wellness
ChatGPT Meal Planning Apps for Macro Tracking, Grocery Lists, and Weekly Prep
2026 Latest Best ChatGPT Meal Planning Apps Top-rated must-try curated powerful game-changing tools for macro tracking grocery lists and weekly prep. XIX.AI delivers weekly updated rankings based on real-world tests, including free vs paid comparison details. Discover your perfect tool to boost productivity and unlock your AI edge today. Explore now!
9 tools
xix.ai
Video creation
AI Video Script Tools for Short Form Content
2026 Latest Best Top-Rated AI Video Script Tools for Short Form Content! XIX.AI has curated a powerful, game-changing collection of must-try tools that go through rigorous real-world tests. You’ll find detailed weekly updated rankings, free vs paid comparison info, and insights to help you boost productivity and unlock your AI edge in creating high-quality short form content. Explore now to discover your perfect tool!
10 tools
xix.ai
Comic Creation
AI Comic Panel Tools for Storyboard Style Narratives
2026 Latest Best AI Comic Panel Tools for Storyboard Style Narratives! This curated top-rated collection features powerful game-changing solutions that help creators boost writing efficiency and overcome creation bottlenecks. You’ll find detailed free vs paid comparison, real-world tests, and official rankings to guide your pick. XIX.AI offers expert insights too. Explore now to Discover your perfect tool for bringing vivid stories to life! 238 characters
9 tools
xix.ai
Video creation
Best AI Video Generation Tools for Short Content
2026 Latest Best Top-rated AI Video Generation Tools for Short Content are here on XIX.AI’s curated collection. These powerful game-changing tools have undergone rigorous real-world tests, featuring a comprehensive free vs paid comparison and detailed rankings to help you find the perfect option. Whether you need to create high-quality short videos fast or boost your productivity across various tasks, these must-try solutions deliver outstanding results. Explore now to discover your ideal tool and unlock your AI edge.
9 tools
xix.ai
Design & Art
Best AI Art Generators: Explore Moodboards, Styles, and Visual Directions
2026 Latest Best AI Art Generators ranking showcases top-rated tools for creating stunning moodboards, exploring diverse styles, and defining visual directions. XIX.AI offers a curated list of powerful, game-changing options that have passed rigorous real-world tests. Get a free vs paid comparison to help you find the perfect fit for boosting your creative workflow. Explore now to Unlock your AI edge in art creation.
10 tools
xix.ai

 Comments (0)
0/500
On September 1st, iFLYTEK’s wholly-owned subsidiary, Ciyuan Xinghuo, officially launched and open-sourced two edge-side general large models: Xinghuo X2.5-4B and Xinghuo X2.5-1.7B. These models are the first of their kind to natively support a context length of up to 1 million Tokens, with full access to model weights, code repositories, and deployment documentation.
Million-level Context Support, Small Models Can "Read the Whole Book"
Both models utilize a hybrid attention architecture, optimized for core capabilities such as agents, code, mathematics, and instruction following, delivering comprehensive performance that leads among industry-class open-source models of similar size.
Regarding context capability, Xinghuo X2.5-4B and Xinghuo X2.5-1.7B are trained on high-quality data at the level of trillions of Tokens, covering scenarios such as long documents and technical materials. They natively support a context window of 1 million Tokens, allowing them to receive and understand larger-scale information at once.
For example, in product after-sales service: users can import the complete after-sales manual into Xinghuo X2.5-4B. The model first sorts out after-sales rules under different scenarios and marks corresponding chapters. When asked "Whether a device failure within 10 days of purchase and using third-party consumables qualifies for a replacement?", it can provide a comprehensive judgment by linking regulations on returns, fault handling, and exceptions across chapters. Even if new conditions such as remote areas or devices with family maps are added later, the model can maintain the previous context and continue to provide advice by combining logistics, data erasure, and cost-bearing rules.
The long context solves the issue of "whether information can be fully viewed," while the agent and tool calling capabilities solve "whether actions can be taken after viewing." Xinghuo X2.5 edge-side models provide localized intelligent capabilities for scenarios such as personal office, code development, smart hardware, and robotics. In code development scenarios, Xinghuo X2.5-4B can match cloud models with parameters 2 to 3 times larger in tasks such as algorithm implementation, code completion, and generation; on the Domux smart home test set, the end-to-end execution accuracy of Xinghuo X2.5-1.7B for control instructions reaches 90.3%, with an average response time of only 0.85 seconds; in robotics scenarios, both models can be deployed on robot bodies or edge devices, supporting tasks such as operation control, target tracking, and navigation decision-making, reducing dependency on cloud connections and fixed pre-set programs.
Entirely Domestic Computing Power Training, Instant Download and Experience
Xinghuo X2.5-4B and Xinghuo X2.5-1.7B were trained entirely on domestic computing platforms, using about 20 trillion diverse tokens of data for pre-training, and continuously improving performance through high-quality supervised fine-tuning and reinforcement learning.
In terms of deployment, both models support hardware platforms including NVIDIA, Huawei, Hai Guang, and Hemo, and are compatible with mainstream inference frameworks such as vLLM, SGLang, and llama.cpp. They can be quickly deployed through tools like Ollama and LM Studio, and support incremental training using LLaMA-Factory. Starting from today, model weights have been made available on platforms such as Hugging Face and GitHub, and corresponding model APIs have been launched on iFLYTEK's Starry MaaS platform, free of charge for a limited time. On September 7th, iFLYTEK will officially release the next-generation flagship general large model, Xinghuo X2.5, further upgrading core capabilities such as code and agents.








 Meitun LongCat Launches LoHoSearch as BrowseComp Scores Drop Below 30%
Search agent capabilities have been largely defined by BrowseComp over the last year. Yet, this benchmark is losing its relevance — it drove model performance from 30% to 90% in just ten months, and its value is rapidly diminishing. On July 17, Meitu
 MiniMax Unveils M3, a Domestic AI Large Model That Surpasses GPT-5.5
China’s AI sector has witnessed a major technological leap with the official launch of Xiyu Technology’s latest large language model, MiniMax M3. This advanced system combines state-of-the-art coding proficiency with support for an ultra-long context
 India mandates caller-ID apps to share spam data with telecom operators
India has expanded its anti-spam regulations to mandate that caller-ID and call-management applications share user spam reports with telecom operators, a move that has led Truecaller, a prominent spam-blocking app provider, to label the policy as ant

2026 Latest Best Top-Rated AI Songwriting Tools for Lyrics and Melody Ideas are here on XIX.AI! This curated collection features powerful, game-changing options that go through rigorous real-world tests to deliver accurate lyric and melody suggestions. Get a free vs paid comparison, see detailed rankings, and discover must-try tools that can boost your creative workflow significantly. Explore now to find the perfect fit for your needs!
8 tools
xix.ai

2026 Latest Best ChatGPT Meal Planning Apps Top-rated must-try curated powerful game-changing tools for macro tracking grocery lists and weekly prep. XIX.AI delivers weekly updated rankings based on real-world tests, including free vs paid comparison details. Discover your perfect tool to boost productivity and unlock your AI edge today. Explore now!
9 tools
xix.ai

2026 Latest Best Top-Rated AI Video Script Tools for Short Form Content! XIX.AI has curated a powerful, game-changing collection of must-try tools that go through rigorous real-world tests. You’ll find detailed weekly updated rankings, free vs paid comparison info, and insights to help you boost productivity and unlock your AI edge in creating high-quality short form content. Explore now to discover your perfect tool!
10 tools
xix.ai

2026 Latest Best AI Comic Panel Tools for Storyboard Style Narratives! This curated top-rated collection features powerful game-changing solutions that help creators boost writing efficiency and overcome creation bottlenecks. You’ll find detailed free vs paid comparison, real-world tests, and official rankings to guide your pick. XIX.AI offers expert insights too. Explore now to Discover your perfect tool for bringing vivid stories to life! 238 characters
9 tools
xix.ai

2026 Latest Best Top-rated AI Video Generation Tools for Short Content are here on XIX.AI’s curated collection. These powerful game-changing tools have undergone rigorous real-world tests, featuring a comprehensive free vs paid comparison and detailed rankings to help you find the perfect option. Whether you need to create high-quality short videos fast or boost your productivity across various tasks, these must-try solutions deliver outstanding results. Explore now to discover your ideal tool and unlock your AI edge.
9 tools
xix.ai

2026 Latest Best AI Art Generators ranking showcases top-rated tools for creating stunning moodboards, exploring diverse styles, and defining visual directions. XIX.AI offers a curated list of powerful, game-changing options that have passed rigorous real-world tests. Get a free vs paid comparison to help you find the perfect fit for boosting your creative workflow. Explore now to Unlock your AI edge in art creation.
10 tools
xix.ai












