


 Home
DeepSeek V4 Flash: A Small-Scale Inference Engine Breaking Tradition
As artificial intelligence advances rapidly, DeepSeek V4Flash is setting a new standard for local inference engines through its distinct advantages. Tailored specifically for the Metal platform, this lightweight engine delivers a faster and more adaptable local inference experience. Rather than serving as a general-purpose tool, DeepSeek V4Flash is optimized exclusively for the DeepSeek V4Flash model, ensuring peak performance for its intended use.
Beyond raw speed, DeepSeek V4Flash excels in its reasoning architecture. With fewer parameters than comparable models, it processes tasks more efficiently. In its reasoning mode, it resolves complex queries in just one-fifth of the time required by other models, making it highly effective for demanding scenarios across various applications.
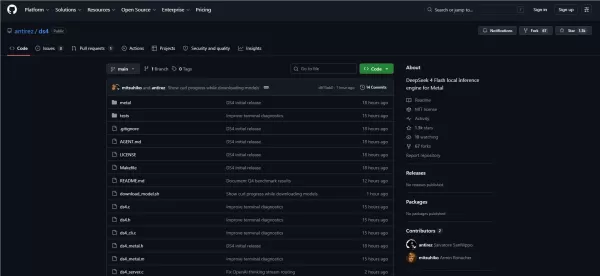
Additionally, DeepSeek V4Flash features a massive context window capable of handling up to one million tokens. This extensive processing power allows it to navigate cutting-edge topics effortlessly, whether discussing Italian programming or political affairs, showcasing a robust knowledge base.
Regarding hardware compatibility, DeepSeek V4Flash supports 2-bit quantization on a MacBook with 128GB of RAM, delivering impressive results. The DeepSeek team also plans to release a more powerful version in the future to further enhance user experience.
More than just an inference engine, DeepSeek V4Flash offers a comprehensive local solution, including an HTTP API and specially crafted GGUF models. This integration ensures seamless service and support for users. However, users should note that the current version remains in the Alpha stage and requires further refinement.
In conclusion, DeepSeek V4Flash has emerged as a standout option in local inference thanks to its unique design and powerful capabilities, with promising developments on the horizon.
Related article
 Tony Fadell on why the first wave of AI gadgets failed — and what comes next
As Tony Fadell steps onto the stage at the inaugural MIT Future Fest, he displays a slide featuring three discontinued, heavily hyped AI devices: the Rabbit R1, the Humane AI pin, and the Limitless pendant.“These represented the initial generation of
South Korea Passes Law to Boost AI by Allowing Limited Personal Data Use After Regulatory Review
The Korean Personal Information Protection Committee recently announced that the National Assembly has unanimously approved an amendment to the Personal Information Protection Act, permitting AI developers to utilize limited personal data following c
Hygon DCU Runs Trillion-Parameter Models With Kimi K3 Expert Parallelism
Domestic computing infrastructure has successfully powered a trillion-parameter model for the first time. Hai Guang Information confirmed full-stack adaptation and performance validation of Kimi K3 on its DCU platform, demonstrating that executing su
Related Special Topic Recommendations
Video creation
 Best AI Video Generators for Demos: Turn Scripts into Explainer Videos
2026 Latest Best Top-Rated AI Video Generators for Demos are curated here, offering powerful game-changing solutions to turn scripts into professional explainer videos fast. XIX.AI provides weekly updated rankings based on real-world tests, including free vs paid comparison details. Must-try tools help boost productivity significantly. Explore now to discover your perfect demo video creation tool!
 9 tools
 xix.ai
Finance
AI Cash Flow Forecasting Tools for Small Business Finance
2026 Latest Best Top-rated AI Cash Flow Forecasting Tools for Small Business Finance are here on XIX.AI! Our curated list features powerful, game-changing solutions that go through real-world tests to help small business owners boost financial accuracy, plan budgets more effectively, and avoid cash flow issues. Get a free vs paid comparison and explore now to find your perfect tool for seamless financial management.
7 tools
xix.ai
code
Best AI Coding Chatbots: Debug Python, JS, and SQL in One Place
2026 Latest Best Top-Rated AI Coding Chatbots Curated for Developers! Experience powerful game-changing tools that help you debug Python, JS, and SQL issues quickly. Get a free vs paid comparison along with real-world tests and detailed rankings to find the perfect fit for boosting your coding productivity. Try XIX.AI today to unlock your AI edge! Explore now.
12 tools
xix.ai
Prompt
AI Prompt Versioning Platforms for Reusable Claude and ChatGPT Playbooks
2026 Latest Best Top-rated AI Prompt Versioning Platforms for Reusable Playbooks are here on XIX.AI! Our curated list includes powerful game-changing tools that help you keep track of all prompts, test variations efficiently, and boost productivity across writing, content creation, and more. Get a free vs paid comparison along with real-world tests and updated rankings weekly. Explore now to discover your perfect tool for staying ahead in AI tasks!
9 tools
xix.ai
writing
Best AI Writing Assistants for Long Articles: Outline and Draft Faster
2026 Latest Best AI Writing Assistants for Long Articles: Outline and Draft Faster. XIX.AI curates the top-rated, must-try tools that offer powerful, game-changing support to boost writing efficiency significantly. You’ll find detailed free vs paid comparison, real-world tests, and updated rankings weekly. Explore now to Discover your perfect tool and Start creating today to Unlock your AI edge.
8 tools
xix.ai
Education and Learning
ChatGPT Study Tools for Exam Revision, Flashcards, and Homework Explanations
2026 Latest Best ChatGPT Study Tools for Exam Revision, Flashcards, and Homework Explanations! XIX.AI has curated a top-rated list of powerful game-changing tools designed to boost your productivity. These must-try solutions offer free vs paid comparison, real-world tests, and detailed rankings to help you find the perfect option for efficient exam preparation and homework support. Explore now to unlock your AI edge!
10 tools
xix.ai

 Comments (0)
0/500
As artificial intelligence advances rapidly, DeepSeek V4Flash is setting a new standard for local inference engines through its distinct advantages. Tailored specifically for the Metal platform, this lightweight engine delivers a faster and more adaptable local inference experience. Rather than serving as a general-purpose tool, DeepSeek V4Flash is optimized exclusively for the DeepSeek V4Flash model, ensuring peak performance for its intended use.
Beyond raw speed, DeepSeek V4Flash excels in its reasoning architecture. With fewer parameters than comparable models, it processes tasks more efficiently. In its reasoning mode, it resolves complex queries in just one-fifth of the time required by other models, making it highly effective for demanding scenarios across various applications.
Additionally, DeepSeek V4Flash features a massive context window capable of handling up to one million tokens. This extensive processing power allows it to navigate cutting-edge topics effortlessly, whether discussing Italian programming or political affairs, showcasing a robust knowledge base.
Regarding hardware compatibility, DeepSeek V4Flash supports 2-bit quantization on a MacBook with 128GB of RAM, delivering impressive results. The DeepSeek team also plans to release a more powerful version in the future to further enhance user experience.
More than just an inference engine, DeepSeek V4Flash offers a comprehensive local solution, including an HTTP API and specially crafted GGUF models. This integration ensures seamless service and support for users. However, users should note that the current version remains in the Alpha stage and requires further refinement.
In conclusion, DeepSeek V4Flash has emerged as a standout option in local inference thanks to its unique design and powerful capabilities, with promising developments on the horizon.








 Tony Fadell on why the first wave of AI gadgets failed — and what comes next
As Tony Fadell steps onto the stage at the inaugural MIT Future Fest, he displays a slide featuring three discontinued, heavily hyped AI devices: the Rabbit R1, the Humane AI pin, and the Limitless pendant.“These represented the initial generation of
 South Korea Passes Law to Boost AI by Allowing Limited Personal Data Use After Regulatory Review
The Korean Personal Information Protection Committee recently announced that the National Assembly has unanimously approved an amendment to the Personal Information Protection Act, permitting AI developers to utilize limited personal data following c
 Hygon DCU Runs Trillion-Parameter Models With Kimi K3 Expert Parallelism
Domestic computing infrastructure has successfully powered a trillion-parameter model for the first time. Hai Guang Information confirmed full-stack adaptation and performance validation of Kimi K3 on its DCU platform, demonstrating that executing su
2026 Latest Best Top-Rated AI Video Generators for Demos are curated here, offering powerful game-changing solutions to turn scripts into professional explainer videos fast. XIX.AI provides weekly updated rankings based on real-world tests, including free vs paid comparison details. Must-try tools help boost productivity significantly. Explore now to discover your perfect demo video creation tool!
9 tools
xix.ai
2026 Latest Best Top-rated AI Cash Flow Forecasting Tools for Small Business Finance are here on XIX.AI! Our curated list features powerful, game-changing solutions that go through real-world tests to help small business owners boost financial accuracy, plan budgets more effectively, and avoid cash flow issues. Get a free vs paid comparison and explore now to find your perfect tool for seamless financial management.
7 tools
xix.ai
2026 Latest Best Top-Rated AI Coding Chatbots Curated for Developers! Experience powerful game-changing tools that help you debug Python, JS, and SQL issues quickly. Get a free vs paid comparison along with real-world tests and detailed rankings to find the perfect fit for boosting your coding productivity. Try XIX.AI today to unlock your AI edge! Explore now.
12 tools
xix.ai
2026 Latest Best Top-rated AI Prompt Versioning Platforms for Reusable Playbooks are here on XIX.AI! Our curated list includes powerful game-changing tools that help you keep track of all prompts, test variations efficiently, and boost productivity across writing, content creation, and more. Get a free vs paid comparison along with real-world tests and updated rankings weekly. Explore now to discover your perfect tool for staying ahead in AI tasks!
9 tools
xix.ai
2026 Latest Best AI Writing Assistants for Long Articles: Outline and Draft Faster. XIX.AI curates the top-rated, must-try tools that offer powerful, game-changing support to boost writing efficiency significantly. You’ll find detailed free vs paid comparison, real-world tests, and updated rankings weekly. Explore now to Discover your perfect tool and Start creating today to Unlock your AI edge.
8 tools
xix.ai
2026 Latest Best ChatGPT Study Tools for Exam Revision, Flashcards, and Homework Explanations! XIX.AI has curated a top-rated list of powerful game-changing tools designed to boost your productivity. These must-try solutions offer free vs paid comparison, real-world tests, and detailed rankings to help you find the perfect option for efficient exam preparation and homework support. Explore now to unlock your AI edge!
10 tools
xix.ai












