


 Home
Alibaba's Tongyi Lab Open-Sources Fun-CineForge, Solves Multi-Speaker Dubbing Challenge
Traditional AI voice dubbing often falls short in high-stakes productions like films and animation, where capturing nuanced emotional peaks and perfectly synchronized lip movements is paramount. To tackle this core industry challenge, Tongyi Lab has officially launched and open-sourced the groundbreaking film-grade, multi-scenario multimodal dubbing model—Fun-CineForge .
Bridging the Audio-Visual Gap: A Four-Pillar Framework for Seamless Sync
Rather than relying on basic text-to-speech, Fun-CineForge is engineered to master four critical dimensions of professional dubbing:
Lip Sync: Ensures synthesized speech aligns with on-screen character mouth movements with exceptional precision.
Emotional Expression: Infuses the voice with authentic human-like emotion by analyzing facial cues and contextual instructions.
Voice Consistency: Maintains a stable, recognizable vocal identity for specific characters across complex multi-speaker dialogue scenes.
Time Alignment: Enables millisecond-accurate insertion of dialogue, even when the speaker is off-screen or partially obscured.
Core Innovation: Pioneering "Time Modality" and a High-Fidelity Dataset
The technical leap of Fun-CineForge stems from its unique "data + model" co-design philosophy:
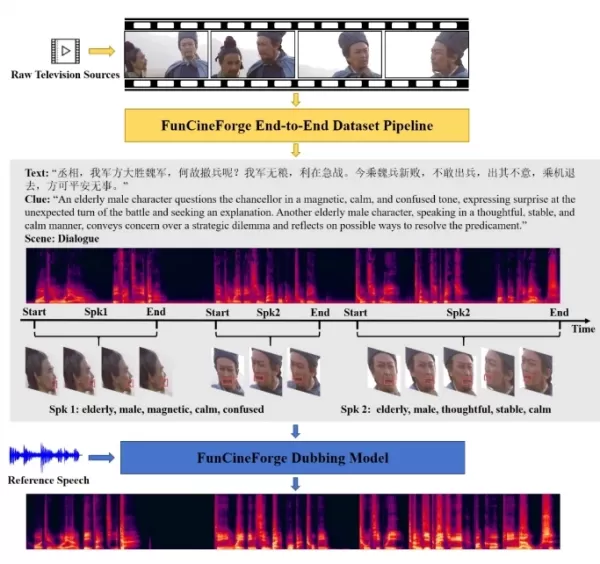
The CineDub High-Quality Dataset: Tongyi Lab has also open-sourced the automated CineDub dataset construction pipeline. Utilizing a chain-of-thought error correction mechanism, it reduces transcription error rates for Chinese and English text to approximately 1% - 2% and slashes speaker diarization errors to as low as 1.2%.
Four-Modality Fusion Architecture: The model pioneers the integration of a "time modality", jointly modeling visual inputs (lip shape and expression), text (dialogue and emotional context), and audio (voice reference). This fusion allows for exact synchronization in challenging scenes, including those without visible faces.
Demonstrated Excellence: Pioneering Authentic Multi-Character Dialogue Dubbing
Benchmark results demonstrate that Fun-CineForge substantially outperforms baseline models like DeepDubber-V1 across key metrics: word error rate (WER/CER), lip synchronization (LSE-C/D), and voice similarity. A landmark achievement is its first-of-its-kind capability to handle duet and multi-person dialogues with precision, showing remarkable robustness in video clips up to 30 seconds.
GitHub: https://github.com/FunAudioLLM/FunCineForge
HuggingFace: https://huggingface.co/FunAudioLLM/Fun-CineForge
ModelScope: https://www.modelscope.cn/models/FunAudioLLM/Fun-CineForge/
Related article
 Stripe to Acquire OpenRouter as AI Model Routing Gains Momentum
Stripe has agreed to acquire OpenRouter, an AI model-routing platform that gives developers access to hundreds of models through a single interface. The deal adds model selection and routing to Stripe’s existing work around AI usage and token-based b
Former OpenAI Researcher Barrett Zoph Returns to Google to Support Gemini Development
Barret Zoph, who previously abruptly left and joined OpenAI due to a disagreement with Thinking Machines Lab CEO Miriam Mularati, has once again changed employers. Alphabet's Google announced that Zoph will return as Vice President of Research, bring
How Recursive Intelligence Raised $335M at $4B Valuation in 4 Months
The co-founders of startup Ricursive Intelligence seemed destined to be co-founders.Anna Goldie, CEO, and Azalia Mirhoseini, CTO, are so well-known in the AI community that they were among those AI engineers who “got those weird emails from Zuckerber
Related Special Topic Recommendations
Design & Art
 Top AI Illustration Tools: Create Editorial Scenes and Cover Art Faster
2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
 10 tools
 xix.ai
Education and Learning
Top AI Tutors for Exam Prep: Practice Math, Science, and English
2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai
Finance
AI Budget Planning Tools for Personal Money Management
2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai
Health & Wellness
AI Sleep Tracking Assistants: Improve Recovery with Better Bedtime Habits
2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai
Data Analysis
AI SQL Copilots for Product and Revenue Analytics
2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai
Education and Learning
Best AI Homework Helpers That Teach: Learn Concepts, Not Just Answers
2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai

 Comments (0)
0/500
Traditional AI voice dubbing often falls short in high-stakes productions like films and animation, where capturing nuanced emotional peaks and perfectly synchronized lip movements is paramount. To tackle this core industry challenge, Tongyi Lab has officially launched and open-sourced the groundbreaking film-grade, multi-scenario multimodal dubbing model—
Bridging the Audio-Visual Gap: A Four-Pillar Framework for Seamless Sync
Rather than relying on basic text-to-speech, Fun-CineForge is engineered to master four critical dimensions of professional dubbing:
Lip Sync: Ensures synthesized speech aligns with on-screen character mouth movements with exceptional precision.
Emotional Expression: Infuses the voice with authentic human-like emotion by analyzing facial cues and contextual instructions.
Voice Consistency: Maintains a stable, recognizable vocal identity for specific characters across complex multi-speaker dialogue scenes.
Time Alignment: Enables millisecond-accurate insertion of dialogue, even when the speaker is off-screen or partially obscured.
Core Innovation: Pioneering "Time Modality" and a High-Fidelity Dataset
The technical leap of Fun-CineForge stems from its unique "data + model" co-design philosophy:
The CineDub High-Quality Dataset: Tongyi Lab has also open-sourced the automated CineDub dataset construction pipeline. Utilizing a chain-of-thought error correction mechanism, it reduces transcription error rates for Chinese and English text to approximately 1% - 2% and slashes speaker diarization errors to as low as 1.2%.
Four-Modality Fusion Architecture: The model pioneers the integration of a "time modality", jointly modeling visual inputs (lip shape and expression), text (dialogue and emotional context), and audio (voice reference). This fusion allows for exact synchronization in challenging scenes, including those without visible faces.
Demonstrated Excellence: Pioneering Authentic Multi-Character Dialogue Dubbing
Benchmark results demonstrate that Fun-CineForge substantially outperforms baseline models like DeepDubber-V1 across key metrics: word error rate (WER/CER), lip synchronization (LSE-C/D), and voice similarity. A landmark achievement is its first-of-its-kind capability to handle duet and multi-person dialogues with precision, showing remarkable robustness in video clips up to 30 seconds.
GitHub: https://github.com/FunAudioLLM/FunCineForge
HuggingFace: https://huggingface.co/FunAudioLLM/Fun-CineForge
ModelScope: https://www.modelscope.cn/models/FunAudioLLM/Fun-CineForge/








 Stripe to Acquire OpenRouter as AI Model Routing Gains Momentum
Stripe has agreed to acquire OpenRouter, an AI model-routing platform that gives developers access to hundreds of models through a single interface. The deal adds model selection and routing to Stripe’s existing work around AI usage and token-based b
 Former OpenAI Researcher Barrett Zoph Returns to Google to Support Gemini Development
Barret Zoph, who previously abruptly left and joined OpenAI due to a disagreement with Thinking Machines Lab CEO Miriam Mularati, has once again changed employers. Alphabet's Google announced that Zoph will return as Vice President of Research, bring
 How Recursive Intelligence Raised $335M at $4B Valuation in 4 Months
The co-founders of startup Ricursive Intelligence seemed destined to be co-founders.Anna Goldie, CEO, and Azalia Mirhoseini, CTO, are so well-known in the AI community that they were among those AI engineers who “got those weird emails from Zuckerber

2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
10 tools
xix.ai

2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai

2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai

2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai












