
option
Home
Flash News
Content
JerryGonzalez
JerryGonzalez
July 27, 2026

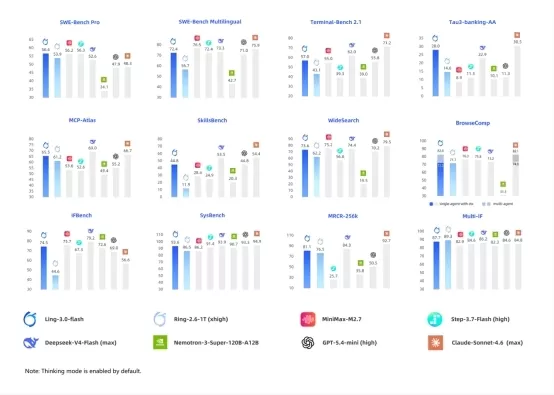
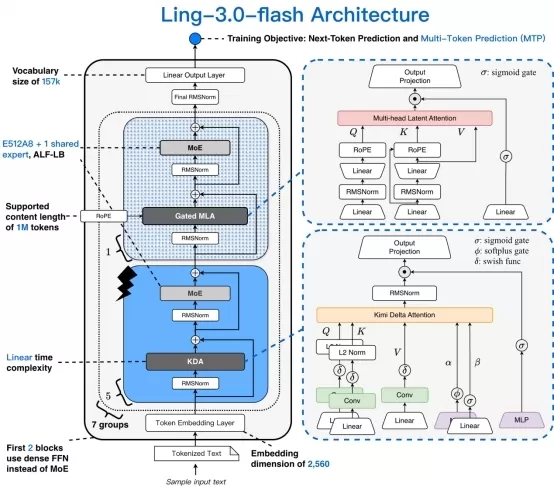
Ant Bailing launched Ling-3.0-Flash, a hybrid reasoning model with 124B total parameters and 5.1B activated, matching or exceeding models 2-3 times larger in reasoning and long-text tasks. It features a 5:1 hybrid attention architecture (KDA linear and MLA layers) and a 1/64 expert activation ratio for higher efficiency. Optimized for agent applications with over 10,000 training scenarios, it reduces first-token latency by 60-80% via hierarchical caching. Now available on OpenRouter for free for one week, then open-sourced.
Ant Bailing launched Ling-3.0-Flash, a hybrid reasoning model with 124B total parameters and 5.1B activated, matching or exceeding models 2-3 times larger in reasoning and long-text tasks. It features a 5:1 hybrid attention architecture (KDA linear and MLA layers) and a 1/64 expert activation ratio for higher efficiency. Optimized for agent applications with over 10,000 training scenarios, it reduces first-token latency by 60-80% via hierarchical caching. Now available on OpenRouter for free for one week, then open-sourced. Ant Bailing launched Ling-3.0-Flash, a hybrid reasoning model with 124B total parameters and 5.1B activated, matching or exceeding models 2-3 times larger in reasoning and long-text tasks. It features a 5:1 hybrid attention architecture (KDA linear and MLA layers) and a 1/64 expert activation ratio for higher efficiency. Optimized for agent applications with over 10,000 training scenarios, it reduces first-token latency by 60-80% via hierarchical caching. Now available on OpenRouter for free for one week, then open-sourced.
Comments (0)
0/300
OR