


 Home
High School Student Creates Website for AI Minecraft Build-Off Challenges
Creative AI Benchmarking with Minecraft
As traditional AI benchmarking methods fall short, developers are exploring innovative approaches to evaluate the prowess of generative AI models. One such creative method involves using Minecraft, the popular sandbox game owned by Microsoft. A group of developers has launched Minecraft Benchmark, or MC-Bench, a platform where AI models compete in creating Minecraft builds based on given prompts.
On MC-Bench, users can vote on which AI model's creation they prefer, and only after casting their vote do they discover which model made each build. This interactive approach not only engages the community but also provides a unique way to assess AI capabilities.
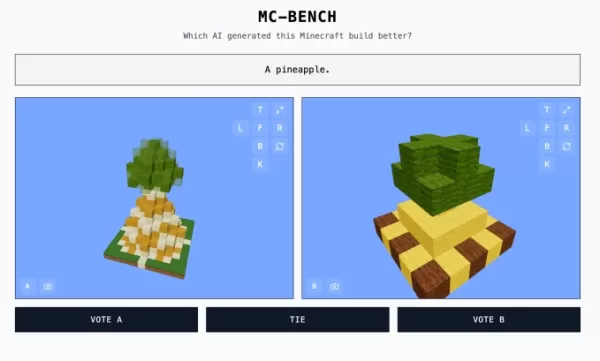
Image Credits:Minecraft Benchmark
Adi Singh, a 12th-grader and the initiator of MC-Bench, believes that Minecraft's widespread recognition is key. As the best-selling video game ever, it's familiar to many, making it easier for people to judge the quality of AI-generated builds, even if they haven't played the game themselves. "Minecraft allows people to see the progress [of AI development] much more easily," Singh explained to TechCrunch. "People are used to Minecraft, used to the look and the vibe."
MC-Bench is supported by a team of eight volunteer contributors. Companies like Anthropic, Google, OpenAI, and Alibaba have provided their products for running benchmark prompts, though they are not otherwise involved with the project.
Singh envisions expanding MC-Bench beyond simple builds to more complex, goal-oriented tasks. "Games might just be a medium to test agentic reasoning that is safer than in real life and more controllable for testing purposes, making it more ideal in my eyes," he said.
Other Games as AI Benchmarks
Besides Minecraft, other games like Pokémon Red, Street Fighter, and Pictionary have been used as experimental benchmarks for AI. The challenge of benchmarking AI lies in its complexity, as traditional standardized tests often favor AI models due to their training methods, which excel in narrow problem-solving areas like rote memorization or basic extrapolation.
For instance, while OpenAI's GPT-4 can score in the 88th percentile on the LSAT, it struggles with simpler tasks like counting the number of Rs in "strawberry." Similarly, Anthropic's Claude 3.7 Sonnet achieved 62.3% accuracy on a software engineering benchmark but falls short in playing Pokémon compared to most five-year-olds.
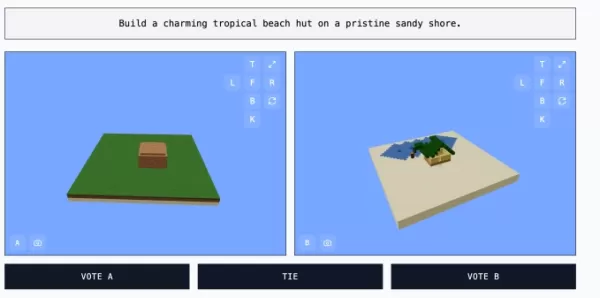
Image Credits:Minecraft Benchmark
MC-Bench: More Than Just a Programming Benchmark
Technically, MC-Bench is a programming benchmark because it requires AI models to write code to create builds like "Frosty the Snowman" or "a charming tropical beach hut on a pristine sandy shore." However, the platform's appeal lies in its accessibility. It's easier for users to evaluate the visual quality of a build than to analyze code, which broadens the project's reach and potential for data collection on model performance.
The debate continues on whether these scores truly reflect AI usefulness. Singh, however, believes they are a strong indicator. "The current leaderboard reflects quite closely to my own experience of using these models, which is unlike a lot of pure text benchmarks," he said. "Maybe [MC-Bench] could be useful to companies to know if they're heading in the right direction."
Related article
 DeepMind CEO Hassabis: I sleep six hours a day, usually feel energetic around 1 a.m.
Fortune recently featured an interview with Demis Hassabis, CEO of Google DeepMind, revealing his unconventional approach to rest and productivity. Hassabis disclosed that he sleeps very little, structuring his waking hours into two distinct work blo
OpenAI, Anthropic Vie for Market Share Despite Revenue Shortfalls
Despite recent reports suggesting OpenAI missed revenue targets, creating pressure on tech stocks this Tuesday, private AI lab investors remain resilient. Seasoned backers have confirmed they will not reduce investment despite negative media coverage
California AV Compliance: A New Era of Tickets, Geofences, and 1M Miles
Guident operates an AuveTech shuttle in South Florida, managing a four-mile route in West Palm Beach and a one-mile route in Boca Raton using its remote monitoring technology. | Credit: GuidentCalifornia is redefining the regulatory landscape for dri
Related Special Topic Recommendations
Music composition
 AI Stem Separation Tools for Remix Production, Sampling Prep, and Karaoke Masters
2026 Latest Best Top-rated AI Stem Separation Tools Curated for Remix Production, Sampling Prep, and Karaoke Masters. These powerful game-changing tools offer real-world tests to deliver precise audio isolation, boosting productivity significantly. XIX.AI provides a weekly updated free vs paid comparison guide to help you find the must-try solution that suits your needs. Explore now to unlock your AI edge.
 8 tools
 xix.ai
Data Analysis
AI SQL Copilots for Revenue Dashboards, Funnel Analysis, and Product Metrics
2026 Latest Best AI SQL Copilots Ranked Top-Rated! XIX.AI curates a powerful game-changing collection for weekly updated real-world tests. These must-try tools help you generate accurate revenue dashboards, analyze sales funnels, and track product metrics swiftly, boosting productivity massively. Explore now to Discover your perfect tool for data-driven decision making! 238 characters
9 tools
xix.ai
Music composition
Best AI Melody Writing Tools for Song Drafts
2026 Latest Best Top-Rated AI Melody Writing Tools for Song Drafts! XIX.AI has curated a highly powerful game-changing collection that goes through rigorous real-world tests to deliver the best writing experience. You can find detailed free vs paid comparisons, accurate rankings, and must-try options designed to help you create stunning song drafts effortlessly and boost your creative productivity significantly. Explore now to discover your perfect tool!
8 tools
xix.ai
chatbot
Best AI Conversation Trainer Tools for Interview Practice
2026 Latest Best Top-rated AI Conversation Trainer Tools for Interview Practice are here on XIX.AI! This curated collection features powerful, game-changing tools that go through rigorous real-world tests to deliver accurate feedback. You’ll find a free vs paid comparison and detailed rankings to help you choose the must-try option that boosts your confidence and skills. Explore now to Discover your perfect tool for interview success!
12 tools
xix.ai
Design & Art
Best AI Style Transfer Tools for Creative Experiments
2026 Latest Best Top-rated AI Style Transfer Tools for Creative Experiments! XIX.AI has curated a powerful, game-changing collection of must-try tools that deliver exceptional results through real-world tests and rigorous rankings. These top solutions help creatives boost productivity significantly by accelerating content creation and unlocking endless creative possibilities. Explore now to discover your perfect tool and start creating today!
9 tools
xix.ai
Comic Creation
Best AI Dialogue Bubble Tools for Visual Storytelling
2026 Latest Best Top-Rated AI Dialogue Bubble Tools for Visual Storytelling are here on XIX.AI! This curated collection features powerful, game-changing tools that help creators boost productivity and overcome creative bottlenecks. Get a free vs paid comparison, see real-world tests, and check the latest rankings to find the must-try solutions perfect for crafting engaging visual narratives. Explore now to discover your ideal tool!
10 tools
xix.ai

 Comments (27)
0/500
![DouglasMartinez]()
Interesting approach! Using Minecraft for AI benchmarking sounds way more engaging than standard tests. Wonder if this could lead to AI that actually helps design game worlds? The student's project is a cool example of how gaming and AI research can mix. Hope they share the results! 🎮
![RaymondGreen]()
高校生がAI建築チャレンジのサイトを作ったのか…!Minecraftの世界でAIの創造性を測るってアイデア、すごく面白いな。でも、これって結局マイクロソフトのプロモーションみたいなものじゃないの?AIがどんどんゲーム内に溶け込んでいくの、ちょっと怖い気もする😅 未来のゲームはすべてAIが作っちゃうのかな?
![NicholasYoung]()
AIが建築対決するなんて面白すぎる!🏗️ Minecraftでベンチマークを取る発想が新鮮だけど、これってゲームバランス崩さないのかな?ちょっと心配…
![JamesMiller]()
É sempre incrível ver jovens inovando com IA! Alguém já testou se esses desafios do Minecraft realmente conseguem medir bem a criatividade dos modelos? Ou será que é só mais uma moda passageira? 😅
![RalphRoberts]()
这个高中生用Minecraft来测试AI生成建筑也太有创意了吧!😂 传统AI评测标准太死板了,确实需要这种更直观有趣的方式。不过我很好奇评判标准是什么,是美观度还是还原度?也想试试看用我的世界来测试Stable Diffusion效果
![JasonJohnson]()
This high school kid building an AI Minecraft challenge site is wild! 🧱 Makes me wonder how far AI can push creativity in games. Could it outbuild my epic castle? 😎
Creative AI Benchmarking with Minecraft
As traditional AI benchmarking methods fall short, developers are exploring innovative approaches to evaluate the prowess of generative AI models. One such creative method involves using Minecraft, the popular sandbox game owned by Microsoft. A group of developers has launched Minecraft Benchmark, or MC-Bench, a platform where AI models compete in creating Minecraft builds based on given prompts.
On MC-Bench, users can vote on which AI model's creation they prefer, and only after casting their vote do they discover which model made each build. This interactive approach not only engages the community but also provides a unique way to assess AI capabilities.
Adi Singh, a 12th-grader and the initiator of MC-Bench, believes that Minecraft's widespread recognition is key. As the best-selling video game ever, it's familiar to many, making it easier for people to judge the quality of AI-generated builds, even if they haven't played the game themselves. "Minecraft allows people to see the progress [of AI development] much more easily," Singh explained to TechCrunch. "People are used to Minecraft, used to the look and the vibe."
MC-Bench is supported by a team of eight volunteer contributors. Companies like Anthropic, Google, OpenAI, and Alibaba have provided their products for running benchmark prompts, though they are not otherwise involved with the project.
Singh envisions expanding MC-Bench beyond simple builds to more complex, goal-oriented tasks. "Games might just be a medium to test agentic reasoning that is safer than in real life and more controllable for testing purposes, making it more ideal in my eyes," he said.
Other Games as AI Benchmarks
Besides Minecraft, other games like Pokémon Red, Street Fighter, and Pictionary have been used as experimental benchmarks for AI. The challenge of benchmarking AI lies in its complexity, as traditional standardized tests often favor AI models due to their training methods, which excel in narrow problem-solving areas like rote memorization or basic extrapolation.
For instance, while OpenAI's GPT-4 can score in the 88th percentile on the LSAT, it struggles with simpler tasks like counting the number of Rs in "strawberry." Similarly, Anthropic's Claude 3.7 Sonnet achieved 62.3% accuracy on a software engineering benchmark but falls short in playing Pokémon compared to most five-year-olds.
MC-Bench: More Than Just a Programming Benchmark
Technically, MC-Bench is a programming benchmark because it requires AI models to write code to create builds like "Frosty the Snowman" or "a charming tropical beach hut on a pristine sandy shore." However, the platform's appeal lies in its accessibility. It's easier for users to evaluate the visual quality of a build than to analyze code, which broadens the project's reach and potential for data collection on model performance.
The debate continues on whether these scores truly reflect AI usefulness. Singh, however, believes they are a strong indicator. "The current leaderboard reflects quite closely to my own experience of using these models, which is unlike a lot of pure text benchmarks," he said. "Maybe [MC-Bench] could be useful to companies to know if they're heading in the right direction."








 DeepMind CEO Hassabis: I sleep six hours a day, usually feel energetic around 1 a.m.
Fortune recently featured an interview with Demis Hassabis, CEO of Google DeepMind, revealing his unconventional approach to rest and productivity. Hassabis disclosed that he sleeps very little, structuring his waking hours into two distinct work blo
 OpenAI, Anthropic Vie for Market Share Despite Revenue Shortfalls
Despite recent reports suggesting OpenAI missed revenue targets, creating pressure on tech stocks this Tuesday, private AI lab investors remain resilient. Seasoned backers have confirmed they will not reduce investment despite negative media coverage
California AV Compliance: A New Era of Tickets, Geofences, and 1M Miles
Guident operates an AuveTech shuttle in South Florida, managing a four-mile route in West Palm Beach and a one-mile route in Boca Raton using its remote monitoring technology. | Credit: GuidentCalifornia is redefining the regulatory landscape for dri

2026 Latest Best Top-rated AI Stem Separation Tools Curated for Remix Production, Sampling Prep, and Karaoke Masters. These powerful game-changing tools offer real-world tests to deliver precise audio isolation, boosting productivity significantly. XIX.AI provides a weekly updated free vs paid comparison guide to help you find the must-try solution that suits your needs. Explore now to unlock your AI edge.
8 tools
xix.ai

2026 Latest Best AI SQL Copilots Ranked Top-Rated! XIX.AI curates a powerful game-changing collection for weekly updated real-world tests. These must-try tools help you generate accurate revenue dashboards, analyze sales funnels, and track product metrics swiftly, boosting productivity massively. Explore now to Discover your perfect tool for data-driven decision making! 238 characters
9 tools
xix.ai

2026 Latest Best Top-Rated AI Melody Writing Tools for Song Drafts! XIX.AI has curated a highly powerful game-changing collection that goes through rigorous real-world tests to deliver the best writing experience. You can find detailed free vs paid comparisons, accurate rankings, and must-try options designed to help you create stunning song drafts effortlessly and boost your creative productivity significantly. Explore now to discover your perfect tool!
8 tools
xix.ai

2026 Latest Best Top-rated AI Conversation Trainer Tools for Interview Practice are here on XIX.AI! This curated collection features powerful, game-changing tools that go through rigorous real-world tests to deliver accurate feedback. You’ll find a free vs paid comparison and detailed rankings to help you choose the must-try option that boosts your confidence and skills. Explore now to Discover your perfect tool for interview success!
12 tools
xix.ai

2026 Latest Best Top-rated AI Style Transfer Tools for Creative Experiments! XIX.AI has curated a powerful, game-changing collection of must-try tools that deliver exceptional results through real-world tests and rigorous rankings. These top solutions help creatives boost productivity significantly by accelerating content creation and unlocking endless creative possibilities. Explore now to discover your perfect tool and start creating today!
9 tools
xix.ai

2026 Latest Best Top-Rated AI Dialogue Bubble Tools for Visual Storytelling are here on XIX.AI! This curated collection features powerful, game-changing tools that help creators boost productivity and overcome creative bottlenecks. Get a free vs paid comparison, see real-world tests, and check the latest rankings to find the must-try solutions perfect for crafting engaging visual narratives. Explore now to discover your ideal tool!
10 tools
xix.ai

Interesting approach! Using Minecraft for AI benchmarking sounds way more engaging than standard tests. Wonder if this could lead to AI that actually helps design game worlds? The student's project is a cool example of how gaming and AI research can mix. Hope they share the results! 🎮
高校生がAI建築チャレンジのサイトを作ったのか…!Minecraftの世界でAIの創造性を測るってアイデア、すごく面白いな。でも、これって結局マイクロソフトのプロモーションみたいなものじゃないの?AIがどんどんゲーム内に溶け込んでいくの、ちょっと怖い気もする😅 未来のゲームはすべてAIが作っちゃうのかな?
AIが建築対決するなんて面白すぎる!🏗️ Minecraftでベンチマークを取る発想が新鮮だけど、これってゲームバランス崩さないのかな?ちょっと心配…
É sempre incrível ver jovens inovando com IA! Alguém já testou se esses desafios do Minecraft realmente conseguem medir bem a criatividade dos modelos? Ou será que é só mais uma moda passageira? 😅
这个高中生用Minecraft来测试AI生成建筑也太有创意了吧!😂 传统AI评测标准太死板了,确实需要这种更直观有趣的方式。不过我很好奇评判标准是什么,是美观度还是还原度?也想试试看用我的世界来测试Stable Diffusion效果
This high school kid building an AI Minecraft challenge site is wild! 🧱 Makes me wonder how far AI can push creativity in games. Could it outbuild my epic castle? 😎












