


 Home
Douba Seedance 2.5 Video Generation Model Debuts, Official Release Set for Early July
During the 2026 ByteDance Engine FORCE Original Power Conference, which recently concluded, a major advancement in video generation large models was announced. ByteDance's Douyin subsidiary unveiled the Seedance2.5 video generation model, now available for global enterprise beta testing, with an official launch expected in early July.
With this upgrade, Seedance2.5 delivers industry-leading performance across several key metrics. Its standout achievement is video generation length: single videos can now reach up to 30 seconds, the longest globally. While current video models are often constrained by a 15- to 20-second creative ceiling, Seedance2.5 not only enhances the continuity of scene expression but also enables long-form narrative short films.
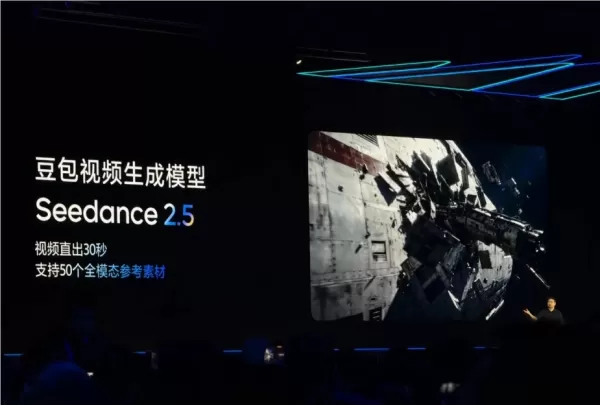
For creative flexibility, Seedance2.5 introduces highly competitive multi-modal material processing, supporting up to 50 full-modal materials for joint input. Creators can import image assets of multiple actors simultaneously, and the model automatically handles arrangement and scheduling, greatly streamlining the workflow from raw materials to final output. Additionally, the model offers a "local re-drawing" feature that allows localized adjustments—such as changing backgrounds, replacing products, or substituting models—without affecting the overall image. During demonstrations, this feature effectively addressed common complex replacement scenarios in e-commerce advertising.
Beyond the video model, ByteDance Engine also showcased the image creation model Seedream5.0Pro and the audio generation model Seed-Audio1.0. The former excels in interactive precise editing, layered design, and native text generation, enabling direct production of editable design sketches. The latter features zero-shot multi-modal reference capabilities, supporting simultaneous generation of vivid dialogues for multiple characters, background music, and sound effects.
With a comprehensive layout across video, image, and audio, the Douyin series models are further cementing their technological lead in the generative AI space through deep multi-modal collaboration. As these tools are set to officially launch in early July, the production efficiency of the video creation industry may see another acceleration.
Related article
 DeepMind CEO Hassabis: I sleep six hours a day, usually feel energetic around 1 a.m.
Fortune recently featured an interview with Demis Hassabis, CEO of Google DeepMind, revealing his unconventional approach to rest and productivity. Hassabis disclosed that he sleeps very little, structuring his waking hours into two distinct work blo
OpenAI, Anthropic Vie for Market Share Despite Revenue Shortfalls
Despite recent reports suggesting OpenAI missed revenue targets, creating pressure on tech stocks this Tuesday, private AI lab investors remain resilient. Seasoned backers have confirmed they will not reduce investment despite negative media coverage
California AV Compliance: A New Era of Tickets, Geofences, and 1M Miles
Guident operates an AuveTech shuttle in South Florida, managing a four-mile route in West Palm Beach and a one-mile route in Boca Raton using its remote monitoring technology. | Credit: GuidentCalifornia is redefining the regulatory landscape for dri
Related Special Topic Recommendations
writing
 AI Article Outline Tools for Long Form Writing
2026 Latest Best Top-Rated AI Article Outline Tools for Long Form Writing! This curated collection features powerful, game-changing tools that deliver accurate, structured outlines with real-world tests to boost writing efficiency significantly. XIX.AI is part of this elite selection. Get a free vs paid comparison to help you choose the perfect tool. Explore now and Unlock your AI edge!
 9 tools
 xix.ai
chatbot
Best AI Roleplay Chat Apps for Language Practice, Interview Prep, and Daily Fluency
2026 Latest Best Top-rated AI Roleplay Chat Apps for Language Practice, Interview Prep, and Daily Fluency! XIX.AI curates a powerful game-changing collection that offers free vs paid comparison, real-world tests, and updated rankings weekly. These must-try tools help you boost writing skills, overcome fluency challenges, and improve communication efficiency across all daily scenarios. Explore now to discover your perfect tool for language growth!
10 tools
xix.ai
Music composition
AI Stem Separation Tools for Remix Production, Sampling Prep, and Karaoke Masters
2026 Latest Best Top-rated AI Stem Separation Tools Curated for Remix Production, Sampling Prep, and Karaoke Masters. These powerful game-changing tools offer real-world tests to deliver precise audio isolation, boosting productivity significantly. XIX.AI provides a weekly updated free vs paid comparison guide to help you find the must-try solution that suits your needs. Explore now to unlock your AI edge.
8 tools
xix.ai
Data Analysis
AI SQL Copilots for Revenue Dashboards, Funnel Analysis, and Product Metrics
2026 Latest Best AI SQL Copilots Ranked Top-Rated! XIX.AI curates a powerful game-changing collection for weekly updated real-world tests. These must-try tools help you generate accurate revenue dashboards, analyze sales funnels, and track product metrics swiftly, boosting productivity massively. Explore now to Discover your perfect tool for data-driven decision making! 238 characters
9 tools
xix.ai
Music composition
Best AI Melody Writing Tools for Song Drafts
2026 Latest Best Top-Rated AI Melody Writing Tools for Song Drafts! XIX.AI has curated a highly powerful game-changing collection that goes through rigorous real-world tests to deliver the best writing experience. You can find detailed free vs paid comparisons, accurate rankings, and must-try options designed to help you create stunning song drafts effortlessly and boost your creative productivity significantly. Explore now to discover your perfect tool!
8 tools
xix.ai
chatbot
Best AI Conversation Trainer Tools for Interview Practice
2026 Latest Best Top-rated AI Conversation Trainer Tools for Interview Practice are here on XIX.AI! This curated collection features powerful, game-changing tools that go through rigorous real-world tests to deliver accurate feedback. You’ll find a free vs paid comparison and detailed rankings to help you choose the must-try option that boosts your confidence and skills. Explore now to Discover your perfect tool for interview success!
12 tools
xix.ai

 Comments (0)
0/500
During the 2026 ByteDance Engine FORCE Original Power Conference, which recently concluded, a major advancement in video generation large models was announced. ByteDance's Douyin subsidiary unveiled the Seedance2.5 video generation model, now available for global enterprise beta testing, with an official launch expected in early July.
With this upgrade, Seedance2.5 delivers industry-leading performance across several key metrics. Its standout achievement is video generation length: single videos can now reach up to 30 seconds, the longest globally. While current video models are often constrained by a 15- to 20-second creative ceiling, Seedance2.5 not only enhances the continuity of scene expression but also enables long-form narrative short films.
For creative flexibility, Seedance2.5 introduces highly competitive multi-modal material processing, supporting up to 50 full-modal materials for joint input. Creators can import image assets of multiple actors simultaneously, and the model automatically handles arrangement and scheduling, greatly streamlining the workflow from raw materials to final output. Additionally, the model offers a "local re-drawing" feature that allows localized adjustments—such as changing backgrounds, replacing products, or substituting models—without affecting the overall image. During demonstrations, this feature effectively addressed common complex replacement scenarios in e-commerce advertising.
Beyond the video model, ByteDance Engine also showcased the image creation model Seedream5.0Pro and the audio generation model Seed-Audio1.0. The former excels in interactive precise editing, layered design, and native text generation, enabling direct production of editable design sketches. The latter features zero-shot multi-modal reference capabilities, supporting simultaneous generation of vivid dialogues for multiple characters, background music, and sound effects.
With a comprehensive layout across video, image, and audio, the Douyin series models are further cementing their technological lead in the generative AI space through deep multi-modal collaboration. As these tools are set to officially launch in early July, the production efficiency of the video creation industry may see another acceleration.








 DeepMind CEO Hassabis: I sleep six hours a day, usually feel energetic around 1 a.m.
Fortune recently featured an interview with Demis Hassabis, CEO of Google DeepMind, revealing his unconventional approach to rest and productivity. Hassabis disclosed that he sleeps very little, structuring his waking hours into two distinct work blo
 OpenAI, Anthropic Vie for Market Share Despite Revenue Shortfalls
Despite recent reports suggesting OpenAI missed revenue targets, creating pressure on tech stocks this Tuesday, private AI lab investors remain resilient. Seasoned backers have confirmed they will not reduce investment despite negative media coverage
California AV Compliance: A New Era of Tickets, Geofences, and 1M Miles
Guident operates an AuveTech shuttle in South Florida, managing a four-mile route in West Palm Beach and a one-mile route in Boca Raton using its remote monitoring technology. | Credit: GuidentCalifornia is redefining the regulatory landscape for dri

2026 Latest Best Top-Rated AI Article Outline Tools for Long Form Writing! This curated collection features powerful, game-changing tools that deliver accurate, structured outlines with real-world tests to boost writing efficiency significantly. XIX.AI is part of this elite selection. Get a free vs paid comparison to help you choose the perfect tool. Explore now and Unlock your AI edge!
9 tools
xix.ai

2026 Latest Best Top-rated AI Roleplay Chat Apps for Language Practice, Interview Prep, and Daily Fluency! XIX.AI curates a powerful game-changing collection that offers free vs paid comparison, real-world tests, and updated rankings weekly. These must-try tools help you boost writing skills, overcome fluency challenges, and improve communication efficiency across all daily scenarios. Explore now to discover your perfect tool for language growth!
10 tools
xix.ai

2026 Latest Best Top-rated AI Stem Separation Tools Curated for Remix Production, Sampling Prep, and Karaoke Masters. These powerful game-changing tools offer real-world tests to deliver precise audio isolation, boosting productivity significantly. XIX.AI provides a weekly updated free vs paid comparison guide to help you find the must-try solution that suits your needs. Explore now to unlock your AI edge.
8 tools
xix.ai

2026 Latest Best AI SQL Copilots Ranked Top-Rated! XIX.AI curates a powerful game-changing collection for weekly updated real-world tests. These must-try tools help you generate accurate revenue dashboards, analyze sales funnels, and track product metrics swiftly, boosting productivity massively. Explore now to Discover your perfect tool for data-driven decision making! 238 characters
9 tools
xix.ai

2026 Latest Best Top-Rated AI Melody Writing Tools for Song Drafts! XIX.AI has curated a highly powerful game-changing collection that goes through rigorous real-world tests to deliver the best writing experience. You can find detailed free vs paid comparisons, accurate rankings, and must-try options designed to help you create stunning song drafts effortlessly and boost your creative productivity significantly. Explore now to discover your perfect tool!
8 tools
xix.ai

2026 Latest Best Top-rated AI Conversation Trainer Tools for Interview Practice are here on XIX.AI! This curated collection features powerful, game-changing tools that go through rigorous real-world tests to deliver accurate feedback. You’ll find a free vs paid comparison and detailed rankings to help you choose the must-try option that boosts your confidence and skills. Explore now to Discover your perfect tool for interview success!
12 tools
xix.ai












