


 Home
27B Math SOTA and 3-Second Emotional Cloning: Youdao Open-Sources Zi Yue 4 Multimodal and TTS Engine
NetEase Youdao recently announced a comprehensive upgrade of its "Confucius4" large model to version 4.0. Now fully multimodal, Confucius4 supports integrated text, image, and audio interactions. Youdao also open-sourced its core multimodal and text-to-speech (TTS) models, while the translation model underwent a deep technical overhaul, delivering improvements in both quality and efficiency.
The multimodal model achieves SOTA in vision and mathematics, with superior performance on pure-text math problems
According to the announcement, the open-source Confucius4 multimodal model, with 27 billion parameters, has brought visual-input-based math capabilities to an industry-leading level (SOTA) in educational scenarios. Among models of similar scale, Confucius4 excels at handling advanced visual math and physics problems that incorporate charts. It also shows significant improvement on Chinese pure-text math problems, achieving an accuracy of 81.4%, which is industry-leading.
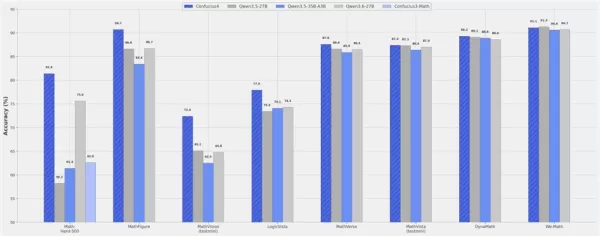
▲ Confucius4 achieves best-in-class results on multiple visual math benchmarks among models of the same scale
Image source: https://huggingface.co/netease-youdao/Confucius4
A more critical breakthrough lies in practical cost-effectiveness. According to relevant officials, the new model employs a refined reasoning chain reconstruction scheme. By aggregating a large volume of high-quality, concise reasoning samples for deep optimization, it compresses the output length of the reasoning chain by 43.2%.
This means it can deliver answers faster with fewer tokens and shorter reasoning paths, significantly reducing inference costs in real-world business scenarios for enterprises and developers.
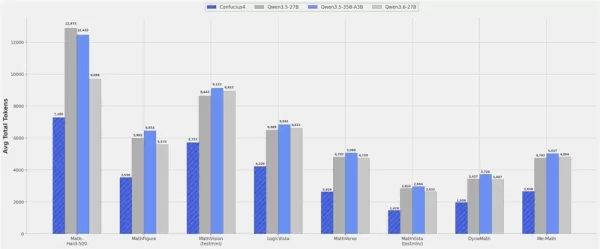
▲ Confucius4 significantly reduces output tokens on multiple visual math benchmarks
Image source: https://huggingface.co/netease-youdao/Confucius4
Additionally, the Confucius4 research team deeply optimized the model for real-world homework, exams, and problem-solving scenarios faced by Chinese students. This enables it to address authentic learning challenges, making it a more empathetic digital assistant.
Open-source TTS: supports 14 languages, clones original voice in 3 seconds with no accent issues across languages
Alongside the multimodal model, the speech synthesis (TTS) engine was also open-sourced. Built on a cutting-edge "speech encoder + LLM" architecture, it offers developers and content creators zero-shot, low-barrier voice cloning and emotional synthesis capabilities.
Currently, it fully supports 14 languages: Chinese, English, Japanese, Korean, German, French, Spanish, Indonesian, Italian, Thai, Portuguese, Russian, Malay, and Vietnamese. The system can naturally transfer a speaker's voice across different languages without additional training, maintaining voice consistency while ensuring the synthesized results sound native and fluent, with no accent leakage during cross-language cloning.
For voice cloning, Confucius4 achieves full "upload and clone" support. Users simply provide any audio material, and the system replicates the original voice within three seconds. According to the announcement, the engine's accuracy on cloning tasks exceeds 97%, and the similarity between the cloned voice and the original voice is over 85%. It preserves the speaker's unique vocal characteristics while accurately reproducing their emotional tone, with comprehensive capabilities that rank among the top in the field.
Furthermore, this open-source model demonstrates strong robustness in real multilingual scenarios. It can handle various synthesis needs, including daily conversations, news broadcasts, corporate promotions, and complex emotional expressions.
Translation model quality upgraded comprehensively, with 80% faster inference speed
As one of Youdao's most deeply rooted technological assets, the translation model also received significant technical upgrades in this update, further enhancing its performance on translation tasks.
Regarding data, the Confucius team collected and cleaned billions of multilingual items and hired professionals with TEM-8 certification for multidimensional manual evaluation, ensuring high-quality corpora from the start.
On the algorithmic side, the model uses an innovative "multi-expert OPD" mode, adopting a smarter "soft approach" to leverage the strengths of various experts. It also introduces format rewards and language detection mechanisms through reinforcement learning, effectively resolving common issues like out-of-context translations and mixed-language outputs in machine translation.
To meet the demands of high-frequency, high-concurrency industrial applications, the updated translation model is equipped with an efficient acceleration mechanism that directly boosts overall inference speed by 80%. Combined with a customized solution of automated large model evaluation and random manual sampling, the new generation translation model demonstrates extremely high standards of speed and quality across multiple scenarios, including text, image, and document translation.
Reflecting on Youdao's journey in AI, from the initial launch of Confucius as the first education-focused large model, introducing the "virtual speaking coach Hi Echo" that overturned traditional oral practice methods, to the comprehensive integration of Confucius 2.0 and 3.0 into software and hardware ecosystems, Youdao has consistently led AI empowerment in real-world scenarios. In 2026, Youdao accelerated AI application with a series of AI Agent products such as LobsterAI, Youdao Treasure, Youdao Conference Agent, and Thinkflow, realizing a forward-looking full-scenario AI Agent matrix.
The upgrade of Confucius4 and the full open-sourcing of core models not only significantly lower barriers for developers in multimodal and speech synthesis fields but also demonstrate an ecological closed loop where underlying core technologies nurture upper-layer Agent matrices. Youdao hopes that, with the joint contributions of global developers and the open-source community, this full-modal large model ecosystem will unleash true productivity transformation across a wide range of industries.
Appendix: Open-source addresses:
"Confucius4" multimodal model: https://huggingface.co/netease-youdao/Confucius4
"Confucius4" TTS model: https://github.com/netease-youdao/Confucius4-TTS
Related article
 Cybersecurity Experts Criticize Guardrails on Anthropic’s Fable
Anthropic launched its newest model, Fable, on Tuesday, positioning it as a public, restricted iteration of its highly anticipated cybersecurity-focused model, Mythos.However, the limitations have sparked dissatisfaction among several cybersecurity r
Vbot VITA Power Raises Nearly 500 Million Yuan in Pre-A Funding, Begins Mass Delivery of First Embodied Intelligence Product
Vbot Weita Power, a pioneer in embodied intelligence, has secured nearly 500 million yuan in pre-A financing. Dongfang Jiafu, Huatai Zijin, and Fosun Ruizheng led the round, with additional backing from Shangqi Capital (SAIC Group) and existing share
Baidu Wenyin Unveils PaddleOCR-VL-1.6, Achieving 96.33% Accuracy and New SOTA in Document Parsing
Baidu has officially launched PaddleOCR-VL-1.6, a specialized variant of the ERNIE Large Model. In the authoritative OmnicDocBench v1.6 benchmark, it secured a 96.33% accuracy rate, outperforming leading models like Gemini-3-Pro, GPT-5.2, and GLM-OCR
Related Special Topic Recommendations
automation
 Top AI Agent Builders: Design Multi-Step Business Automations
2026 Latest Top-Rated Best AI Agent Builders for Creating Multi-Step Business Automations. This curated list features powerful, game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparisons, comprehensive rankings, and weekly updated insights to help you choose the perfect solution that boosts your productivity significantly. Explore now at XIX.AI to unlock your AI edge!
 11 tools
 xix.ai
Productivity
AI Task Planning Tools for Busy Professionals
2026 Latest Best Top-rated AI Task Planning Tools for Busy Professionals! XIX.AI has curated a powerful, game-changing collection of highly efficient tools that help users streamline workflows, boost productivity, and overcome daily scheduling challenges. Each option goes through rigorous real-world tests to ensure reliability. Get a free vs paid comparison and discover the perfect tool to unlock your AI edge. Explore now!
15 tools
xix.ai
chatbot
Top AI Customer Chatbots: Answer FAQs and Qualify Leads 24/7
2026 Latest Top-rated AI Customer Chatbots featured on this curated list are the best solutions for answering customer FAQs instantly and qualifying leads around the clock. XIX.AI has conducted rigorous real-world tests to deliver a detailed free vs paid comparison along with up-to-date rankings, helping you find a powerful game-changing tool that boosts productivity significantly. Explore now to Discover your perfect AI chatbot solution!
9 tools
xix.ai
Design & Art
AI Storyboard Generators for Ad Creative Teams
2026 Latest Best AI Storyboard Generators for Ad Creative Teams! XIX.AI has curated a top-rated list of powerful, game-changing tools that help teams create stunning visual content faster through real-world tests and rigorous weekly updated rankings. Enjoy a free vs paid comparison to find the perfect fit for your workflow. Explore now to unlock your AI edge in ad creation!
8 tools
xix.ai
chatbot
AI Knowledge Chatbot Tools for Internal Documentation
2026 Latest Best Top-rated AI Knowledge Chatbot Tools for Internal Documentation are here on XIX.AI! This curated list features powerful game-changing solutions that significantly boost productivity by helping teams quickly generate high-quality content, streamline documentation creation, and overcome common writing challenges. We conduct rigorous real-world tests and provide a weekly updated free vs paid comparison along with detailed rankings to help you find the must-try option that fits your needs best. Explore now to Discover your perfect tool!
12 tools
xix.ai
Text-to-speech
Best AI Text-to-Speech Tools: Create Natural Voiceovers for Videos
2026 Latest Best Top-Rated AI Text-to-Speech Tools Curated for Creating Natural Voiceovers in Videos. XIX.AI delivers powerful, game-changing solutions that boost writing efficiency and help you break through creation bottlenecks. We conduct real-world tests, offer free vs paid comparison, and update our rankings weekly. Must-try options are highlighted based on rigorous evaluations. Explore now to Discover your perfect tool for enhancing video quality.
9 tools
xix.ai

 Comments (1)
0/500
![WillGarcía]()
有道のZi Yue 4って、27Bパラメータで数学SOTA達成しつつ3秒で感情クローン?技術の進歩が速すぎて追いつけない。特にTTSエンジンのオープンソース化は開発者には朗報だけど、倫理面の規制が追いついてないのが心配だ。ただ、リアルタイムの音声合成精度が上がれば、アクセシビリティの向上に大きく貢献するはず。今後のアップデートに期待しつつも、深偽技術の悪用防止策がどうなるか注視したい。🤖✨
NetEase Youdao recently announced a comprehensive upgrade of its "Confucius4" large model to version 4.0. Now fully multimodal, Confucius4 supports integrated text, image, and audio interactions. Youdao also open-sourced its core multimodal and text-to-speech (TTS) models, while the translation model underwent a deep technical overhaul, delivering improvements in both quality and efficiency.
The multimodal model achieves SOTA in vision and mathematics, with superior performance on pure-text math problems
According to the announcement, the open-source Confucius4 multimodal model, with 27 billion parameters, has brought visual-input-based math capabilities to an industry-leading level (SOTA) in educational scenarios. Among models of similar scale, Confucius4 excels at handling advanced visual math and physics problems that incorporate charts. It also shows significant improvement on Chinese pure-text math problems, achieving an accuracy of 81.4%, which is industry-leading.
▲ Confucius4 achieves best-in-class results on multiple visual math benchmarks among models of the same scale
Image source: https://huggingface.co/netease-youdao/Confucius4
A more critical breakthrough lies in practical cost-effectiveness. According to relevant officials, the new model employs a refined reasoning chain reconstruction scheme. By aggregating a large volume of high-quality, concise reasoning samples for deep optimization, it compresses the output length of the reasoning chain by 43.2%.
This means it can deliver answers faster with fewer tokens and shorter reasoning paths, significantly reducing inference costs in real-world business scenarios for enterprises and developers.
▲ Confucius4 significantly reduces output tokens on multiple visual math benchmarks
Image source: https://huggingface.co/netease-youdao/Confucius4
Additionally, the Confucius4 research team deeply optimized the model for real-world homework, exams, and problem-solving scenarios faced by Chinese students. This enables it to address authentic learning challenges, making it a more empathetic digital assistant.
Open-source TTS: supports 14 languages, clones original voice in 3 seconds with no accent issues across languages
Alongside the multimodal model, the speech synthesis (TTS) engine was also open-sourced. Built on a cutting-edge "speech encoder + LLM" architecture, it offers developers and content creators zero-shot, low-barrier voice cloning and emotional synthesis capabilities.
Currently, it fully supports 14 languages: Chinese, English, Japanese, Korean, German, French, Spanish, Indonesian, Italian, Thai, Portuguese, Russian, Malay, and Vietnamese. The system can naturally transfer a speaker's voice across different languages without additional training, maintaining voice consistency while ensuring the synthesized results sound native and fluent, with no accent leakage during cross-language cloning.
For voice cloning, Confucius4 achieves full "upload and clone" support. Users simply provide any audio material, and the system replicates the original voice within three seconds. According to the announcement, the engine's accuracy on cloning tasks exceeds 97%, and the similarity between the cloned voice and the original voice is over 85%. It preserves the speaker's unique vocal characteristics while accurately reproducing their emotional tone, with comprehensive capabilities that rank among the top in the field.
Furthermore, this open-source model demonstrates strong robustness in real multilingual scenarios. It can handle various synthesis needs, including daily conversations, news broadcasts, corporate promotions, and complex emotional expressions.
Translation model quality upgraded comprehensively, with 80% faster inference speed
As one of Youdao's most deeply rooted technological assets, the translation model also received significant technical upgrades in this update, further enhancing its performance on translation tasks.
Regarding data, the Confucius team collected and cleaned billions of multilingual items and hired professionals with TEM-8 certification for multidimensional manual evaluation, ensuring high-quality corpora from the start.
On the algorithmic side, the model uses an innovative "multi-expert OPD" mode, adopting a smarter "soft approach" to leverage the strengths of various experts. It also introduces format rewards and language detection mechanisms through reinforcement learning, effectively resolving common issues like out-of-context translations and mixed-language outputs in machine translation.
To meet the demands of high-frequency, high-concurrency industrial applications, the updated translation model is equipped with an efficient acceleration mechanism that directly boosts overall inference speed by 80%. Combined with a customized solution of automated large model evaluation and random manual sampling, the new generation translation model demonstrates extremely high standards of speed and quality across multiple scenarios, including text, image, and document translation.
Reflecting on Youdao's journey in AI, from the initial launch of Confucius as the first education-focused large model, introducing the "virtual speaking coach Hi Echo" that overturned traditional oral practice methods, to the comprehensive integration of Confucius 2.0 and 3.0 into software and hardware ecosystems, Youdao has consistently led AI empowerment in real-world scenarios. In 2026, Youdao accelerated AI application with a series of AI Agent products such as LobsterAI, Youdao Treasure, Youdao Conference Agent, and Thinkflow, realizing a forward-looking full-scenario AI Agent matrix.
The upgrade of Confucius4 and the full open-sourcing of core models not only significantly lower barriers for developers in multimodal and speech synthesis fields but also demonstrate an ecological closed loop where underlying core technologies nurture upper-layer Agent matrices. Youdao hopes that, with the joint contributions of global developers and the open-source community, this full-modal large model ecosystem will unleash true productivity transformation across a wide range of industries.
Appendix: Open-source addresses:
"Confucius4" multimodal model: https://huggingface.co/netease-youdao/Confucius4
"Confucius4" TTS model: https://github.com/netease-youdao/Confucius4-TTS








 Cybersecurity Experts Criticize Guardrails on Anthropic’s Fable
Anthropic launched its newest model, Fable, on Tuesday, positioning it as a public, restricted iteration of its highly anticipated cybersecurity-focused model, Mythos.However, the limitations have sparked dissatisfaction among several cybersecurity r
 Vbot VITA Power Raises Nearly 500 Million Yuan in Pre-A Funding, Begins Mass Delivery of First Embodied Intelligence Product
Vbot Weita Power, a pioneer in embodied intelligence, has secured nearly 500 million yuan in pre-A financing. Dongfang Jiafu, Huatai Zijin, and Fosun Ruizheng led the round, with additional backing from Shangqi Capital (SAIC Group) and existing share
 Baidu Wenyin Unveils PaddleOCR-VL-1.6, Achieving 96.33% Accuracy and New SOTA in Document Parsing
Baidu has officially launched PaddleOCR-VL-1.6, a specialized variant of the ERNIE Large Model. In the authoritative OmnicDocBench v1.6 benchmark, it secured a 96.33% accuracy rate, outperforming leading models like Gemini-3-Pro, GPT-5.2, and GLM-OCR
2026 Latest Top-Rated Best AI Agent Builders for Creating Multi-Step Business Automations. This curated list features powerful, game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparisons, comprehensive rankings, and weekly updated insights to help you choose the perfect solution that boosts your productivity significantly. Explore now at XIX.AI to unlock your AI edge!
11 tools
xix.ai
2026 Latest Best Top-rated AI Task Planning Tools for Busy Professionals! XIX.AI has curated a powerful, game-changing collection of highly efficient tools that help users streamline workflows, boost productivity, and overcome daily scheduling challenges. Each option goes through rigorous real-world tests to ensure reliability. Get a free vs paid comparison and discover the perfect tool to unlock your AI edge. Explore now!
15 tools
xix.ai
2026 Latest Top-rated AI Customer Chatbots featured on this curated list are the best solutions for answering customer FAQs instantly and qualifying leads around the clock. XIX.AI has conducted rigorous real-world tests to deliver a detailed free vs paid comparison along with up-to-date rankings, helping you find a powerful game-changing tool that boosts productivity significantly. Explore now to Discover your perfect AI chatbot solution!
9 tools
xix.ai
2026 Latest Best AI Storyboard Generators for Ad Creative Teams! XIX.AI has curated a top-rated list of powerful, game-changing tools that help teams create stunning visual content faster through real-world tests and rigorous weekly updated rankings. Enjoy a free vs paid comparison to find the perfect fit for your workflow. Explore now to unlock your AI edge in ad creation!
8 tools
xix.ai
2026 Latest Best Top-rated AI Knowledge Chatbot Tools for Internal Documentation are here on XIX.AI! This curated list features powerful game-changing solutions that significantly boost productivity by helping teams quickly generate high-quality content, streamline documentation creation, and overcome common writing challenges. We conduct rigorous real-world tests and provide a weekly updated free vs paid comparison along with detailed rankings to help you find the must-try option that fits your needs best. Explore now to Discover your perfect tool!
12 tools
xix.ai
2026 Latest Best Top-Rated AI Text-to-Speech Tools Curated for Creating Natural Voiceovers in Videos. XIX.AI delivers powerful, game-changing solutions that boost writing efficiency and help you break through creation bottlenecks. We conduct real-world tests, offer free vs paid comparison, and update our rankings weekly. Must-try options are highlighted based on rigorous evaluations. Explore now to Discover your perfect tool for enhancing video quality.
9 tools
xix.ai

有道のZi Yue 4って、27Bパラメータで数学SOTA達成しつつ3秒で感情クローン?技術の進歩が速すぎて追いつけない。特にTTSエンジンのオープンソース化は開発者には朗報だけど、倫理面の規制が追いついてないのが心配だ。ただ、リアルタイムの音声合成精度が上がれば、アクセシビリティの向上に大きく貢献するはず。今後のアップデートに期待しつつも、深偽技術の悪用防止策がどうなるか注視したい。🤖✨












