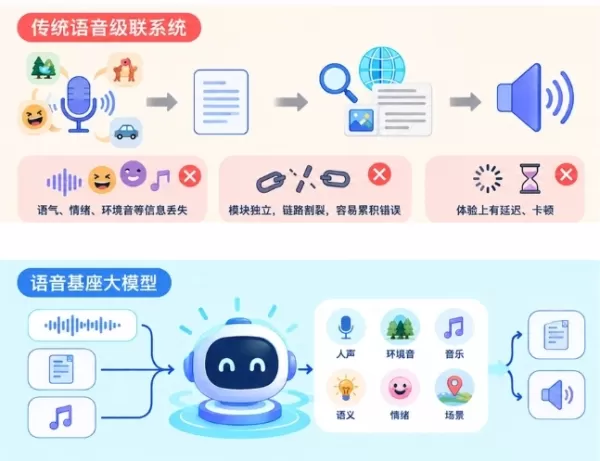
iFLYTEK released Spark-Audio-1.0-Preview, a speech foundation model trained on fully domestic computing power. Unlike traditional cascading systems that convert speech to text, this model directly understands audio, capturing semantics, emotions, and ambient sounds. Built with a 0.65B audio encoder and 30B-A3B LLM, it supports 99 languages and 202 dialects. It outperforms competitors in noisy scenarios and achieves SOTA in Chinese-English recognition. The model enables tasks like sentiment analysis and complex Q&A, marking a shift from transcription to true audio understanding. API access will follow via the iFLYTEK Open Platform.
By clicking "Accept All Cookies", you agree to the storing of cookies on your device to enhance site navigation, analyze site usage, and assist in our marketing efforts.Privacy Policy Notice
When you visit any website, it may store or retrieve information on your browser, mostly in the form of cookies. This information might be about you, your preferences or your device and is mostly used to make the site work as you expect it to. The information does not usually directly identify you, but it can give you a more personalized web experience. Because we respect your right to privacy, you can choose not to allow some types of cookies. Click on the different category headings to find out more and change our default settings.However, blocking some types of cookies may impact your experience of the site and the services we are able to offer. Privacy PolicyStatement
Manage Preferences
Strictly Necessary Cookie
Always Active
These cookies are necessary for the website to function and cannot be switched off in our systems. They are usually only set in response to actions made by you which amount to a request for services, such as setting your privacy preferences, logging in or filling in forms. You can set your browser to block or alert you about these cookies, but some parts of the site will not then work. These cookies do not store any personally identifiable information.