option
Home
Flash News
Content
ScottRoberts
ScottRoberts
August 21, 2026

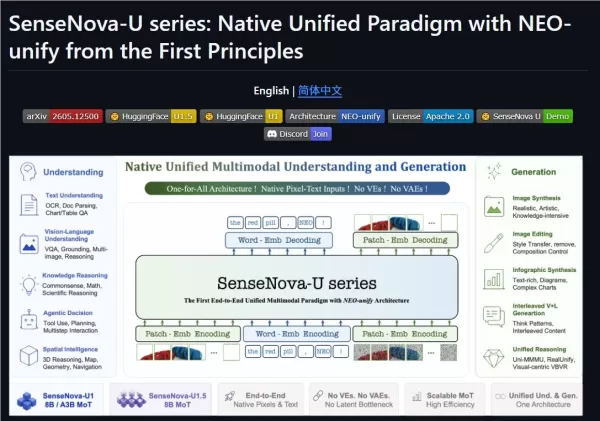
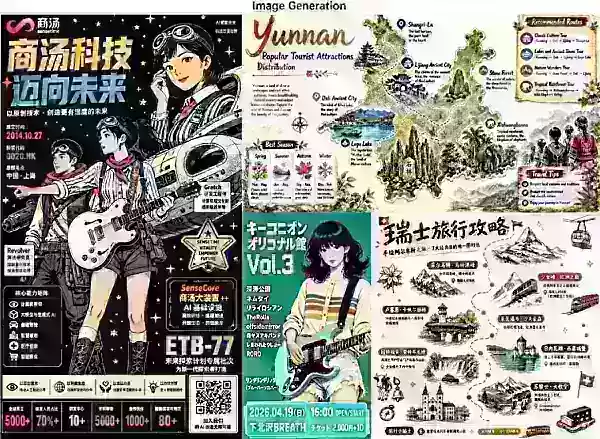
SenseTime has released SenseNova U1.5Lite, a new open-source lightweight unified multimodal large model with 8B parameters. It outperforms models of similar size in core visual tasks and matches performance of larger commercial models in complex layout and text rendering scenarios. The model supports context lengths of 3 to 4K, enabling it to handle multiple constraints simultaneously and improving task stability. It delivers higher quality visual generation with improved composition, color, realism and details, avoiding the issue of locally correct but overall incomplete results from traditional models. Its native image editing capabilities better preserve subject identity, spatial structure and layout while boosting performance in local modifications, element replacement, text refinement and multi-reference editing. The model also excels at handling text and complex layouts, supporting Chinese and English content, posters, infographics and multi-text formatting to achieve complete visual outputs. It offers precise editing options via Bounding Box, Visual Marker and reference images, and supports native 4K high-resolution generation that retains fine textures, small texts and lighting effects. The project is available at https://github.com/OpenSenseNova/SenseNova-U1
SenseTime has released SenseNova U1.5Lite, a new open-source lightweight unified multimodal large model with 8B parameters. It outperforms models of similar size in core visual tasks and matches performance of larger commercial models in complex layout and text rendering scenarios. The model supports context lengths of 3 to 4K, enabling it to handle multiple constraints simultaneously and improving task stability. It delivers higher quality visual generation with improved composition, color, realism and details, avoiding the issue of locally correct but overall incomplete results from traditional models. Its native image editing capabilities better preserve subject identity, spatial structure and layout while boosting performance in local modifications, element replacement, text refinement and multi-reference editing. The model also excels at handling text and complex layouts, supporting Chinese and English content, posters, infographics and multi-text formatting to achieve complete visual outputs. It offers precise editing options via Bounding Box, Visual Marker and reference images, and supports native 4K high-resolution generation that retains fine textures, small texts and lighting effects. The project is available at https://github.com/OpenSenseNova/SenseNova-U1 SenseTime has released SenseNova U1.5Lite, a new open-source lightweight unified multimodal large model with 8B parameters. It outperforms models of similar size in core visual tasks and matches performance of larger commercial models in complex layout and text rendering scenarios. The model supports context lengths of 3 to 4K, enabling it to handle multiple constraints simultaneously and improving task stability. It delivers higher quality visual generation with improved composition, color, realism and details, avoiding the issue of locally correct but overall incomplete results from traditional models. Its native image editing capabilities better preserve subject identity, spatial structure and layout while boosting performance in local modifications, element replacement, text refinement and multi-reference editing. The model also excels at handling text and complex layouts, supporting Chinese and English content, posters, infographics and multi-text formatting to achieve complete visual outputs. It offers precise editing options via Bounding Box, Visual Marker and reference images, and supports native 4K high-resolution generation that retains fine textures, small texts and lighting effects. The project is available at https://github.com/OpenSenseNova/SenseNova-U1
Comments (0)
0/300
OR