
option
Home
Flash News
Content
BillyThomas
BillyThomas
July 17, 2026

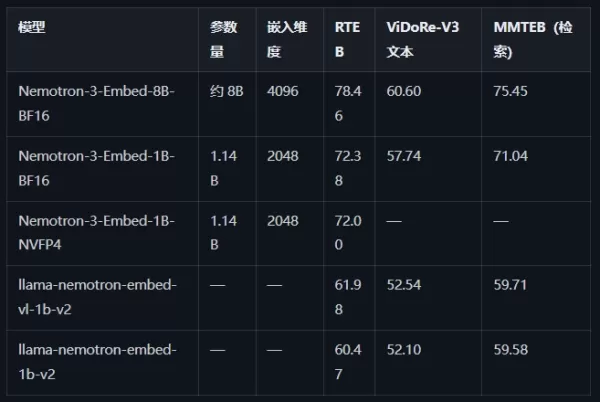
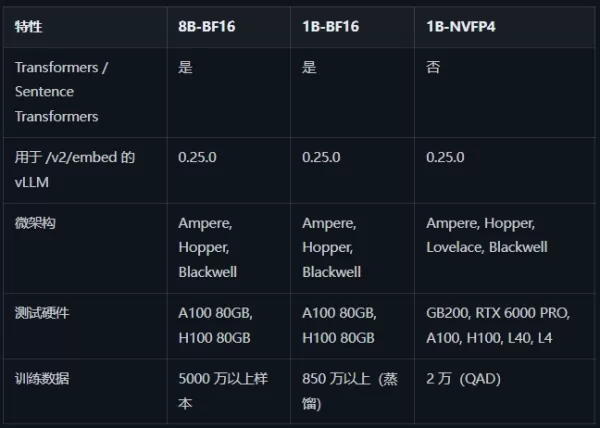
NVIDIA released the Nemotron-3-Embed series of embedding models for production RAG, code retrieval, and agent memory. The 8B BF16 version ranks first on the RTEB benchmark with 78.46 NDCG@10. The series includes 1B BF16 and 1B NVFP4 (4-bit) versions, all based on Mistral architecture, supporting 34 languages and 32K tokens. The 1B models were created via pruning and knowledge distillation. The NVFP4 version retains 99.5% precision with 2x throughput on Blackwell. It supports vLLM deployment; BF16 versions support Transformers and Sentence Transformers.
NVIDIA released the Nemotron-3-Embed series of embedding models for production RAG, code retrieval, and agent memory. The 8B BF16 version ranks first on the RTEB benchmark with 78.46 NDCG@10. The series includes 1B BF16 and 1B NVFP4 (4-bit) versions, all based on Mistral architecture, supporting 34 languages and 32K tokens. The 1B models were created via pruning and knowledge distillation. The NVFP4 version retains 99.5% precision with 2x throughput on Blackwell. It supports vLLM deployment; BF16 versions support Transformers and Sentence Transformers. NVIDIA released the Nemotron-3-Embed series of embedding models for production RAG, code retrieval, and agent memory. The 8B BF16 version ranks first on the RTEB benchmark with 78.46 NDCG@10. The series includes 1B BF16 and 1B NVFP4 (4-bit) versions, all based on Mistral architecture, supporting 34 languages and 32K tokens. The 1B models were created via pruning and knowledge distillation. The NVFP4 version retains 99.5% precision with 2x throughput on Blackwell. It supports vLLM deployment; BF16 versions support Transformers and Sentence Transformers.
Comments (0)
0/300
OR