


 Home
Qwen3.8-LiveTranslate Launches Real-time Translation Model with 2.3s Delay
Qwen3.8-LiveTranslate, Alibaba Qwen’s latest real-time speech translation model, redefines simultaneous interpretation through its unified Interleave architecture. This innovation boosts accuracy, fluency, and conciseness, cutting average latency per character (LAAL) from 2.8 to 2.3 seconds—a critical 0.5-second improvement that ensures a natural listening experience in a field where even a slight delay can disrupt flow.
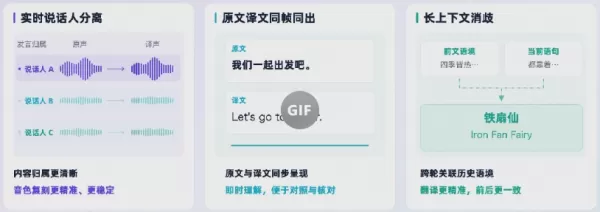
Expanding on support for 60 languages, the updated model introduces three practical enhancements for real-time interpretation. First, it supports real-time speaker separation, accurately assigning each sentence to the correct speaker while maintaining stable voice cloning, thus preventing cross-talk or speaker confusion. Second, it displays source and translated text side-by-side, enabling listeners to follow along visually as they hear the translation. Third, it enhances long-context disambiguation, allowing the model to leverage prior context for improved accuracy—particularly for names and specialized terminology, which are common error points.
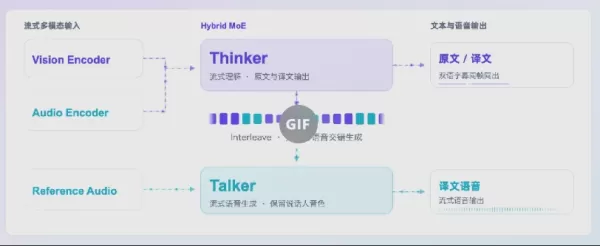
At its core, Qwen3.8-LiveTranslate employs a Thinker–Talker dual-module design built on Hybrid MoE. The Interleave mechanism seamlessly integrates streaming comprehension, text generation, and speech synthesis into a single pipeline. The Thinker processes video, audio, source text, and translation outputs into a unified causal sequence, ordering them chronologically to produce end-to-end results that simultaneously handle “understanding” and “translation.” The Talker then converts the translated text, guided by the original audio, into speech that preserves the source speaker’s voice identity.
Related article
 OpenAI Unveils Privacy Filter for 128K Context with Eight Recognition Modes
OpenAI has introduced Privacy Filter, a state-of-the-art Personal Identifiable Information (PII) anonymization model. Now available under the Apache 2.0 license on Hugging Face and GitHub, this tool empowers developers with a local, highly customizab
NewCore raises $66M to equip AI agents with identities as they transition into employee roles
Cybersecurity startup NewCore has officially launched from stealth, securing $66 million in funding on Monday. The company aims to address a critical challenge that many organizations will soon encounter as they integrate AI agents: how to authentica
Microsoft and Mistral Ink Multi-Billion-Dollar European AI Partnership
At the core of this collaboration lies a multi-billion-dollar pact designed to bolster artificial intelligence infrastructure across Europe. Credit: MicrosoftMicrosoft and Mistral, a leading French artificial intelligence firm, have unveiled a multi-
Related Special Topic Recommendations
Marketing
 AI Landing Page Copy Tools for SaaS A/B Tests, Pricing Pages, and Demo Conversion
2026 Latest Best AI Landing Page Copy Tools for SaaS A/B Tests, Pricing Pages, and Demo Conversion are here on XIX.AI. This curated list of top-rated tools offers powerful game-changing solutions to boost content quality, improve writing efficiency, and enhance overall productivity. We conduct real-world tests and provide a free vs paid comparison along with weekly updated rankings. Must-try options help you break through creation bottlenecks. Explore now to discover your perfect tool and unlock your AI edge!
 8 tools
 xix.ai
Finance
Excel AI Budget Forecasting Tools for Cash Flow Planning and Expense Control
2026 Latest Best Excel AI tools for cash flow planning and expense control are here on XIX.AI’s top-rated curated list. These powerful game-changing solutions help you boost productivity significantly through real-world tests and rigorous rankings. Get a free vs paid comparison to find the perfect fit for your needs. Explore now to unlock your AI edge in financial management.
9 tools
xix.ai
Prompt
AI Prompt Management Tools for Teams
2026 Latest Best Top-Rated AI Prompt Management Tools for Teams are curated by XIX.AI here. This weekly updated guide features powerful game-changing solutions that boost team productivity significantly through real-world tests and detailed rankings. Get a free vs paid comparison to help you choose the perfect tool. Explore now to Unlock your AI edge.
9 tools
xix.ai
Music composition
AI Lyric Idea Tools for Music Composition
2026 Latest Best Top-rated AI Lyric Idea Tools for Music Composition are here on XIX.AI! This curated collection features powerful game-changing options that go through real-world tests to deliver high-quality lyric concepts fast, helping users boost creativity and streamline their music creation process. Get a free vs paid comparison overview too. Explore now to Discover your perfect tool!
16 tools
xix.ai
Comic Creation
AI Character Sheet Tools for Comic Worldbuilding
2026 Latest Best Top-Rated AI Character Sheet Tools for Comic Worldbuilding are here on XIX.AI! This curated list features powerful, game-changing options that have undergone rigorous real-world tests. You’ll find a free vs paid comparison along with weekly updated rankings to help you discover the must-try tools that boost your creativity and streamline worldbuilding tasks. Explore now to Unlock your AI edge!
13 tools
xix.ai
automation
n8n AI Automation Tools for Internal Ops, Data Sync, and Multi-Step Agent Flows
2026 Latest Best n8n AI Automation Tools for Internal Ops, Data Sync, and Multi-Step Agent Flows are here! XIX.AI has curated a top-rated list of powerful game-changing tools that boost productivity across all work tasks. Each entry goes through rigorous real-world tests to ensure reliability, with detailed free vs paid comparison and weekly updated rankings. Must-try options help you unlock your AI edge and streamline workflows effortlessly. Explore now to discover your perfect tool!
11 tools
xix.ai

 Comments (0)
0/500
Qwen3.8-LiveTranslate, Alibaba Qwen’s latest real-time speech translation model, redefines simultaneous interpretation through its unified Interleave architecture. This innovation boosts accuracy, fluency, and conciseness, cutting average latency per character (LAAL) from 2.8 to 2.3 seconds—a critical 0.5-second improvement that ensures a natural listening experience in a field where even a slight delay can disrupt flow.
Expanding on support for 60 languages, the updated model introduces three practical enhancements for real-time interpretation. First, it supports real-time speaker separation, accurately assigning each sentence to the correct speaker while maintaining stable voice cloning, thus preventing cross-talk or speaker confusion. Second, it displays source and translated text side-by-side, enabling listeners to follow along visually as they hear the translation. Third, it enhances long-context disambiguation, allowing the model to leverage prior context for improved accuracy—particularly for names and specialized terminology, which are common error points.
At its core, Qwen3.8-LiveTranslate employs a Thinker–Talker dual-module design built on Hybrid MoE. The Interleave mechanism seamlessly integrates streaming comprehension, text generation, and speech synthesis into a single pipeline. The Thinker processes video, audio, source text, and translation outputs into a unified causal sequence, ordering them chronologically to produce end-to-end results that simultaneously handle “understanding” and “translation.” The Talker then converts the translated text, guided by the original audio, into speech that preserves the source speaker’s voice identity.








 OpenAI Unveils Privacy Filter for 128K Context with Eight Recognition Modes
OpenAI has introduced Privacy Filter, a state-of-the-art Personal Identifiable Information (PII) anonymization model. Now available under the Apache 2.0 license on Hugging Face and GitHub, this tool empowers developers with a local, highly customizab
 NewCore raises $66M to equip AI agents with identities as they transition into employee roles
Cybersecurity startup NewCore has officially launched from stealth, securing $66 million in funding on Monday. The company aims to address a critical challenge that many organizations will soon encounter as they integrate AI agents: how to authentica
 Microsoft and Mistral Ink Multi-Billion-Dollar European AI Partnership
At the core of this collaboration lies a multi-billion-dollar pact designed to bolster artificial intelligence infrastructure across Europe. Credit: MicrosoftMicrosoft and Mistral, a leading French artificial intelligence firm, have unveiled a multi-

2026 Latest Best AI Landing Page Copy Tools for SaaS A/B Tests, Pricing Pages, and Demo Conversion are here on XIX.AI. This curated list of top-rated tools offers powerful game-changing solutions to boost content quality, improve writing efficiency, and enhance overall productivity. We conduct real-world tests and provide a free vs paid comparison along with weekly updated rankings. Must-try options help you break through creation bottlenecks. Explore now to discover your perfect tool and unlock your AI edge!
8 tools
xix.ai

2026 Latest Best Excel AI tools for cash flow planning and expense control are here on XIX.AI’s top-rated curated list. These powerful game-changing solutions help you boost productivity significantly through real-world tests and rigorous rankings. Get a free vs paid comparison to find the perfect fit for your needs. Explore now to unlock your AI edge in financial management.
9 tools
xix.ai

2026 Latest Best Top-Rated AI Prompt Management Tools for Teams are curated by XIX.AI here. This weekly updated guide features powerful game-changing solutions that boost team productivity significantly through real-world tests and detailed rankings. Get a free vs paid comparison to help you choose the perfect tool. Explore now to Unlock your AI edge.
9 tools
xix.ai

2026 Latest Best Top-rated AI Lyric Idea Tools for Music Composition are here on XIX.AI! This curated collection features powerful game-changing options that go through real-world tests to deliver high-quality lyric concepts fast, helping users boost creativity and streamline their music creation process. Get a free vs paid comparison overview too. Explore now to Discover your perfect tool!
16 tools
xix.ai
2026 Latest Best Top-Rated AI Character Sheet Tools for Comic Worldbuilding are here on XIX.AI! This curated list features powerful, game-changing options that have undergone rigorous real-world tests. You’ll find a free vs paid comparison along with weekly updated rankings to help you discover the must-try tools that boost your creativity and streamline worldbuilding tasks. Explore now to Unlock your AI edge!
13 tools
xix.ai
2026 Latest Best n8n AI Automation Tools for Internal Ops, Data Sync, and Multi-Step Agent Flows are here! XIX.AI has curated a top-rated list of powerful game-changing tools that boost productivity across all work tasks. Each entry goes through rigorous real-world tests to ensure reliability, with detailed free vs paid comparison and weekly updated rankings. Must-try options help you unlock your AI edge and streamline workflows effortlessly. Explore now to discover your perfect tool!
11 tools
xix.ai












