


 Home
Google TurboQuant Shrinks Large Models Sixfold, Easing Memory Strain
Memory bottlenecks have long been a major performance hurdle in the reasoning process of large language models (LLMs). When AI handles lengthy texts or generates complex responses, the KV cache (Key-Value Cache) — a form of working memory — quickly expands, leading to slowdowns or crashes. To address this, Google Research introduced TurboQuant, a new AI memory compression technology, on March 26, 2026.
The key breakthrough of TurboQuant is its ability to cut cache memory usage to one-sixth of the original size without compromising model accuracy, while delivering an impressive eightfold boost in inference speed.
Breaking the KV Cache Bottleneck: Smarter Memory, Faster AI
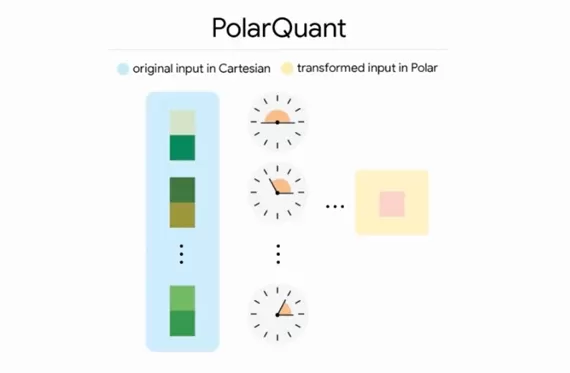
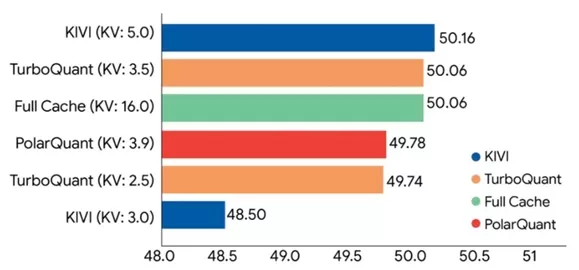
TurboQuant represents a new milestone in AI operational efficiency. It employs an advanced vector quantization scheme that combines the PolarQuant quantization method with the QJL optimization approach. In rigorous tests on popular open-source models like Gemma and Mistral, TurboQuant showed robust adaptability, efficiently compressing key-value caches to 3 bits without requiring any pre-training or fine-tuning. In the "needle in a haystack" long-context test, which simulates realistic and complex scenarios, TurboQuant achieved zero precision loss — meaning that even after significant size reduction, AI retains its original intelligence and memory accuracy.
Peak Hardware Efficiency: 8x Speedup on H100 Accelerators
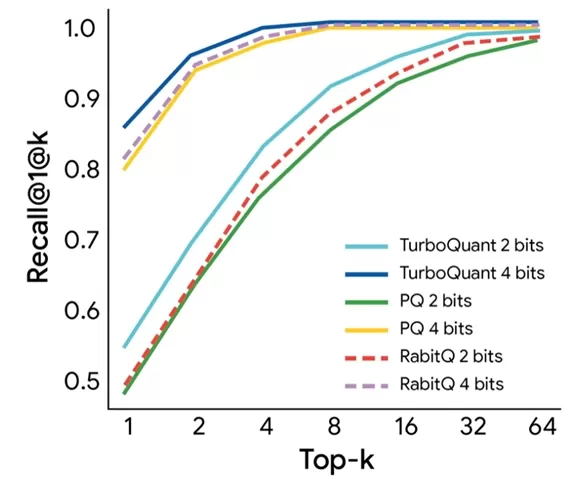
Beyond memory reduction, TurboQuant also excels in hardware utilization. On high-performance H100 GPU accelerators, the 4-bit optimized TurboQuant runs 8 times faster than the unquantized 32-bit baseline.
Related article
 Google Unveils Veo 3.1 Lite Video Mode, Granting Ultra Subscribers Unlimited Generation
Google has introduced a new video generation mode, "Veo 3.1 - Lite [Low Priority]," exclusively for Ultra subscribers to boost creative output and cost efficiency. This mode’s key advantage is that it operates without consuming additional subscriptio
ChatGPT Deep Integration Unlocks 300,000 Movies and TV Shows via Conversation
As streaming services saturate the market with endless content, helping users cut through the noise to find what they actually want has emerged as a critical industry hurdle.On April 9, major streaming providers officially announced the integration o
How to fix Core Web Vitals for better SEO ranking
Transform your video editing workflow with AI-powered transcriptsTable of Contents:IntroductionKey Advantages of Automated TranscriptionEnsuring Accuracy and Refining OutputLeveraging Search Capabilities in TranscriptsSeamless Import of Existing File
Related Special Topic Recommendations
Design & Art
 Top AI Illustration Tools: Create Editorial Scenes and Cover Art Faster
2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
 10 tools
 xix.ai
Education and Learning
Top AI Tutors for Exam Prep: Practice Math, Science, and English
2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai
Finance
AI Budget Planning Tools for Personal Money Management
2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai
Health & Wellness
AI Sleep Tracking Assistants: Improve Recovery with Better Bedtime Habits
2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai
Data Analysis
AI SQL Copilots for Product and Revenue Analytics
2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai
Education and Learning
Best AI Homework Helpers That Teach: Learn Concepts, Not Just Answers
2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai

 Comments (0)
0/500
Memory bottlenecks have long been a major performance hurdle in the reasoning process of large language models (LLMs). When AI handles lengthy texts or generates complex responses, the KV cache (Key-Value Cache) — a form of working memory — quickly expands, leading to slowdowns or crashes. To address this, Google Research introduced TurboQuant, a new AI memory compression technology, on March 26, 2026.
The key breakthrough of TurboQuant is its ability to cut cache memory usage to one-sixth of the original size without compromising model accuracy, while delivering an impressive eightfold boost in inference speed.
Breaking the KV Cache Bottleneck: Smarter Memory, Faster AI
TurboQuant represents a new milestone in AI operational efficiency. It employs an advanced vector quantization scheme that combines the PolarQuant quantization method with the QJL optimization approach. In rigorous tests on popular open-source models like Gemma and Mistral, TurboQuant showed robust adaptability, efficiently compressing key-value caches to 3 bits without requiring any pre-training or fine-tuning. In the "needle in a haystack" long-context test, which simulates realistic and complex scenarios, TurboQuant achieved zero precision loss — meaning that even after significant size reduction, AI retains its original intelligence and memory accuracy.
Peak Hardware Efficiency: 8x Speedup on H100 Accelerators
Beyond memory reduction, TurboQuant also excels in hardware utilization. On high-performance H100 GPU accelerators, the 4-bit optimized TurboQuant runs 8 times faster than the unquantized 32-bit baseline.








 Google Unveils Veo 3.1 Lite Video Mode, Granting Ultra Subscribers Unlimited Generation
Google has introduced a new video generation mode, "Veo 3.1 - Lite [Low Priority]," exclusively for Ultra subscribers to boost creative output and cost efficiency. This mode’s key advantage is that it operates without consuming additional subscriptio
 ChatGPT Deep Integration Unlocks 300,000 Movies and TV Shows via Conversation
As streaming services saturate the market with endless content, helping users cut through the noise to find what they actually want has emerged as a critical industry hurdle.On April 9, major streaming providers officially announced the integration o
 How to fix Core Web Vitals for better SEO ranking
Transform your video editing workflow with AI-powered transcriptsTable of Contents:IntroductionKey Advantages of Automated TranscriptionEnsuring Accuracy and Refining OutputLeveraging Search Capabilities in TranscriptsSeamless Import of Existing File

2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
10 tools
xix.ai

2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai

2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai

2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai












