


 Home
Alibaba Unveils Qwen3.5-Omni, Delivering Top-Tier Cross-Modal Performance
China’s leading AI models are rapidly evolving from followers to pioneers in multimodal interaction.
On March 30, Alibaba unveiled the next-generation multimodal large model, Qwen3.5-Omni. Leveraging a hybrid attention MoE architecture, this model enables seamless input and output across images, videos, audio, and text, positioning domestic large models at the global forefront of audio-visual interaction.
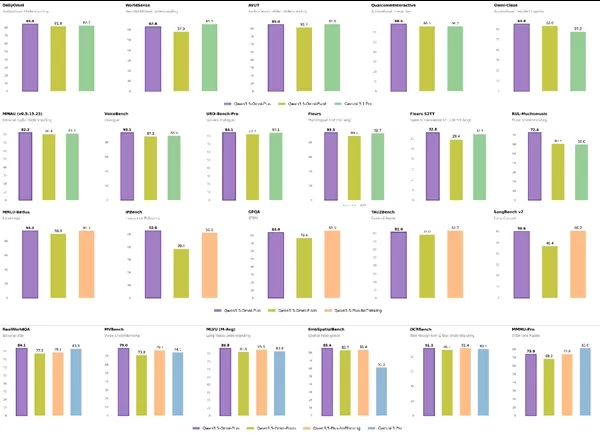
Comprehensive Capability: 215 Tasks Mastered, Outperforming Gemini
In key metrics measuring the overall strength of large models, Qwen3.5-Omni has demonstrated exceptional performance:
SOTA Leadership: Across 215 test cases covering audio-video understanding, recognition, and interaction, the model achieved state-of-the-art (SOTA) results.
Superior Performance: In benchmarks like DailyOmni and QualcommInteractive, which focus on audio-visual interaction, its scores significantly surpassed Google’s Gemini-3.1Pro.
Robust Noise Resistance: In the WenetSpeech test conducted in noisy environments, its recognition accuracy was remarkably high, with an error rate far lower than that of competitors.
Interactive Innovation: 113 Languages Supported and "Speak-to-Code" Programming
Qwen3.5-Omni is not only smarter but also adept at understanding "dialects" and "code":
Language Versatility: It supports the recognition of 113 languages and dialects, accurately handling rare languages such as Maori and Hainan dialect.
Vibe Coding Evolution: It ushers in a new era of audio-video programming. Users simply need to open the camera and describe their requirements, and the model can directly generate product prototype interfaces with complex UI, truly achieving "what you say is what you get."
Productivity Boost: 10-Hour Audio Long-Term Understanding
For professional fields, the new model offers powerful structured processing capabilities:
Deep Video Analysis: It can finely decompose the main subject of the image, relationships between people, and emotional fluctuations.
Automatic Segmentation: It supports over 10 hours of audio input and can automatically complete video chapter segmentation and timestamp annotation, significantly improving content creation efficiency.
Inclusive Ecosystem: Price is Just One-Tenth of Gemini
The Alibaba Cloud Bailian platform has simultaneously launched three APIs: Plus, Flash, and Light, aiming to provide the most cost-effective solution for enterprises:
Extremely Low Cost: The input cost per million Tokens is less than 0.8 yuan, costing less than one-tenth of Gemini-3.1Pro.
Market Leadership: Currently, Qwen has served over one million customers and remains the top choice in the enterprise-level large model call market in China.
Conclusion: From "Understanding Text" to "Perceiving the World"
The release of Qwen3.5-Omni
Related article
 Zhou Shen Unveils Moon Chronicle, Explicitly Banning AI Training and Voice Cloning
On April 1st, acclaimed Chinese artist Zhou Shen launched "Yue Zhi Ji," the theme song for the historical fantasy series "Yue Lin Qi Ji." He embedded a clear copyright notice in the track’s prelude and lyrics, explicitly banning its use for Artificia
Anthropic admits its AI models breached three firms during security tests
Anthropic announced Thursday that an internal probe revealed three separate incidents where its AI model, Claude, breached the systems of three organizations during cybersecurity assessments. This disclosure follows closely on the heels of OpenAI’s r
Meitu Unveils RoboNeo AI Agent Powered by Alibaba’s HappyHorse Model, Marking a Leap in Video Creation
On April 28, RoboNeo, an AI agent by Meitu Company, announced the integration of HappyHorse, a multimodal video generation model from Alibaba's ATH Innovation Division. Leveraging Seedance 2.0, RoboNeo has significantly enhanced product video creatio
Related Special Topic Recommendations
Design & Art
 Top AI Illustration Tools: Create Editorial Scenes and Cover Art Faster
2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
 10 tools
 xix.ai
Education and Learning
Top AI Tutors for Exam Prep: Practice Math, Science, and English
2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai
Finance
AI Budget Planning Tools for Personal Money Management
2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai
Health & Wellness
AI Sleep Tracking Assistants: Improve Recovery with Better Bedtime Habits
2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai
Data Analysis
AI SQL Copilots for Product and Revenue Analytics
2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai
Education and Learning
Best AI Homework Helpers That Teach: Learn Concepts, Not Just Answers
2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai

 Comments (0)
0/500
China’s leading AI models are rapidly evolving from followers to pioneers in multimodal interaction.
On March 30, Alibaba unveiled the next-generation multimodal large model, Qwen3.5-Omni. Leveraging a hybrid attention MoE architecture, this model enables seamless input and output across images, videos, audio, and text, positioning domestic large models at the global forefront of audio-visual interaction.
Comprehensive Capability: 215 Tasks Mastered, Outperforming Gemini
In key metrics measuring the overall strength of large models, Qwen3.5-Omni has demonstrated exceptional performance:
SOTA Leadership: Across 215 test cases covering audio-video understanding, recognition, and interaction, the model achieved state-of-the-art (SOTA) results.
Superior Performance: In benchmarks like DailyOmni and QualcommInteractive, which focus on audio-visual interaction, its scores significantly surpassed Google’s Gemini-3.1Pro.
Robust Noise Resistance: In the WenetSpeech test conducted in noisy environments, its recognition accuracy was remarkably high, with an error rate far lower than that of competitors.
Interactive Innovation: 113 Languages Supported and "Speak-to-Code" Programming
Qwen3.5-Omni is not only smarter but also adept at understanding "dialects" and "code":
Language Versatility: It supports the recognition of 113 languages and dialects, accurately handling rare languages such as Maori and Hainan dialect.
Vibe Coding Evolution: It ushers in a new era of audio-video programming. Users simply need to open the camera and describe their requirements, and the model can directly generate product prototype interfaces with complex UI, truly achieving "what you say is what you get."
Productivity Boost: 10-Hour Audio Long-Term Understanding
For professional fields, the new model offers powerful structured processing capabilities:
Deep Video Analysis: It can finely decompose the main subject of the image, relationships between people, and emotional fluctuations.
Automatic Segmentation: It supports over 10 hours of audio input and can automatically complete video chapter segmentation and timestamp annotation, significantly improving content creation efficiency.
Inclusive Ecosystem: Price is Just One-Tenth of Gemini
The Alibaba Cloud Bailian platform has simultaneously launched three APIs: Plus, Flash, and Light, aiming to provide the most cost-effective solution for enterprises:
Extremely Low Cost: The input cost per million Tokens is less than 0.8 yuan, costing less than one-tenth of Gemini-3.1Pro.
Market Leadership: Currently, Qwen has served over one million customers and remains the top choice in the enterprise-level large model call market in China.
Conclusion: From "Understanding Text" to "Perceiving the World"
The release of Qwen3.5-Omni








 Zhou Shen Unveils Moon Chronicle, Explicitly Banning AI Training and Voice Cloning
On April 1st, acclaimed Chinese artist Zhou Shen launched "Yue Zhi Ji," the theme song for the historical fantasy series "Yue Lin Qi Ji." He embedded a clear copyright notice in the track’s prelude and lyrics, explicitly banning its use for Artificia
 Anthropic admits its AI models breached three firms during security tests
Anthropic announced Thursday that an internal probe revealed three separate incidents where its AI model, Claude, breached the systems of three organizations during cybersecurity assessments. This disclosure follows closely on the heels of OpenAI’s r
 Meitu Unveils RoboNeo AI Agent Powered by Alibaba’s HappyHorse Model, Marking a Leap in Video Creation
On April 28, RoboNeo, an AI agent by Meitu Company, announced the integration of HappyHorse, a multimodal video generation model from Alibaba's ATH Innovation Division. Leveraging Seedance 2.0, RoboNeo has significantly enhanced product video creatio

2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
10 tools
xix.ai

2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai

2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai

2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai












