Home

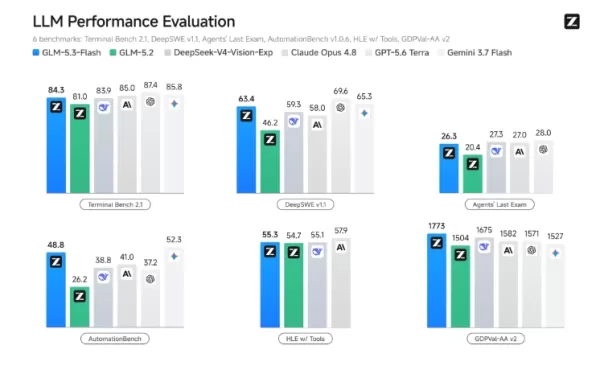
Zhipu AI launched GLM-5.3-FlashX on its BigModel platform, featuring 200 tokens per second output speed. This enhanced version builds on the popular GLM-5.3-Flash, leveraging 100,000 domestic chips to optimize inference efficiency. It prioritizes intelligence, cost-effectiveness, and speed, offering high-throughput, low-latency services for enterprises. Available via API and experience center, the upgrade aims to boost commercial viability in high-concurrency scenarios, marking significant progress in domestic large model inference and accessibility.
Comments (0)
0/300