
option
Home
Flash News
Content
MichaelMartinez
MichaelMartinez
April 14, 2026

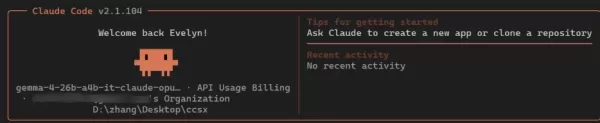
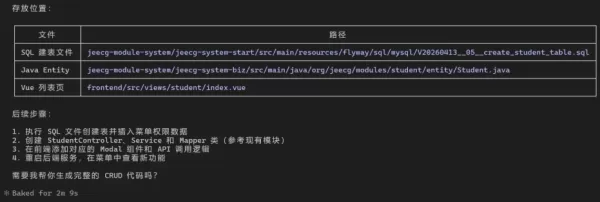
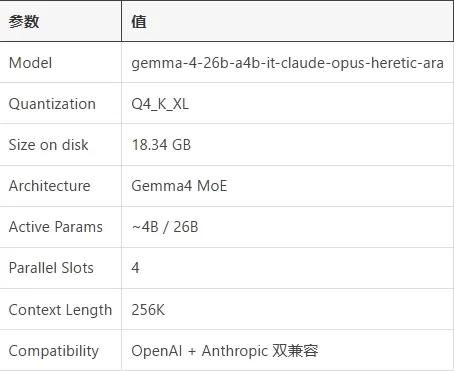
Developer JeecgBoot tested a community-modified distillation model on Mac Studio M4Max, achieving 5-6x faster generation speeds than the official version. The model, using an A4B MoE architecture with 26B total parameters, activated only about 4B per inference, reaching up to 78 tok/s and supporting 256K context. While generation is fast, complex Agentic workflows for tasks like code generation can take ~1.5 minutes due to multi-step decision chains. The test successfully generated a standardized JeecgBoot project skeleton. A dual-model strategy is recommended: using the local modified model for most tasks (like CRUD) for privacy and cost savings, and cloud APIs for complex design needs.
Developer JeecgBoot tested a community-modified distillation model on Mac Studio M4Max, achieving 5-6x faster generation speeds than the official version. The model, using an A4B MoE architecture with 26B total parameters, activated only about 4B per inference, reaching up to 78 tok/s and supporting 256K context. While generation is fast, complex Agentic workflows for tasks like code generation can take ~1.5 minutes due to multi-step decision chains. The test successfully generated a standardized JeecgBoot project skeleton. A dual-model strategy is recommended: using the local modified model for most tasks (like CRUD) for privacy and cost savings, and cloud APIs for complex design needs. Developer JeecgBoot tested a community-modified distillation model on Mac Studio M4Max, achieving 5-6x faster generation speeds than the official version. The model, using an A4B MoE architecture with 26B total parameters, activated only about 4B per inference, reaching up to 78 tok/s and supporting 256K context. While generation is fast, complex Agentic workflows for tasks like code generation can take ~1.5 minutes due to multi-step decision chains. The test successfully generated a standardized JeecgBoot project skeleton. A dual-model strategy is recommended: using the local modified model for most tasks (like CRUD) for privacy and cost savings, and cloud APIs for complex design needs. Developer JeecgBoot tested a community-modified distillation model on Mac Studio M4Max, achieving 5-6x faster generation speeds than the official version. The model, using an A4B MoE architecture with 26B total parameters, activated only about 4B per inference, reaching up to 78 tok/s and supporting 256K context. While generation is fast, complex Agentic workflows for tasks like code generation can take ~1.5 minutes due to multi-step decision chains. The test successfully generated a standardized JeecgBoot project skeleton. A dual-model strategy is recommended: using the local modified model for most tasks (like CRUD) for privacy and cost savings, and cloud APIs for complex design needs.
Comments (0)
0/300
OR