


 Home
StepZen Unveils Step Audio 2.5 Realtime Version, Offering Human-Like Emotions and Intelligence to Large Language Models
With the rapid advancement of artificial intelligence, the interaction experience offered by large language models is undergoing a significant shift, moving beyond simple text-based conversations toward true real-time emotional communication. On May 8th, Jieque Star, a leading innovator in the field of large language models, unveiled its latest research breakthrough — the new real-time speech model StepAudio 2.5 Realtime. The release of this advanced model represents another milestone in enhancing the naturalness and intelligence of domestic large language models designed for voice interactions.
Deep Perception: Entering an Interaction Era at Human-Level Complexity
Unlike conventional voice assistants, StepAudio 2.5 Realtime stands out thanks to its highly sophisticated deep perception capabilities that operate at a human-level sophistication. It goes beyond simply recognizing spoken commands; instead, it can accurately detect subtle emotional cues and contextual shifts within conversations.
Thanks to these technological improvements, the model has achieved significant advancements in both cognitive and emotional intelligence. During interactions, it is able to deliver responses that better align with the user’s emotional state, taking into account factors such as tone and speaking pace. This enables the communication to move beyond a one-way information exchange toward more genuine, human-like dialogue filled with empathy.
Flexible Customization: Building Tailored AI Personas
To suit the diverse needs of various application scenarios, StepAudio 2.5 Realtime features a highly adaptable option for customizing AI personas. Whether users require a professional and reliable assistant for work or a lively chat partner for entertainment, developers and end-users can assign specific personality traits and language styles to the AI based on their actual requirements. This level of personalization has the potential to significantly broaden the scope of application for real-time speech models across industries such as education, entertainment, and business.
Full Commercial Availability: Domestic Large Language Models Accelerating Their Growth
At present, Jieque Star has announced that StepAudio 2.5 Realtime is now fully available for use. This means that developers and partners can immediately access and start experimenting with this cutting-edge technology.
Related article
 How AWS and NVIDIA Are Powering Agentic and Physical AI
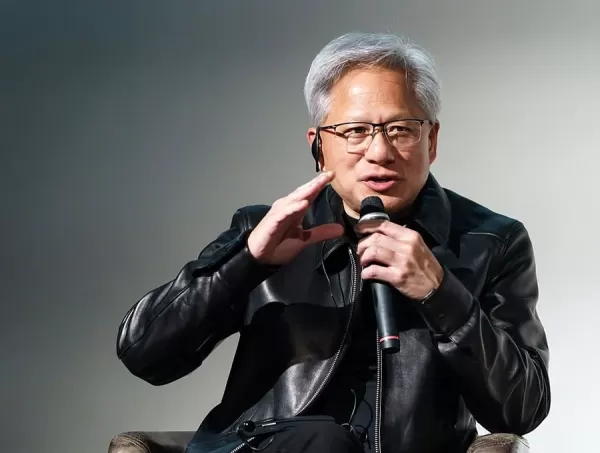
NVIDIA CEO Jensen Huang (Credit: Tomohiro Ohsumi/Getty Images)Jensen Huang’s NVIDIA and AWS scale their global partnership, deploying 2M GPUs to power next-generation agentic and physical AI enterprise infrastructureAWS and NVIDIA have announced a ma
SenseTime Unveils 8B Lightweight Multimodal Model with Native 4K Output and Full Visual Editing Capabilities
SenseTime has officially released SenseNova U1.5Lite, a new lightweight, native unified multimodal large model. With 8B parameters, this efficient model outperforms similarly sized alternatives in key visual tasks and matches large-scale commercial m
Brainwave Training Robot: Physical AI’s Next Leap Driven by Human Brain Signals
In a San Leandro, California warehouse, Encord, a data tools firm, is running an innovative experiment: "pilots" wear headsets with cameras and EEG sensors while playing Jenga to capture brain activity. The Zander Labs EEG headset tracks brainwaves i
Related Special Topic Recommendations
Design & Art
 Top AI Illustration Tools: Create Editorial Scenes and Cover Art Faster
2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
 10 tools
 xix.ai
Education and Learning
Top AI Tutors for Exam Prep: Practice Math, Science, and English
2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai
Finance
AI Budget Planning Tools for Personal Money Management
2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai
Health & Wellness
AI Sleep Tracking Assistants: Improve Recovery with Better Bedtime Habits
2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai
Data Analysis
AI SQL Copilots for Product and Revenue Analytics
2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai
Education and Learning
Best AI Homework Helpers That Teach: Learn Concepts, Not Just Answers
2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai

 Comments (0)
0/500
With the rapid advancement of artificial intelligence, the interaction experience offered by large language models is undergoing a significant shift, moving beyond simple text-based conversations toward true real-time emotional communication. On May 8th, Jieque Star, a leading innovator in the field of large language models, unveiled its latest research breakthrough — the new real-time speech model StepAudio 2.5 Realtime. The release of this advanced model represents another milestone in enhancing the naturalness and intelligence of domestic large language models designed for voice interactions.
Deep Perception: Entering an Interaction Era at Human-Level Complexity
Unlike conventional voice assistants, StepAudio 2.5 Realtime stands out thanks to its highly sophisticated deep perception capabilities that operate at a human-level sophistication. It goes beyond simply recognizing spoken commands; instead, it can accurately detect subtle emotional cues and contextual shifts within conversations.
Thanks to these technological improvements, the model has achieved significant advancements in both cognitive and emotional intelligence. During interactions, it is able to deliver responses that better align with the user’s emotional state, taking into account factors such as tone and speaking pace. This enables the communication to move beyond a one-way information exchange toward more genuine, human-like dialogue filled with empathy.
Flexible Customization: Building Tailored AI Personas
To suit the diverse needs of various application scenarios, StepAudio 2.5 Realtime features a highly adaptable option for customizing AI personas. Whether users require a professional and reliable assistant for work or a lively chat partner for entertainment, developers and end-users can assign specific personality traits and language styles to the AI based on their actual requirements. This level of personalization has the potential to significantly broaden the scope of application for real-time speech models across industries such as education, entertainment, and business.
Full Commercial Availability: Domestic Large Language Models Accelerating Their Growth
At present, Jieque Star has announced that StepAudio 2.5 Realtime is now fully available for use. This means that developers and partners can immediately access and start experimenting with this cutting-edge technology.








 How AWS and NVIDIA Are Powering Agentic and Physical AI
NVIDIA CEO Jensen Huang (Credit: Tomohiro Ohsumi/Getty Images)Jensen Huang’s NVIDIA and AWS scale their global partnership, deploying 2M GPUs to power next-generation agentic and physical AI enterprise infrastructureAWS and NVIDIA have announced a ma
 SenseTime Unveils 8B Lightweight Multimodal Model with Native 4K Output and Full Visual Editing Capabilities
SenseTime has officially released SenseNova U1.5Lite, a new lightweight, native unified multimodal large model. With 8B parameters, this efficient model outperforms similarly sized alternatives in key visual tasks and matches large-scale commercial m
 Brainwave Training Robot: Physical AI’s Next Leap Driven by Human Brain Signals
In a San Leandro, California warehouse, Encord, a data tools firm, is running an innovative experiment: "pilots" wear headsets with cameras and EEG sensors while playing Jenga to capture brain activity. The Zander Labs EEG headset tracks brainwaves i

2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
10 tools
xix.ai

2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai

2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai

2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai












