


 Home
OmniHuman AI Transforms Video Production Using a Single Image
In the rapidly evolving field of artificial intelligence, a revolutionary new tool has emerged with the potential to transform video creation. OmniHuman AI is a state-of-the-art technology that produces remarkably realistic videos from just one image and an audio file. This innovative solution is set to reshape numerous industries, including entertainment, marketing, education, and accessibility services. Yet, such powerful technology also carries significant responsibilities, making it essential to understand its broader implications. This article will delve into OmniHuman AI, exploring its impressive features and its possible effects on society.
Key Points
OmniHuman AI creates lifelike videos using only a single image and audio file.
It makes video content creation exceptionally straightforward.
It has applications across education, entertainment, marketing, and accessibility.
The technology offers vast opportunities alongside important ethical questions.
OmniHuman's capabilities, especially in full-body animation and detailed motion capture, exceed those of current AI video generators.
Although it's not yet publicly accessible, its upcoming release is highly awaited.
Understanding OmniHuman AI
What is OmniHuman AI?
OmniHuman AI is a groundbreaking multimodality-conditioned framework for generating human videos. Its unique feature is producing full-body, realistic videos using only one image and an audio track. It was developed by Bytedance.
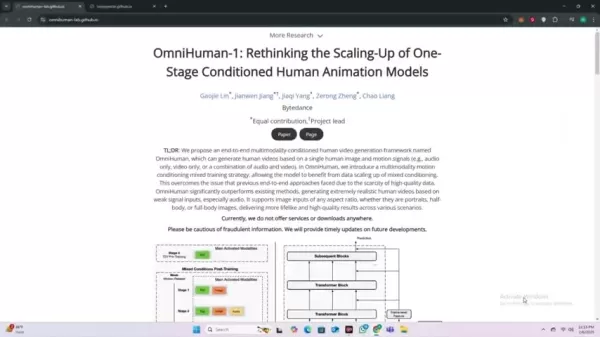
This approach streamlines content creation, making realistic video production more accessible than ever. The primary strength of OmniHuman is its capacity to deduce realistic human motions, facial expressions, and lip-syncing from very limited input. OmniHuman differs from other AI video tools through its superior performance, achieving outcomes that were previously out of reach. With OmniHuman AI, current techniques are substantially outperformed, resulting in highly realistic human videos even from sparse inputs like audio, consistently delivering natural and high-fidelity results in diverse contexts.
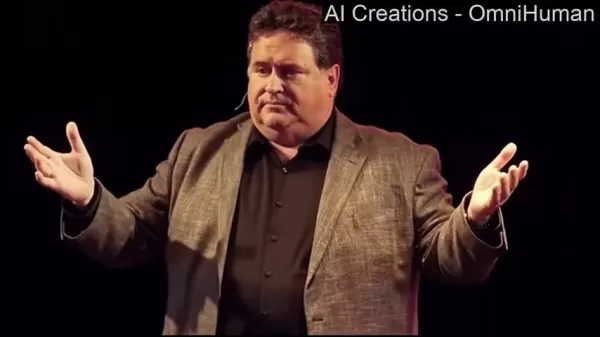
This AI works by examining the provided image to identify the subject's characteristics, then uses the audio to guide the subject's motions, facial expressions, and speech patterns. The system can generate a wide range of content, such as:
- Lip-synced speech: Precisely aligning the audio with believable mouth movements.
- Natural gestures: Creating realistic hand and body motions that fit the audio's context.
- Emotional expressions: Animating facial and body language that reflects the feelings in the audio.
How Does OmniHuman AI Work?
OmniHuman AI's technical strength comes from its end-to-end, multimodality-conditioned framework for human video generation. This system employs a novel method that overcomes previous limitations of end-to-end models, largely due to the shortage of high-quality training data. OmniHuman substantially outperforms existing approaches, creating extremely realistic human videos from minimal inputs, particularly audio. The AI depends on a blend of advanced machine learning methods, including:
- Deep learning: For analyzing and interpreting image and audio data.
- Generative adversarial networks (GANs): For producing realistic video frames.
- Motion capture technology: For accurately reproducing human movements.
- Transformer Networks: These models help understand long-range relationships in the audio and link them to corresponding motion and visual elements for video production.
The general process involves these stages:
- Image and audio input: The user supplies one person's image and a recording of their speech.
- AI processing: OmniHuman AI processes the image and audio to extract relevant features.
- Video synthesis: The AI produces a lifelike video of the individual speaking the audio, complete with fitting facial expressions and body language.
The final product is a smooth and credible video suitable for various uses. Notably, the AI animates not just head movements but also hand gestures, maintaining excellent hand consistency throughout.
.
Technical Specifications of OmniHuman AI
Here are the model's specifications that outline its capabilities and operational mechanics.
- Model Name: OmniHuman-1
- Developer: Bytedance
- Paper: OmniHuman-1: Rethinking the Scaling-Up of One-Stage Conditioned Human Animation Models
- Framework: End-to-end multimodality-conditioned human video generation framework
- Input: OmniHuman creates human videos from a single human image and motion cues (e.g., audio-only, video-only, or a mix of both).
- Capabilities:
- Supports various visual and audio styles.
- Generates realistic human videos in any aspect ratio and body proportion (accommodating portrait, half-body, and full-body shots in one model), achieving realism through motion, lighting, and texture details.
- Handles multiple body poses and singing formats.
- Manages high-pitched songs and shows different motion styles for various music genres.
- Produces realistic human videos in any aspect ratio and body proportion.
- Accepts image inputs of any aspect ratio, including portraits, half-body, and full-body photos.
- Availability: Currently, the services or downloads are not offered anywhere. The codebase is also not publicly released.
Ethical Considerations and Potential Risks
Deepfakes and Misinformation
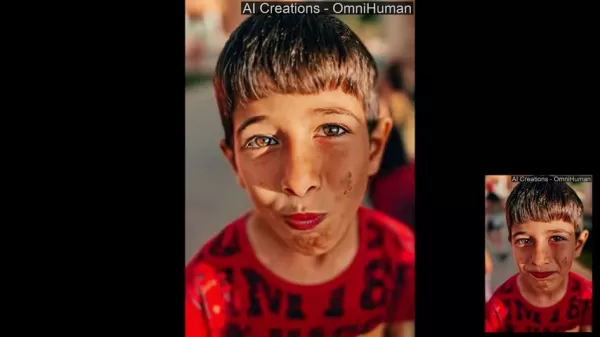
The simplicity of creating realistic videos with OmniHuman AI also brings up worries about possible misuse. The technology could be exploited to produce deepfakes – altered videos that realistically show someone saying or doing something that never happened. AI-generated videos might be used to spread false information, damage someone's reputation, or even provoke conflict. Distinguishing between genuine footage and AI-created videos becomes challenging.
Addressing these dangers requires a multi-pronged strategy, involving:
- Creating detection tools: Building AI-based systems that can recognize deepfakes and other manipulated videos.
- Enhancing media literacy: Teaching people how to identify deepfakes and other types of online falsehoods.
- Setting ethical standards: Forming industry norms and ethical rules for producing and using AI-generated videos.
- Ensuring consistent digital markers in generated content to allow quick identification of AI characters.
Bias and Representation
Similar to many AI systems, OmniHuman AI is prone to bias depending on its training data. If the training data lacks diversity and representation, the AI might create videos that reinforce negative stereotypes or overlook certain communities. Tackling bias in AI systems involves:
- Utilizing diverse training data: Making sure the data used for training OmniHuman AI represents various ethnicities, genders, and cultural backgrounds.
- Conducting bias audits: Regularly checking the AI's outputs to find and reduce any potential biases.
- Encouraging transparency: Sharing the AI's training data and algorithms openly to enable review and accountability.
Pricing
OmniHuman AI Pricing
At this time, OmniHuman remains in the research and development phase, and no pricing information has been announced. We will promptly inform you as soon as OmniHuman reveals its pricing structure.
Stay tuned for pricing updates!
OmniHuman AI: Pros and Cons
Pros
High-quality video output: Produces realistic and compelling videos.
User-friendly: Needs only one image and audio file.
Adaptable: Works with diverse visual and audio formats.
Full-body movement: Able to create realistic full-body animations.
Cons
Risk of misuse: Could be employed to make deepfakes and circulate misinformation.
Ethical issues: Brings up concerns about truthfulness and permission.
Bias vulnerability: May reflect biases if trained on unrepresentative data.
Not currently available to the public: Presently restricted to research and development use.
Frequently Asked Questions
What is OmniHuman AI?
OmniHuman AI is an artificial intelligence tool created by Bytedance that can generate realistic videos from just one image and an audio track. It enables portrait animation and full-body video creation with synchronized lip movement, gestures, and expressions.
How does OmniHuman AI compare to other AI video generators?
It distinguishes itself from other AI video tools through its higher performance, achieving realistic results that were once impossible. It outperforms current methods by creating extremely lifelike human videos even with limited inputs like audio. It also accommodates various visual and audio styles and accepts image inputs in any aspect ratio, including portraits, half-body, and full-body shots.
Can OmniHuman AI handle different languages?
Yes, OmniHuman AI can process multiple languages for both audio input and video output.
Is OmniHuman AI able to handle animated and cartoon images?
Yes! Although it delivers the most realistic results with actual photos, this AI can also work with cartoons and animated figures.
Related Questions
What are some other AI video generation tools available?
The AI video generation field is continuously advancing, with new tools and platforms appearing frequently. While OmniHuman AI is notable for its realism and simplicity, other significant alternatives include: VASA-1 (Microsoft): Focuses on creating natural-looking talking faces with accurate lip-sync, realistic facial expressions, and natural head motions, generated in real time. RunwayML: A full-featured AI-driven creative platform with tools for video editing, style transfer, and content generation. Synthesia: A service that lets you build AI avatars and produce videos from text, providing an economical option for training and marketing materials. DeepMotion: Specializes in motion capture and animation, allowing you to develop realistic 3D animations from video clips. Elai.io: Concentrates on making AI presenters for videos, perfect for training, product demonstrations, and marketing content. Always research each option thoroughly to choose the one that best matches your specific requirements and budget. Also, check their usage policies to avoid unethical applications.
Related article
 Stripe to Acquire OpenRouter as AI Model Routing Gains Momentum
Stripe has agreed to acquire OpenRouter, an AI model-routing platform that gives developers access to hundreds of models through a single interface. The deal adds model selection and routing to Stripe’s existing work around AI usage and token-based b
Former OpenAI Researcher Barrett Zoph Returns to Google to Support Gemini Development
Barret Zoph, who previously abruptly left and joined OpenAI due to a disagreement with Thinking Machines Lab CEO Miriam Mularati, has once again changed employers. Alphabet's Google announced that Zoph will return as Vice President of Research, bring
How Recursive Intelligence Raised $335M at $4B Valuation in 4 Months
The co-founders of startup Ricursive Intelligence seemed destined to be co-founders.Anna Goldie, CEO, and Azalia Mirhoseini, CTO, are so well-known in the AI community that they were among those AI engineers who “got those weird emails from Zuckerber
Related Special Topic Recommendations
Design & Art
 Top AI Illustration Tools: Create Editorial Scenes and Cover Art Faster
2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
 10 tools
 xix.ai
Education and Learning
Top AI Tutors for Exam Prep: Practice Math, Science, and English
2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai
Finance
AI Budget Planning Tools for Personal Money Management
2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai
Health & Wellness
AI Sleep Tracking Assistants: Improve Recovery with Better Bedtime Habits
2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai
Data Analysis
AI SQL Copilots for Product and Revenue Analytics
2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai
Education and Learning
Best AI Homework Helpers That Teach: Learn Concepts, Not Just Answers
2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai

 Comments (3)
0/500
![BruceHernández]()
這技術也太酷了吧!只用一張照片就能生成影片,以後拍片門檻是不是要降到零了?不過想到深度偽造濫用的可能性,又有點擔心... 開發團隊有考慮過倫理防護機制嗎?🤔
![RogerJackson]()
제목만 봐도 상상력을 자극하네요! 단 하나의 사진으로 비디오를 만다니, 이게 진짜 기술인가요? 🧐 AI가 이렇게 발전하면 영상 제작자들은 걱정해야 할지도... 제 친구가 요즘 영상 편집하는데 엄청 시간이 걸린다고 하던데, 이런 기술이 실용화되면 업무 방식이 완전히 바뀔 것 같아요. 근데 이런 기술이 악용될 가능성에 대한 논의도 필요하지 않을까요?
![KevinTaylor]()
Один снимок, а готово целое видео — возможно ли это? OmniHuman AI, судя по всему, делает именно это. Очень впечатляет, хотя лично мне интересно, как технология справляется с движением объектов в кадре, особенно когда изначальная фотография статична. Возможно, в будущем создание фильмов станет куда доступнее для обычных пользователей! 🎥 👏 Надеюсь, это не приведет к распространению фейкового контента.
In the rapidly evolving field of artificial intelligence, a revolutionary new tool has emerged with the potential to transform video creation. OmniHuman AI is a state-of-the-art technology that produces remarkably realistic videos from just one image and an audio file. This innovative solution is set to reshape numerous industries, including entertainment, marketing, education, and accessibility services. Yet, such powerful technology also carries significant responsibilities, making it essential to understand its broader implications. This article will delve into OmniHuman AI, exploring its impressive features and its possible effects on society.
Key Points
OmniHuman AI creates lifelike videos using only a single image and audio file.
It makes video content creation exceptionally straightforward.
It has applications across education, entertainment, marketing, and accessibility.
The technology offers vast opportunities alongside important ethical questions.
OmniHuman's capabilities, especially in full-body animation and detailed motion capture, exceed those of current AI video generators.
Although it's not yet publicly accessible, its upcoming release is highly awaited.
Understanding OmniHuman AI
What is OmniHuman AI?
OmniHuman AI is a groundbreaking multimodality-conditioned framework for generating human videos. Its unique feature is producing full-body, realistic videos using only one image and an audio track. It was developed by Bytedance.
This approach streamlines content creation, making realistic video production more accessible than ever. The primary strength of OmniHuman is its capacity to deduce realistic human motions, facial expressions, and lip-syncing from very limited input. OmniHuman differs from other AI video tools through its superior performance, achieving outcomes that were previously out of reach. With OmniHuman AI, current techniques are substantially outperformed, resulting in highly realistic human videos even from sparse inputs like audio, consistently delivering natural and high-fidelity results in diverse contexts.
This AI works by examining the provided image to identify the subject's characteristics, then uses the audio to guide the subject's motions, facial expressions, and speech patterns. The system can generate a wide range of content, such as:
- Lip-synced speech: Precisely aligning the audio with believable mouth movements.
- Natural gestures: Creating realistic hand and body motions that fit the audio's context.
- Emotional expressions: Animating facial and body language that reflects the feelings in the audio.
How Does OmniHuman AI Work?
OmniHuman AI's technical strength comes from its end-to-end, multimodality-conditioned framework for human video generation. This system employs a novel method that overcomes previous limitations of end-to-end models, largely due to the shortage of high-quality training data. OmniHuman substantially outperforms existing approaches, creating extremely realistic human videos from minimal inputs, particularly audio. The AI depends on a blend of advanced machine learning methods, including:
- Deep learning: For analyzing and interpreting image and audio data.
- Generative adversarial networks (GANs): For producing realistic video frames.
- Motion capture technology: For accurately reproducing human movements.
- Transformer Networks: These models help understand long-range relationships in the audio and link them to corresponding motion and visual elements for video production.
The general process involves these stages:
- Image and audio input: The user supplies one person's image and a recording of their speech.
- AI processing: OmniHuman AI processes the image and audio to extract relevant features.
- Video synthesis: The AI produces a lifelike video of the individual speaking the audio, complete with fitting facial expressions and body language.
The final product is a smooth and credible video suitable for various uses. Notably, the AI animates not just head movements but also hand gestures, maintaining excellent hand consistency throughout.
.
Technical Specifications of OmniHuman AI
Here are the model's specifications that outline its capabilities and operational mechanics.
- Model Name: OmniHuman-1
- Developer: Bytedance
- Paper: OmniHuman-1: Rethinking the Scaling-Up of One-Stage Conditioned Human Animation Models
- Framework: End-to-end multimodality-conditioned human video generation framework
- Input: OmniHuman creates human videos from a single human image and motion cues (e.g., audio-only, video-only, or a mix of both).
- Capabilities:
- Supports various visual and audio styles.
- Generates realistic human videos in any aspect ratio and body proportion (accommodating portrait, half-body, and full-body shots in one model), achieving realism through motion, lighting, and texture details.
- Handles multiple body poses and singing formats.
- Manages high-pitched songs and shows different motion styles for various music genres.
- Produces realistic human videos in any aspect ratio and body proportion.
- Accepts image inputs of any aspect ratio, including portraits, half-body, and full-body photos.
- Availability: Currently, the services or downloads are not offered anywhere. The codebase is also not publicly released.
Ethical Considerations and Potential Risks
Deepfakes and Misinformation
The simplicity of creating realistic videos with OmniHuman AI also brings up worries about possible misuse. The technology could be exploited to produce deepfakes – altered videos that realistically show someone saying or doing something that never happened. AI-generated videos might be used to spread false information, damage someone's reputation, or even provoke conflict. Distinguishing between genuine footage and AI-created videos becomes challenging.
Addressing these dangers requires a multi-pronged strategy, involving:
- Creating detection tools: Building AI-based systems that can recognize deepfakes and other manipulated videos.
- Enhancing media literacy: Teaching people how to identify deepfakes and other types of online falsehoods.
- Setting ethical standards: Forming industry norms and ethical rules for producing and using AI-generated videos.
- Ensuring consistent digital markers in generated content to allow quick identification of AI characters.
Bias and Representation
Similar to many AI systems, OmniHuman AI is prone to bias depending on its training data. If the training data lacks diversity and representation, the AI might create videos that reinforce negative stereotypes or overlook certain communities. Tackling bias in AI systems involves:
- Utilizing diverse training data: Making sure the data used for training OmniHuman AI represents various ethnicities, genders, and cultural backgrounds.
- Conducting bias audits: Regularly checking the AI's outputs to find and reduce any potential biases.
- Encouraging transparency: Sharing the AI's training data and algorithms openly to enable review and accountability.
Pricing
OmniHuman AI Pricing
At this time, OmniHuman remains in the research and development phase, and no pricing information has been announced. We will promptly inform you as soon as OmniHuman reveals its pricing structure.
Stay tuned for pricing updates!
OmniHuman AI: Pros and Cons
Pros
High-quality video output: Produces realistic and compelling videos.
User-friendly: Needs only one image and audio file.
Adaptable: Works with diverse visual and audio formats.
Full-body movement: Able to create realistic full-body animations.
Cons
Risk of misuse: Could be employed to make deepfakes and circulate misinformation.
Ethical issues: Brings up concerns about truthfulness and permission.
Bias vulnerability: May reflect biases if trained on unrepresentative data.
Not currently available to the public: Presently restricted to research and development use.
Frequently Asked Questions
What is OmniHuman AI?
OmniHuman AI is an artificial intelligence tool created by Bytedance that can generate realistic videos from just one image and an audio track. It enables portrait animation and full-body video creation with synchronized lip movement, gestures, and expressions.
How does OmniHuman AI compare to other AI video generators?
It distinguishes itself from other AI video tools through its higher performance, achieving realistic results that were once impossible. It outperforms current methods by creating extremely lifelike human videos even with limited inputs like audio. It also accommodates various visual and audio styles and accepts image inputs in any aspect ratio, including portraits, half-body, and full-body shots.
Can OmniHuman AI handle different languages?
Yes, OmniHuman AI can process multiple languages for both audio input and video output.
Is OmniHuman AI able to handle animated and cartoon images?
Yes! Although it delivers the most realistic results with actual photos, this AI can also work with cartoons and animated figures.
Related Questions
What are some other AI video generation tools available?
The AI video generation field is continuously advancing, with new tools and platforms appearing frequently. While OmniHuman AI is notable for its realism and simplicity, other significant alternatives include: VASA-1 (Microsoft): Focuses on creating natural-looking talking faces with accurate lip-sync, realistic facial expressions, and natural head motions, generated in real time. RunwayML: A full-featured AI-driven creative platform with tools for video editing, style transfer, and content generation. Synthesia: A service that lets you build AI avatars and produce videos from text, providing an economical option for training and marketing materials. DeepMotion: Specializes in motion capture and animation, allowing you to develop realistic 3D animations from video clips. Elai.io: Concentrates on making AI presenters for videos, perfect for training, product demonstrations, and marketing content. Always research each option thoroughly to choose the one that best matches your specific requirements and budget. Also, check their usage policies to avoid unethical applications.








 Stripe to Acquire OpenRouter as AI Model Routing Gains Momentum
Stripe has agreed to acquire OpenRouter, an AI model-routing platform that gives developers access to hundreds of models through a single interface. The deal adds model selection and routing to Stripe’s existing work around AI usage and token-based b
 Former OpenAI Researcher Barrett Zoph Returns to Google to Support Gemini Development
Barret Zoph, who previously abruptly left and joined OpenAI due to a disagreement with Thinking Machines Lab CEO Miriam Mularati, has once again changed employers. Alphabet's Google announced that Zoph will return as Vice President of Research, bring
 How Recursive Intelligence Raised $335M at $4B Valuation in 4 Months
The co-founders of startup Ricursive Intelligence seemed destined to be co-founders.Anna Goldie, CEO, and Azalia Mirhoseini, CTO, are so well-known in the AI community that they were among those AI engineers who “got those weird emails from Zuckerber

2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
10 tools
xix.ai

2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai

2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai

2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai

這技術也太酷了吧!只用一張照片就能生成影片,以後拍片門檻是不是要降到零了?不過想到深度偽造濫用的可能性,又有點擔心... 開發團隊有考慮過倫理防護機制嗎?🤔
제목만 봐도 상상력을 자극하네요! 단 하나의 사진으로 비디오를 만다니, 이게 진짜 기술인가요? 🧐 AI가 이렇게 발전하면 영상 제작자들은 걱정해야 할지도... 제 친구가 요즘 영상 편집하는데 엄청 시간이 걸린다고 하던데, 이런 기술이 실용화되면 업무 방식이 완전히 바뀔 것 같아요. 근데 이런 기술이 악용될 가능성에 대한 논의도 필요하지 않을까요?
Один снимок, а готово целое видео — возможно ли это? OmniHuman AI, судя по всему, делает именно это. Очень впечатляет, хотя лично мне интересно, как технология справляется с движением объектов в кадре, особенно когда изначальная фотография статична. Возможно, в будущем создание фильмов станет куда доступнее для обычных пользователей! 🎥 👏 Надеюсь, это не приведет к распространению фейкового контента.












