


 Home
Apple Unveils RubiCap AI for Image Descriptions Amid Performance Concerns
In computer vision, enabling AI to observe and describe every detail of an image with human-like precision has long been a core challenge. Recently, Apple, in collaboration with the University of Wisconsin-Madison, officially released a novel AI training framework named RubiCap .
This framework is specifically designed for "dense image captioning," aiming to empower AI to accurately capture and articulate fine-grained details—like "a red apple on the wooden table" or "a pedestrian in the distance"—rather than offering only generic summaries.
Reinforcement Learning with Major Impact: Qwen2.5 Serves as the "Referee"
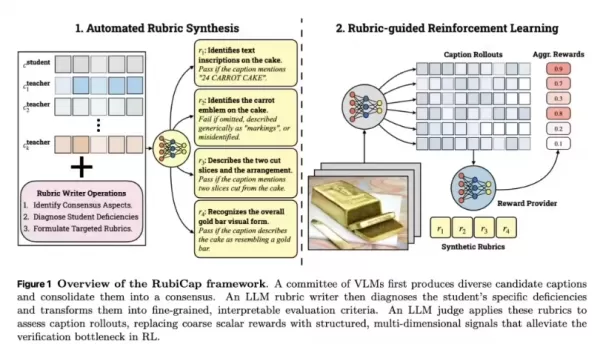
Traditional image captioning often depends on costly human annotation or large models prone to hallucination, resulting in inconsistent data quality. The Apple research team addressed this with an innovative reinforcement learning approach. The system first uses GPT-4 and Gemini 1.5 Pro to generate candidate descriptions. Gemini 1.5 Pro then refines the scoring criteria, while the Qwen2.5 model acts as a referee, providing scores and feedback.
This structured, precise feedback allows the training model to clearly identify and correct errors, achieving higher descriptive accuracy even with a smaller parameter count.
The Compact Model Advantage: Lower Hallucination Rates Surpass Trillion-Parameter Models
The RubiCap series models (ranging from 2 billion to 7 billion parameters) trained on this framework demonstrated exceptional efficiency in evaluations. Experimental data reveals that the 7-billion-parameter RubiCap model achieved top scores in blind tests, with a hallucination error rate lower than a leading 720-billion-parameter large model. Remarkably, the 3-billion-parameter mini version even outperformed its 7-billion-parameter counterpart on certain metrics.
Related article
 DeepMind CEO Hassabis: I sleep six hours a day, usually feel energetic around 1 a.m.
Fortune recently featured an interview with Demis Hassabis, CEO of Google DeepMind, revealing his unconventional approach to rest and productivity. Hassabis disclosed that he sleeps very little, structuring his waking hours into two distinct work blo
OpenAI, Anthropic Vie for Market Share Despite Revenue Shortfalls
Despite recent reports suggesting OpenAI missed revenue targets, creating pressure on tech stocks this Tuesday, private AI lab investors remain resilient. Seasoned backers have confirmed they will not reduce investment despite negative media coverage
California AV Compliance: A New Era of Tickets, Geofences, and 1M Miles
Guident operates an AuveTech shuttle in South Florida, managing a four-mile route in West Palm Beach and a one-mile route in Boca Raton using its remote monitoring technology. | Credit: GuidentCalifornia is redefining the regulatory landscape for dri
Related Special Topic Recommendations
Music composition
 AI Stem Separation Tools for Remix Production, Sampling Prep, and Karaoke Masters
2026 Latest Best Top-rated AI Stem Separation Tools Curated for Remix Production, Sampling Prep, and Karaoke Masters. These powerful game-changing tools offer real-world tests to deliver precise audio isolation, boosting productivity significantly. XIX.AI provides a weekly updated free vs paid comparison guide to help you find the must-try solution that suits your needs. Explore now to unlock your AI edge.
 8 tools
 xix.ai
Data Analysis
AI SQL Copilots for Revenue Dashboards, Funnel Analysis, and Product Metrics
2026 Latest Best AI SQL Copilots Ranked Top-Rated! XIX.AI curates a powerful game-changing collection for weekly updated real-world tests. These must-try tools help you generate accurate revenue dashboards, analyze sales funnels, and track product metrics swiftly, boosting productivity massively. Explore now to Discover your perfect tool for data-driven decision making! 238 characters
9 tools
xix.ai
Music composition
Best AI Melody Writing Tools for Song Drafts
2026 Latest Best Top-Rated AI Melody Writing Tools for Song Drafts! XIX.AI has curated a highly powerful game-changing collection that goes through rigorous real-world tests to deliver the best writing experience. You can find detailed free vs paid comparisons, accurate rankings, and must-try options designed to help you create stunning song drafts effortlessly and boost your creative productivity significantly. Explore now to discover your perfect tool!
8 tools
xix.ai
chatbot
Best AI Conversation Trainer Tools for Interview Practice
2026 Latest Best Top-rated AI Conversation Trainer Tools for Interview Practice are here on XIX.AI! This curated collection features powerful, game-changing tools that go through rigorous real-world tests to deliver accurate feedback. You’ll find a free vs paid comparison and detailed rankings to help you choose the must-try option that boosts your confidence and skills. Explore now to Discover your perfect tool for interview success!
12 tools
xix.ai
Design & Art
Best AI Style Transfer Tools for Creative Experiments
2026 Latest Best Top-rated AI Style Transfer Tools for Creative Experiments! XIX.AI has curated a powerful, game-changing collection of must-try tools that deliver exceptional results through real-world tests and rigorous rankings. These top solutions help creatives boost productivity significantly by accelerating content creation and unlocking endless creative possibilities. Explore now to discover your perfect tool and start creating today!
9 tools
xix.ai
Comic Creation
Best AI Dialogue Bubble Tools for Visual Storytelling
2026 Latest Best Top-Rated AI Dialogue Bubble Tools for Visual Storytelling are here on XIX.AI! This curated collection features powerful, game-changing tools that help creators boost productivity and overcome creative bottlenecks. Get a free vs paid comparison, see real-world tests, and check the latest rankings to find the must-try solutions perfect for crafting engaging visual narratives. Explore now to discover your ideal tool!
10 tools
xix.ai

 Comments (0)
0/500
In computer vision, enabling AI to observe and describe every detail of an image with human-like precision has long been a core challenge. Recently, Apple, in collaboration with the University of Wisconsin-Madison, officially released a novel AI training framework named
This framework is specifically designed for "dense image captioning," aiming to empower AI to accurately capture and articulate fine-grained details—like "a red apple on the wooden table" or "a pedestrian in the distance"—rather than offering only generic summaries.
Reinforcement Learning with Major Impact: Qwen2.5 Serves as the "Referee"
Traditional image captioning often depends on costly human annotation or large models prone to hallucination, resulting in inconsistent data quality. The Apple research team addressed this with an innovative reinforcement learning approach. The system first uses GPT-4 and Gemini 1.5 Pro to generate candidate descriptions. Gemini 1.5 Pro then refines the scoring criteria, while the Qwen2.5 model acts as a referee, providing scores and feedback.
This structured, precise feedback allows the training model to clearly identify and correct errors, achieving higher descriptive accuracy even with a smaller parameter count.
The Compact Model Advantage: Lower Hallucination Rates Surpass Trillion-Parameter Models
The RubiCap series models (ranging from 2 billion to 7 billion parameters) trained on this framework demonstrated exceptional efficiency in evaluations. Experimental data reveals that the 7-billion-parameter RubiCap model achieved top scores in blind tests, with a hallucination error rate lower than a leading 720-billion-parameter large model. Remarkably, the 3-billion-parameter mini version even outperformed its 7-billion-parameter counterpart on certain metrics.








 DeepMind CEO Hassabis: I sleep six hours a day, usually feel energetic around 1 a.m.
Fortune recently featured an interview with Demis Hassabis, CEO of Google DeepMind, revealing his unconventional approach to rest and productivity. Hassabis disclosed that he sleeps very little, structuring his waking hours into two distinct work blo
 OpenAI, Anthropic Vie for Market Share Despite Revenue Shortfalls
Despite recent reports suggesting OpenAI missed revenue targets, creating pressure on tech stocks this Tuesday, private AI lab investors remain resilient. Seasoned backers have confirmed they will not reduce investment despite negative media coverage
California AV Compliance: A New Era of Tickets, Geofences, and 1M Miles
Guident operates an AuveTech shuttle in South Florida, managing a four-mile route in West Palm Beach and a one-mile route in Boca Raton using its remote monitoring technology. | Credit: GuidentCalifornia is redefining the regulatory landscape for dri

2026 Latest Best Top-rated AI Stem Separation Tools Curated for Remix Production, Sampling Prep, and Karaoke Masters. These powerful game-changing tools offer real-world tests to deliver precise audio isolation, boosting productivity significantly. XIX.AI provides a weekly updated free vs paid comparison guide to help you find the must-try solution that suits your needs. Explore now to unlock your AI edge.
8 tools
xix.ai

2026 Latest Best AI SQL Copilots Ranked Top-Rated! XIX.AI curates a powerful game-changing collection for weekly updated real-world tests. These must-try tools help you generate accurate revenue dashboards, analyze sales funnels, and track product metrics swiftly, boosting productivity massively. Explore now to Discover your perfect tool for data-driven decision making! 238 characters
9 tools
xix.ai

2026 Latest Best Top-Rated AI Melody Writing Tools for Song Drafts! XIX.AI has curated a highly powerful game-changing collection that goes through rigorous real-world tests to deliver the best writing experience. You can find detailed free vs paid comparisons, accurate rankings, and must-try options designed to help you create stunning song drafts effortlessly and boost your creative productivity significantly. Explore now to discover your perfect tool!
8 tools
xix.ai

2026 Latest Best Top-rated AI Conversation Trainer Tools for Interview Practice are here on XIX.AI! This curated collection features powerful, game-changing tools that go through rigorous real-world tests to deliver accurate feedback. You’ll find a free vs paid comparison and detailed rankings to help you choose the must-try option that boosts your confidence and skills. Explore now to Discover your perfect tool for interview success!
12 tools
xix.ai

2026 Latest Best Top-rated AI Style Transfer Tools for Creative Experiments! XIX.AI has curated a powerful, game-changing collection of must-try tools that deliver exceptional results through real-world tests and rigorous rankings. These top solutions help creatives boost productivity significantly by accelerating content creation and unlocking endless creative possibilities. Explore now to discover your perfect tool and start creating today!
9 tools
xix.ai

2026 Latest Best Top-Rated AI Dialogue Bubble Tools for Visual Storytelling are here on XIX.AI! This curated collection features powerful, game-changing tools that help creators boost productivity and overcome creative bottlenecks. Get a free vs paid comparison, see real-world tests, and check the latest rankings to find the must-try solutions perfect for crafting engaging visual narratives. Explore now to discover your ideal tool!
10 tools
xix.ai












