


 首頁
Bytedance加入DeepFake AI視頻市場
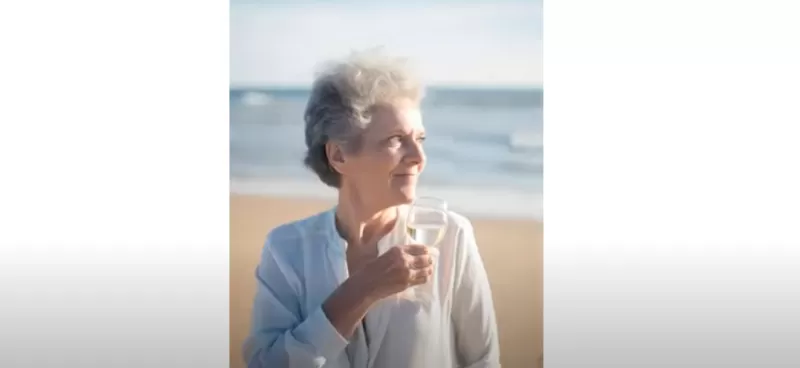
字節跳動,TikTok背後的公司,剛剛展示了他們最新的AI創作OmniHuman-1,真是令人震撼。這套新系統能快速生成極為逼真的影片,只需一張參考圖像和一些音頻即可。很酷的是,你可以調整影片的長寬比,甚至稍微改變主體的身體比例。現在,OmniHuman-1並非完美無缺,但我要說,它比我們見過的其他深偽技術進步了一大步。
相關文章
 Google Vids 推出新功能,讓使用者能成為由 AI 生成的客製化影片中的主角
儘管 OpenAI 的 Sora 已停止服務,但 Google 認為,市場對能讓使用者在自己所製作的 AI 生成影片中擔任主角的工具,仍存在強勁需求。週四,該公司發布了 Google Vids 的更新,新增了一項功能,可根據使用者上傳的自拍照和語音錄製,創建個人化的數位化身。此外,Google 正將其多模態 AI 模型 Gemini Omni 整合至 Vids 中。透過此整合,使用者可結合文字描述
OpenAI 簡化了驗證 AI 生成圖像的流程
隨著 AI 影像生成工具在網路上日益普及且日趨精進,區分真實影像與偽造影像的難度也前所未見地提高。週二,OpenAI 公布了兩項新措施以應對此問題。該公司已採用開放式的 C2PA 標準,該標準會在元資料中嵌入明確訊號,標示該影像是由 AI 生成的。此外,OpenAI 正與 Google 合作,將名為 SynthID 的隱形浮水印整合至影像中——此浮水印設計上更難被偵測,若惡意行為者試圖掩蓋蹤跡,更
隨著創作者們尋求對 AI 媒體的掌控權,ComfyUI 估值突破 5 億美元
新創公司 ComfyUI 透過基於節點的工作流程,讓創作者能精確控制擴散模型產出的圖像、影片及音訊,該公司已以 5 億美元估值完成 3,000 萬美元融資。本輪融資由 Craft Ventures 領投,Pace Capital、Chemistry 及 TruArrow 共同參與。ComfyUI 於 2023 年擴散模型剛問世不久時,以開源專案的形式啟動。當時,像 Midjourney 和 Ope
相關專題推薦
視頻創作
 適用於 Reels、Shorts 及產品上市活動的 AI 短影片吸睛開場生成器
2026 年最新最佳 AI 短影片開場白生成器,適用於 Reels、Shorts 及產品上市活動!XIX.AI 嚴選備受好評、功能強大且能顛覆遊戲規則的工具,這些工具皆經過實際測試,能帶來絕對值得一試的成果。本頁面每週更新,提供免費與付費版本的比較排行榜,助您找到提升內容創意與生產力的完美解決方案。 立即探索,釋放您的 AI 競爭優勢!
 11 個工具
 xix.ai
寫作
適用於長篇寫作的 AI 文章大綱工具
2026 年最新、最受好評的長文寫作 AI 大綱工具!這份精選清單收錄了強大且具顛覆性的工具,能透過實際測試生成精準、結構化的大綱,大幅提升寫作效率。XIX.AI 正是這份菁英名單中的一員。 獲取免費版與付費版的比較指南,助您挑選最合適的工具。立即探索,釋放您的 AI 優勢!
9 個工具
xix.ai
聊天機器人
用於語言練習、面試準備和日常流利度的最佳 AI 角色扮演聊天應用
2026 年最新最佳頂級評分 AI 角色扮演聊天應用,用於語言練習、面試準備和日常流利度!XIX.AI 精心策劃了一個強大的變革性合集,提供免費與付費對比、真實世界測試以及每週更新的排名。這些必試工具可幫助您提升寫作技能,克服流利度挑戰,並提高所有日常場景下的溝通效率。立即探索,發現您語言成長的完美工具!
10 個工具
xix.ai
音樂創作
用於混音製作、取樣準備及卡拉OK母帶處理的 AI 聲部分離工具
2026年最新、最優秀且評分最高的AI音軌分離工具彙總,專為混音製作、取樣準備以及卡拉OK音訊處理而設計。這些功能強大的創新工具經過實際測試,能夠實現精準的音訊分離,顯著提升工作效率。XIX.AI每週都會更新免費的付費產品對比指南,幫助您找到最適合自身需求的工具。立即探索,發揮您的AI優勢。
8 個工具
xix.ai
數據分析
用於收入看板、轉化漏斗分析及產品指標分析的 AI SQL 助手
2026年最新最優秀的AI SQL輔助工具排名揭曉!XIX.AI精心挑選了一系列功能強大的工具,這些工具會定期更新,並透過真實的場景測試來驗證其效能。使用這些值得嘗試的工具,您可以快速生成精準的收入分析報表、分析銷售流程,並追蹤產品各項指標,從而大幅提升工作效率。立即探索,找到最適合您的資料驅動決策工具!238個字元
9 個工具
xix.ai
音樂創作
最佳用於歌曲草稿的 AI 旋律創作工具
2026 年最新最佳頂級評分 AI 旋律創作工具,助力歌曲草稿創作!XIX.AI 精心策劃了一套極具影響力且經過嚴格真實世界測試的變革性合集,旨在提供最佳的創作體驗。您可以找到詳細的免費與付費版對比、精準的排名以及必試選項,這些工具旨在幫助您輕鬆創作出令人驚豔的歌曲草稿,並顯著提升您的創意生產力。立即探索,發現您的完美工具!
8 個工具
xix.ai

 評論 (48)
0/500
![BrianLewis]()
This AI from ByteDance is wild! OmniHuman-1 making videos from just one photo and audio is next-level. Imagine the creative stuff we could do with this, but kinda scary how real it looks. 😳 Anyone else worried about deepfakes getting out of hand?
![NicholasHernández]()
ByteDance's OmniHuman-1 is wild! Turning one photo into a lifelike video is straight-up sci-fi. But, man, this deepfake stuff could get messy fast—imagine fake celeb scandals everywhere! 😬
![HarryClark]()
ByteDance's OmniHuman-1 is wild! Turning one photo into a lifelike video with just audio is next-level. But, like, how long until we can't trust any video online? 😅 Kinda scary thinking about deepfake chaos in elections or ads.
![RichardJackson]()
ByteDanceのOmniHuman-1はすごいです!一枚の画像と音声だけで超リアルなビデオを作れます。アスペクト比を変更できるのはいい機能です。ただ、ビデオが時々あまりにも完璧すぎて、ちょっと気持ち悪いです。でも、ビデオコンテンツには革命的です!🎥
![CharlesYoung]()
El OmniHuman-1 de ByteDance es alucinante! Puede crear videos super realistas a partir de solo una imagen y algo de audio. La capacidad de cambiar la proporción del video es un buen toque. Pero a veces los videos parecen demasiado perfectos, casi espeluznantes. Aún así, es un cambio de juego para el contenido de video! 🎥
![GaryWilson]()
ByteDance의 OmniHuman-1 정말 대단해요! 한 장의 이미지와 음성만으로 초현실적인 비디오를 만들 수 있어요. 아스펙트 비율을 변경할 수 있는 기능도 좋아요. 다만, 비디오가 때때로 너무 완벽해서 좀 섬뜩해요. 그래도 비디오 콘텐츠에는 혁신적이에요! 🎥
字節跳動,TikTok背後的公司,剛剛展示了他們最新的AI創作OmniHuman-1,真是令人震撼。這套新系統能快速生成極為逼真的影片,只需一張參考圖像和一些音頻即可。很酷的是,你可以調整影片的長寬比,甚至稍微改變主體的身體比例。現在,OmniHuman-1並非完美無缺,但我要說,它比我們見過的其他深偽技術進步了一大步。








 Google Vids 推出新功能,讓使用者能成為由 AI 生成的客製化影片中的主角
儘管 OpenAI 的 Sora 已停止服務,但 Google 認為,市場對能讓使用者在自己所製作的 AI 生成影片中擔任主角的工具,仍存在強勁需求。週四,該公司發布了 Google Vids 的更新,新增了一項功能,可根據使用者上傳的自拍照和語音錄製,創建個人化的數位化身。此外,Google 正將其多模態 AI 模型 Gemini Omni 整合至 Vids 中。透過此整合,使用者可結合文字描述
 OpenAI 簡化了驗證 AI 生成圖像的流程
隨著 AI 影像生成工具在網路上日益普及且日趨精進,區分真實影像與偽造影像的難度也前所未見地提高。週二,OpenAI 公布了兩項新措施以應對此問題。該公司已採用開放式的 C2PA 標準,該標準會在元資料中嵌入明確訊號,標示該影像是由 AI 生成的。此外,OpenAI 正與 Google 合作,將名為 SynthID 的隱形浮水印整合至影像中——此浮水印設計上更難被偵測,若惡意行為者試圖掩蓋蹤跡,更
 隨著創作者們尋求對 AI 媒體的掌控權,ComfyUI 估值突破 5 億美元
新創公司 ComfyUI 透過基於節點的工作流程,讓創作者能精確控制擴散模型產出的圖像、影片及音訊,該公司已以 5 億美元估值完成 3,000 萬美元融資。本輪融資由 Craft Ventures 領投,Pace Capital、Chemistry 及 TruArrow 共同參與。ComfyUI 於 2023 年擴散模型剛問世不久時,以開源專案的形式啟動。當時,像 Midjourney 和 Ope

2026 年最新最佳 AI 短影片開場白生成器,適用於 Reels、Shorts 及產品上市活動!XIX.AI 嚴選備受好評、功能強大且能顛覆遊戲規則的工具,這些工具皆經過實際測試,能帶來絕對值得一試的成果。本頁面每週更新,提供免費與付費版本的比較排行榜,助您找到提升內容創意與生產力的完美解決方案。 立即探索,釋放您的 AI 競爭優勢!
11 個工具
xix.ai

2026 年最新、最受好評的長文寫作 AI 大綱工具!這份精選清單收錄了強大且具顛覆性的工具,能透過實際測試生成精準、結構化的大綱,大幅提升寫作效率。XIX.AI 正是這份菁英名單中的一員。 獲取免費版與付費版的比較指南,助您挑選最合適的工具。立即探索,釋放您的 AI 優勢!
9 個工具
xix.ai

2026 年最新最佳頂級評分 AI 角色扮演聊天應用,用於語言練習、面試準備和日常流利度!XIX.AI 精心策劃了一個強大的變革性合集,提供免費與付費對比、真實世界測試以及每週更新的排名。這些必試工具可幫助您提升寫作技能,克服流利度挑戰,並提高所有日常場景下的溝通效率。立即探索,發現您語言成長的完美工具!
10 個工具
xix.ai

2026年最新、最優秀且評分最高的AI音軌分離工具彙總,專為混音製作、取樣準備以及卡拉OK音訊處理而設計。這些功能強大的創新工具經過實際測試,能夠實現精準的音訊分離,顯著提升工作效率。XIX.AI每週都會更新免費的付費產品對比指南,幫助您找到最適合自身需求的工具。立即探索,發揮您的AI優勢。
8 個工具
xix.ai

2026年最新最優秀的AI SQL輔助工具排名揭曉!XIX.AI精心挑選了一系列功能強大的工具,這些工具會定期更新,並透過真實的場景測試來驗證其效能。使用這些值得嘗試的工具,您可以快速生成精準的收入分析報表、分析銷售流程,並追蹤產品各項指標,從而大幅提升工作效率。立即探索,找到最適合您的資料驅動決策工具!238個字元
9 個工具
xix.ai

2026 年最新最佳頂級評分 AI 旋律創作工具,助力歌曲草稿創作!XIX.AI 精心策劃了一套極具影響力且經過嚴格真實世界測試的變革性合集,旨在提供最佳的創作體驗。您可以找到詳細的免費與付費版對比、精準的排名以及必試選項,這些工具旨在幫助您輕鬆創作出令人驚豔的歌曲草稿,並顯著提升您的創意生產力。立即探索,發現您的完美工具!
8 個工具
xix.ai

This AI from ByteDance is wild! OmniHuman-1 making videos from just one photo and audio is next-level. Imagine the creative stuff we could do with this, but kinda scary how real it looks. 😳 Anyone else worried about deepfakes getting out of hand?
ByteDance's OmniHuman-1 is wild! Turning one photo into a lifelike video is straight-up sci-fi. But, man, this deepfake stuff could get messy fast—imagine fake celeb scandals everywhere! 😬
ByteDance's OmniHuman-1 is wild! Turning one photo into a lifelike video with just audio is next-level. But, like, how long until we can't trust any video online? 😅 Kinda scary thinking about deepfake chaos in elections or ads.
ByteDanceのOmniHuman-1はすごいです!一枚の画像と音声だけで超リアルなビデオを作れます。アスペクト比を変更できるのはいい機能です。ただ、ビデオが時々あまりにも完璧すぎて、ちょっと気持ち悪いです。でも、ビデオコンテンツには革命的です!🎥
El OmniHuman-1 de ByteDance es alucinante! Puede crear videos super realistas a partir de solo una imagen y algo de audio. La capacidad de cambiar la proporción del video es un buen toque. Pero a veces los videos parecen demasiado perfectos, casi espeluznantes. Aún así, es un cambio de juego para el contenido de video! 🎥
ByteDance의 OmniHuman-1 정말 대단해요! 한 장의 이미지와 음성만으로 초현실적인 비디오를 만들 수 있어요. 아스펙트 비율을 변경할 수 있는 기능도 좋아요. 다만, 비디오가 때때로 너무 완벽해서 좀 섬뜩해요. 그래도 비디오 콘텐츠에는 혁신적이에요! 🎥












