


 Home

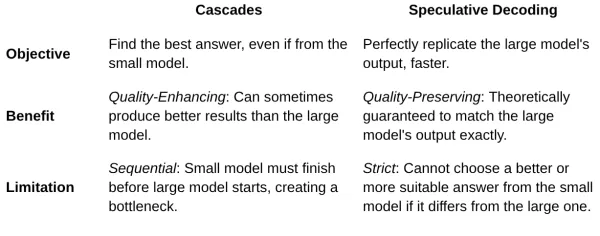
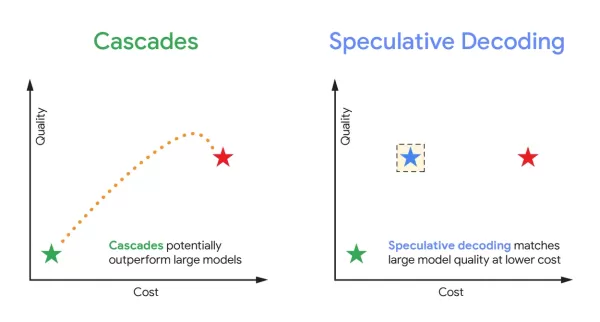
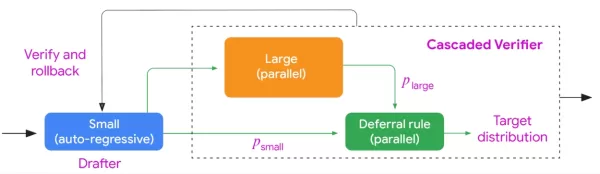
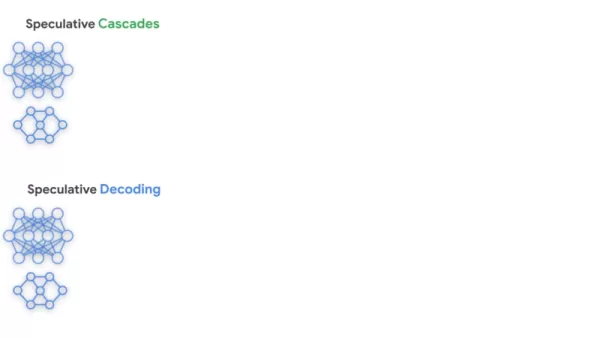
Researchers propose "speculative cascades," merging speculative decoding and standard cascades to improve LLM efficiency. The method uses a smaller model to draft outputs and a deferral rule to decide whether to accept or pass tasks to a larger model. Tests show it achieves better speed-quality trade-offs than standalone techniques, optimizing cost and performance across tasks like summarization, reasoning, and coding.
Comments (0)
0/300






