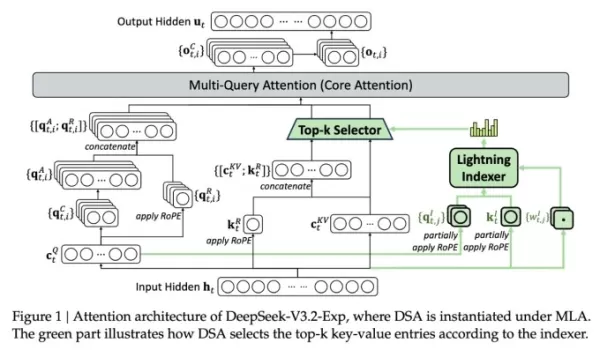
DeepSeek researchers released V3.2-exp, a model with DeepSeek Sparse Attention to cut long-context inference costs by up to 50%, using a lightning indexer and token selection system. Open-weight on Hugging Face, it aims to optimize transformer efficiency.
By clicking "Accept All Cookies", you agree to the storing of cookies on your device to enhance site navigation, analyze site usage, and assist in our marketing efforts.Privacy Policy Notice
When you visit any website, it may store or retrieve information on your browser, mostly in the form of cookies. This information might be about you, your preferences or your device and is mostly used to make the site work as you expect it to. The information does not usually directly identify you, but it can give you a more personalized web experience. Because we respect your right to privacy, you can choose not to allow some types of cookies. Click on the different category headings to find out more and change our default settings.However, blocking some types of cookies may impact your experience of the site and the services we are able to offer. Privacy PolicyStatement
Manage Preferences
Strictly Necessary Cookie
Always Active
These cookies are necessary for the website to function and cannot be switched off in our systems. They are usually only set in response to actions made by you which amount to a request for services, such as setting your privacy preferences, logging in or filling in forms. You can set your browser to block or alert you about these cookies, but some parts of the site will not then work. These cookies do not store any personally identifiable information.



 Home