


 Home
Tealium: Why RAG Quality Depends on Real-Time Data
![]()
Freddy Berlanti, Principal Product Manager of Applied AI at Tealium, explores retrieval-augmented generation (RAG). Image: Getty Images
Freddy Berlanti, Principal Product Manager of Applied AI at Tealium, breaks down the critical divide between RAG systems that deliver value and those that silently undermine user trust
Most enterprise retrieval-augmented generation (RAG) systems retrieve only a snapshot of the customer: a vector store indexed last Tuesday, a knowledge base syncing overnight, or a profile reflecting who the user was 12 hours ago. That gap separates RAG systems that work from those that quietly erode trust.
It’s 8:47pm on a Thursday. A customer adds another item to the cart, pushing the total past the free shipping threshold, then opens support chat and asks whether shipping is included.
The agent answers within milliseconds. It is fluent, polite, well cited—and wrong—because the profile it retrieved was assembled before the cart changed. By the time batch-indexed data catches up, the moment it was meant to inform has already passed.
Two distinct quantities govern that exchange, but most production systems measure only one. Response latency is the time between the question and the answer, and teams measure it obsessively. Age of information, a metric formalized by Kaul, Yates and Gruteser, measures how old a fact is when the system acts on it. Put simply: how stale was the context when you used it?
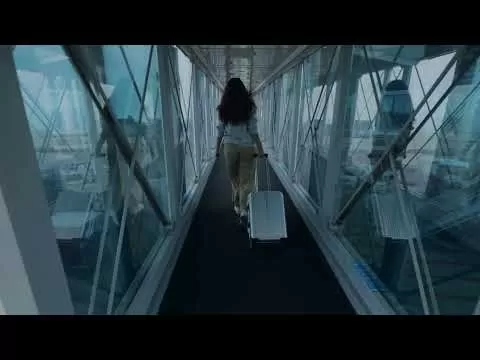
In this example, response latency was less than a second, but the information was hours old. The system was fast without being current. And only one of those numbers appeared on the dashboard.
That distinction matters because a fast answer based on stale customer data is still the wrong answer. For customer-facing RAG, speed and freshness are two different problems, and optimizing one does not guarantee the other.
The two are independent, and under load, they can move in opposite directions. More frequent updates do not always mean fresher information. Beyond a certain point, updates queue up, making the newest available fact older, not newer. Nightly batch is simply the extreme case: a system operating on a day-old view of the world. The fix is not moving more data on the same schedule. It is moving the changes that matter as they happen, which requires a different architecture, not just a faster one.
RAG earned its place by fixing the closed-book problem. Rather than answering from memory alone, the system looks up the relevant material first, then answers from what it found. That material is the corpus. Get the corpus right and the model stops improvising.
For an internal knowledge assistant, a corpus that syncs overnight is fine. A customer mid-session is a different problem. The cart just crossed a threshold, and an agent has to decide right now whether to offer free shipping or hold the line. A snapshot taken before dawn is not a limitation to be tuned away later; it is the wrong architecture, because by the time batch-indexed data catches up, the opportunity it was meant to inform has already passed.
Batch RAG retrieves a memory; live RAG retrieves the customer
The failures are small, plausible, and corrosive. They rarely trigger alerts or bug reports; users simply learn not to trust the system and stop using it. By the time that shows up on a dashboard, it looks like an adoption problem with no obvious cause.
The fix starts before any tooling decision. It’s a service-level agreement, written per use case, that answers three questions: How current must the context be? How fast must the answer arrive? When should the system stop and hand the conversation to a human?
Cart state needs seconds. Product content tolerates minutes. Policy can live with daily. Those numbers stop being a preference and become a design constraint: they decide the architecture, and they decide the bill. The common mistake is treating freshness as a single global setting applied evenly across everything. Freshness is a budget. Spend it where it changes a decision, and stop paying for it where it does not.
For customer-facing agents, the corpus is the customer.
That means identity is resolved across devices and channels, so all touchpoints are understood as one person. It means consent bound to the profile itself, so every downstream lookup is permissioned by construction rather than by a policy document somebody hopes was read.
It also means giving up the nightly rebuild. Change data capture, the practice of streaming only what changed instead of reloading everything, re-embeds a single profile in seconds rather than reprocessing millions of them. Retrieval then runs hybrid: dense vector search for meaning, keyword search for the exact strings that matter like SKUs and order numbers, the two fused by rank, with a re-ranking pass over the finalists. Hot and cold tiers keep the bill honest, so you buy second-level recency for the handful of attributes that actually change a decision and daily freshness for everything else.
The always-current stack, read left to right, with the measurement loop underneath
Connecting every agent to every data source by hand creates a web of integrations, each with its own authentication, schema changes and failure points. That complexity is why so many promising pilots struggle to scale.
The Model Context Protocol (MCP), an open standard for connecting agents to tools and data, turns that seam into a port. Wire a source once and any compliant agent can discover it, with schemas and permissions attached. A gateway sits in front of it: validating inbound calls, redacting by consent, and writing the audit trail. The unglamorous half is what gets you into production.
None of this survives without measurement, and a single number will not do it. One satisfaction score tells you something is wrong. Three separate dashboards tell you what.
Retrieval quality asks whether you fetched the right context at all: context precision, context recall, staleness lag. No model is needed to answer that. Generation quality asks whether the model used what it was handed, faithfully: answer relevance and citation coverage, scored by a judge calibrated against human review. Business outcomes ask whether any of it mattered: resolution time, containment, cost, CSAT. Kept separate, a slipping metric points straight at the layer that needs the work, whether that is the data, the model or the workflow.
Three dashboards: a slip tells you which layer to fix
Then, ship narrow. Shadow one bounded use case against real traffic, tune it until it holds the SLA you wrote down, serve it with escalation switched on, and only then widen. The stall pattern is the exact reverse, and it is the most common project shape in the industry right now: tool first, data later, metrics never.
Models improve for everyone on the same day. Whatever edge a frontier release buys you this quarter, your competitor buys next quarter at list price. What they cannot buy is the currency, the governance, and the identity of the context your agents retrieve at the moment they answer.
The model is the brain. The context is the memory. Only one of those is yours. Check out the full ebook.
Related article
 How Unitree is Shaping the Future of Humanoid Robotics
Unitree’s New Creature of Embodied AI with ultra-wide 4D LiDAR technology for advanced real-world navigation. Credit: UnitreeWang Xingxing, CEO of Unitree, targets world model breakthroughs to help humanoid machines execute 80% of tasks when placed i
Why Cognition Bought Poke: AI Personality Is Becoming a Competitive Advantage
Poke, the AI assistant designed to chat like a friend, is taking its next major step. The Interaction Company of California, the startup behind Poke, has been acquired by AI coding firm Cognition in a transaction valuing the company in the low nine f
Google Tests Remy AI Agent for Gemini as Focus Shifts to User Control
According to Business Insider, Google is testing Remy, a new AI personal agent for Gemini. This tool aims to execute tasks on behalf of users, streamlining both professional workflows and daily routines.Currently, Remy is undergoing testing in an int
Related Special Topic Recommendations
writing
 Best AI Editing Tools for Clear Business Writing
2026 Latest Best Top-rated AI Editing Tools for Clear Business Writing are here on XIX.AI! This curated list features powerful, game-changing solutions that help you boost writing efficiency significantly through real-world tests and rigorous rankings. You’ll find a free vs paid comparison to help you choose the perfect fit. Explore now and Unlock your AI edge!
 10 tools
 xix.ai
Animation Creation
Best AI Motion Cleanup Tools for Mocap Retargeting in Shorts, Ads, and Game Trailers
2026 Latest Best Top-rated AI Motion Cleanup Tools for Mocap Retargeting in Shorts, Ads, and Game Trailers! XIX.AI has curated a powerful game-changing collection featuring weekly updated rankings, free vs paid comparison, and real-world tests to help you find the must-try solution that boosts productivity and unlocks your creative edge. Explore now to discover your perfect tool for flawless motion edits.
9 tools
xix.ai
Comic Creation
Best AI Manga Background Generators for Serialized Stories
2026 Latest Best Top-rated AI Manga Background Generators for Serialized Stories! This curated list features powerful game-changing tools that help creators craft stunning visual content fast, boosting productivity significantly. Every option has undergone real-world tests to ensure top quality. Check out the free vs paid comparison and rankings to find your perfect fit. Explore now at XIX.AI to unlock your AI edge in manga creation.
9 tools
xix.ai
chatbot
Best AI Chat Companions: Hold Natural Talks with Long-Term Memory
2026 Latest Best AI Chat Companions Ranking features top-rated, powerful tools known for their ability to hold natural conversations and retain long-term memory. This curated list includes must-try options across free and paid tiers, backed by real-world tests and weekly updated rankings. XIX.AI stands out as a trusted choice in this elite collection. Explore now to discover your perfect AI chat companion and unlock your productivity edge today.
11 tools
xix.ai
Animation Creation
Best AI Animation Generators: Turn Ideas into Motion Clips Fast
2026 Latest Best Top-Rated AI Animation Generators! XIX.AI curates a powerful game-changing collection of must-try tools for turning creative ideas into high-quality motion clips swiftly. Each option has undergone rigorous real-world tests, featuring detailed free vs paid comparison and updated weekly rankings to help you find the perfect fit for boosting your animation productivity. Explore now to unlock your AI edge!
11 tools
xix.ai
Text-to-speech
Top Multilingual AI Voice Generators: Localize Audio at Scale
2026 Latest Top-Rated Best Multilingual AI Voice Generators for Large-Scale Audio Localization. This curated list features powerful, game-changing tools that deliver high-quality localized audio fast. Each option has undergone rigorous real-world tests to ensure reliability. Get a free vs paid comparison and discover the perfect fit for your projects. Explore now at XIX.AI to unlock your AI edge.
18 tools
xix.ai

 Comments (0)
0/500
Freddy Berlanti, Principal Product Manager of Applied AI at Tealium, explores retrieval-augmented generation (RAG). Image: Getty Images
Freddy Berlanti, Principal Product Manager of Applied AI at Tealium, breaks down the critical divide between RAG systems that deliver value and those that silently undermine user trust
Most enterprise retrieval-augmented generation (RAG) systems retrieve only a snapshot of the customer: a vector store indexed last Tuesday, a knowledge base syncing overnight, or a profile reflecting who the user was 12 hours ago. That gap separates RAG systems that work from those that quietly erode trust.
It’s 8:47pm on a Thursday. A customer adds another item to the cart, pushing the total past the free shipping threshold, then opens support chat and asks whether shipping is included.
The agent answers within milliseconds. It is fluent, polite, well cited—and wrong—because the profile it retrieved was assembled before the cart changed. By the time batch-indexed data catches up, the moment it was meant to inform has already passed.
Two distinct quantities govern that exchange, but most production systems measure only one. Response latency is the time between the question and the answer, and teams measure it obsessively. Age of information, a metric formalized by Kaul, Yates and Gruteser, measures how old a fact is when the system acts on it. Put simply: how stale was the context when you used it?
In this example, response latency was less than a second, but the information was hours old. The system was fast without being current. And only one of those numbers appeared on the dashboard.
That distinction matters because a fast answer based on stale customer data is still the wrong answer. For customer-facing RAG, speed and freshness are two different problems, and optimizing one does not guarantee the other.
The two are independent, and under load, they can move in opposite directions. More frequent updates do not always mean fresher information. Beyond a certain point, updates queue up, making the newest available fact older, not newer. Nightly batch is simply the extreme case: a system operating on a day-old view of the world. The fix is not moving more data on the same schedule. It is moving the changes that matter as they happen, which requires a different architecture, not just a faster one.
RAG earned its place by fixing the closed-book problem. Rather than answering from memory alone, the system looks up the relevant material first, then answers from what it found. That material is the corpus. Get the corpus right and the model stops improvising.
For an internal knowledge assistant, a corpus that syncs overnight is fine. A customer mid-session is a different problem. The cart just crossed a threshold, and an agent has to decide right now whether to offer free shipping or hold the line. A snapshot taken before dawn is not a limitation to be tuned away later; it is the wrong architecture, because by the time batch-indexed data catches up, the opportunity it was meant to inform has already passed.
Batch RAG retrieves a memory; live RAG retrieves the customer
The failures are small, plausible, and corrosive. They rarely trigger alerts or bug reports; users simply learn not to trust the system and stop using it. By the time that shows up on a dashboard, it looks like an adoption problem with no obvious cause.
The fix starts before any tooling decision. It’s a service-level agreement, written per use case, that answers three questions: How current must the context be? How fast must the answer arrive? When should the system stop and hand the conversation to a human?
Cart state needs seconds. Product content tolerates minutes. Policy can live with daily. Those numbers stop being a preference and become a design constraint: they decide the architecture, and they decide the bill. The common mistake is treating freshness as a single global setting applied evenly across everything. Freshness is a budget. Spend it where it changes a decision, and stop paying for it where it does not.
For customer-facing agents, the corpus is the customer.
That means identity is resolved across devices and channels, so all touchpoints are understood as one person. It means consent bound to the profile itself, so every downstream lookup is permissioned by construction rather than by a policy document somebody hopes was read.
It also means giving up the nightly rebuild. Change data capture, the practice of streaming only what changed instead of reloading everything, re-embeds a single profile in seconds rather than reprocessing millions of them. Retrieval then runs hybrid: dense vector search for meaning, keyword search for the exact strings that matter like SKUs and order numbers, the two fused by rank, with a re-ranking pass over the finalists. Hot and cold tiers keep the bill honest, so you buy second-level recency for the handful of attributes that actually change a decision and daily freshness for everything else.
The always-current stack, read left to right, with the measurement loop underneath
Connecting every agent to every data source by hand creates a web of integrations, each with its own authentication, schema changes and failure points. That complexity is why so many promising pilots struggle to scale.
The Model Context Protocol (MCP), an open standard for connecting agents to tools and data, turns that seam into a port. Wire a source once and any compliant agent can discover it, with schemas and permissions attached. A gateway sits in front of it: validating inbound calls, redacting by consent, and writing the audit trail. The unglamorous half is what gets you into production.
None of this survives without measurement, and a single number will not do it. One satisfaction score tells you something is wrong. Three separate dashboards tell you what.
Retrieval quality asks whether you fetched the right context at all: context precision, context recall, staleness lag. No model is needed to answer that. Generation quality asks whether the model used what it was handed, faithfully: answer relevance and citation coverage, scored by a judge calibrated against human review. Business outcomes ask whether any of it mattered: resolution time, containment, cost, CSAT. Kept separate, a slipping metric points straight at the layer that needs the work, whether that is the data, the model or the workflow.
Three dashboards: a slip tells you which layer to fix
Then, ship narrow. Shadow one bounded use case against real traffic, tune it until it holds the SLA you wrote down, serve it with escalation switched on, and only then widen. The stall pattern is the exact reverse, and it is the most common project shape in the industry right now: tool first, data later, metrics never.
Models improve for everyone on the same day. Whatever edge a frontier release buys you this quarter, your competitor buys next quarter at list price. What they cannot buy is the currency, the governance, and the identity of the context your agents retrieve at the moment they answer.
The model is the brain. The context is the memory. Only one of those is yours. Check out the full ebook.








 How Unitree is Shaping the Future of Humanoid Robotics
Unitree’s New Creature of Embodied AI with ultra-wide 4D LiDAR technology for advanced real-world navigation. Credit: UnitreeWang Xingxing, CEO of Unitree, targets world model breakthroughs to help humanoid machines execute 80% of tasks when placed i
 Why Cognition Bought Poke: AI Personality Is Becoming a Competitive Advantage
Poke, the AI assistant designed to chat like a friend, is taking its next major step. The Interaction Company of California, the startup behind Poke, has been acquired by AI coding firm Cognition in a transaction valuing the company in the low nine f
Google Tests Remy AI Agent for Gemini as Focus Shifts to User Control
According to Business Insider, Google is testing Remy, a new AI personal agent for Gemini. This tool aims to execute tasks on behalf of users, streamlining both professional workflows and daily routines.Currently, Remy is undergoing testing in an int

2026 Latest Best Top-rated AI Editing Tools for Clear Business Writing are here on XIX.AI! This curated list features powerful, game-changing solutions that help you boost writing efficiency significantly through real-world tests and rigorous rankings. You’ll find a free vs paid comparison to help you choose the perfect fit. Explore now and Unlock your AI edge!
10 tools
xix.ai

2026 Latest Best Top-rated AI Motion Cleanup Tools for Mocap Retargeting in Shorts, Ads, and Game Trailers! XIX.AI has curated a powerful game-changing collection featuring weekly updated rankings, free vs paid comparison, and real-world tests to help you find the must-try solution that boosts productivity and unlocks your creative edge. Explore now to discover your perfect tool for flawless motion edits.
9 tools
xix.ai

2026 Latest Best Top-rated AI Manga Background Generators for Serialized Stories! This curated list features powerful game-changing tools that help creators craft stunning visual content fast, boosting productivity significantly. Every option has undergone real-world tests to ensure top quality. Check out the free vs paid comparison and rankings to find your perfect fit. Explore now at XIX.AI to unlock your AI edge in manga creation.
9 tools
xix.ai

2026 Latest Best AI Chat Companions Ranking features top-rated, powerful tools known for their ability to hold natural conversations and retain long-term memory. This curated list includes must-try options across free and paid tiers, backed by real-world tests and weekly updated rankings. XIX.AI stands out as a trusted choice in this elite collection. Explore now to discover your perfect AI chat companion and unlock your productivity edge today.
11 tools
xix.ai
2026 Latest Best Top-Rated AI Animation Generators! XIX.AI curates a powerful game-changing collection of must-try tools for turning creative ideas into high-quality motion clips swiftly. Each option has undergone rigorous real-world tests, featuring detailed free vs paid comparison and updated weekly rankings to help you find the perfect fit for boosting your animation productivity. Explore now to unlock your AI edge!
11 tools
xix.ai
2026 Latest Top-Rated Best Multilingual AI Voice Generators for Large-Scale Audio Localization. This curated list features powerful, game-changing tools that deliver high-quality localized audio fast. Each option has undergone rigorous real-world tests to ensure reliability. Get a free vs paid comparison and discover the perfect fit for your projects. Explore now at XIX.AI to unlock your AI edge.
18 tools
xix.ai












