


 Home
MiniMax Unveils H3 Multimodal Model, Cutting 15-Second 2K Audio-Visual Generation Costs to Under One-Third of Industry Standard
MiniMax has officially unveiled MiniMax H3, a general-purpose multimodal generation model designed to unify the understanding and creation of text, images, video, and audio. By bridging the historical divide between tasks and modalities in video generation, this release marks a pivotal shift from specialized tools to versatile, all-in-one assistants.
According to official specifications, H3 natively supports dual-channel audio-video output, capable of generating up to 15 seconds of 2K resolution content. Early invitation tests confirmed its commercial-grade stability in areas like instruction adherence, brand storytelling, and video-to-video action transfer. The model is already deployed across diverse sectors, including advertising, e-commerce, gaming, and UI design.
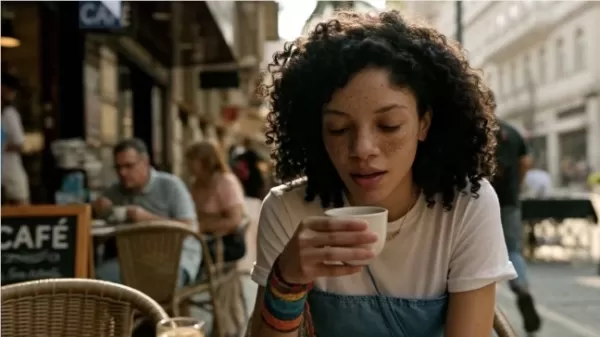
Technologically, H3 leverages Contextual Omni Representation, using natural language as a universal connector across modalities. Users can define complex interactions through simple prompts—for instance, instructing the model to apply a specific Hitchcock-style camera movement from one video to a character in another image while singing a tune from an audio clip. The system automatically handles the entire chain of comprehension and generation. Paired with its proprietary H3-VAE and In-context Regeneration technologies, H3 delivers 2K resolution at less than one-third the cost of leading competitors, and under half the cost for 768P output, offering the industry’s most cost-effective solution to date.
Notably, MiniMax plans to open-source the H3 model weights in the coming days, adhering to applicable laws and regulations. This marks the first time a major domestic video generation model has released its weights to the public, fostering open-source ecosystems and accelerating domestic chip adaptation. Designed from the ground up for compatibility with various local processors, this move significantly lowers technical barriers for domestic enterprises adopting multimodal AI.
MiniMax acknowledges that H3 still has room for growth regarding image detail and model scale. Future updates will focus on integrating capabilities between the H and M series models, continuously pushing the boundaries of performance through scaling.
Industry experts suggest that H3’s release and open-source availability could disrupt the long-standing dominance of closed-source models in video generation, speeding up the widespread adoption of multimodal AI applications.
Related article
 Instinct launches AI agent in group chats, including those with non-users
Instinct, the AI agent now valued at $10 billion following its latest funding round, is expanding into group chats. The startup announced on Monday that users can add the agent to conversations with friends, offering assistance in scenarios such as t
World Bank Urges Emerging Economies to Skip Big Models, Focus on Local Small Tools
The World Bank’s latest report charts a pragmatic course for developing economies: integrate artificial intelligence into public administration and commercial activities immediately, while tailoring existing solutions to local contexts. There is no n
OpenAI CEO Altman Cancels South Korea and Japan Visit Following the Birth of His Second Daughter
OpenAI CEO Sam Altman recently welcomed his second daughter, who was born prematurely, prompting the cancellation of his planned trip to South Korea and Japan scheduled for the 15th. While industry observers had speculated that the itinerary change m
Related Special Topic Recommendations
Design & Art
 Top AI Illustration Tools: Create Editorial Scenes and Cover Art Faster
2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
 10 tools
 xix.ai
Education and Learning
Top AI Tutors for Exam Prep: Practice Math, Science, and English
2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai
Finance
AI Budget Planning Tools for Personal Money Management
2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai
Health & Wellness
AI Sleep Tracking Assistants: Improve Recovery with Better Bedtime Habits
2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai
Data Analysis
AI SQL Copilots for Product and Revenue Analytics
2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai
Education and Learning
Best AI Homework Helpers That Teach: Learn Concepts, Not Just Answers
2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai

 Comments (0)
0/500
MiniMax has officially unveiled MiniMax H3, a general-purpose multimodal generation model designed to unify the understanding and creation of text, images, video, and audio. By bridging the historical divide between tasks and modalities in video generation, this release marks a pivotal shift from specialized tools to versatile, all-in-one assistants.
According to official specifications, H3 natively supports dual-channel audio-video output, capable of generating up to 15 seconds of 2K resolution content. Early invitation tests confirmed its commercial-grade stability in areas like instruction adherence, brand storytelling, and video-to-video action transfer. The model is already deployed across diverse sectors, including advertising, e-commerce, gaming, and UI design.
Technologically, H3 leverages Contextual Omni Representation, using natural language as a universal connector across modalities. Users can define complex interactions through simple prompts—for instance, instructing the model to apply a specific Hitchcock-style camera movement from one video to a character in another image while singing a tune from an audio clip. The system automatically handles the entire chain of comprehension and generation. Paired with its proprietary H3-VAE and In-context Regeneration technologies, H3 delivers 2K resolution at less than one-third the cost of leading competitors, and under half the cost for 768P output, offering the industry’s most cost-effective solution to date.
Notably, MiniMax plans to open-source the H3 model weights in the coming days, adhering to applicable laws and regulations. This marks the first time a major domestic video generation model has released its weights to the public, fostering open-source ecosystems and accelerating domestic chip adaptation. Designed from the ground up for compatibility with various local processors, this move significantly lowers technical barriers for domestic enterprises adopting multimodal AI.
MiniMax acknowledges that H3 still has room for growth regarding image detail and model scale. Future updates will focus on integrating capabilities between the H and M series models, continuously pushing the boundaries of performance through scaling.
Industry experts suggest that H3’s release and open-source availability could disrupt the long-standing dominance of closed-source models in video generation, speeding up the widespread adoption of multimodal AI applications.








 Instinct launches AI agent in group chats, including those with non-users
Instinct, the AI agent now valued at $10 billion following its latest funding round, is expanding into group chats. The startup announced on Monday that users can add the agent to conversations with friends, offering assistance in scenarios such as t
 World Bank Urges Emerging Economies to Skip Big Models, Focus on Local Small Tools
The World Bank’s latest report charts a pragmatic course for developing economies: integrate artificial intelligence into public administration and commercial activities immediately, while tailoring existing solutions to local contexts. There is no n
 OpenAI CEO Altman Cancels South Korea and Japan Visit Following the Birth of His Second Daughter
OpenAI CEO Sam Altman recently welcomed his second daughter, who was born prematurely, prompting the cancellation of his planned trip to South Korea and Japan scheduled for the 15th. While industry observers had speculated that the itinerary change m

2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
10 tools
xix.ai

2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai

2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai

2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai












