


 Home
GitHub to Use Copilot User Data for AI Training by Default
GitHub has announced an update to its code repository policy effective April 24, 2026, which will involve using user interaction data to train its AI models. This data collection applies to Copilot Free, Pro, and Pro+ users and includes model inputs and outputs, code snippets, contextual information, repository structures, and chat logs.
Mario Rodriguez, GitHub's Chief Product Officer, explained that leveraging this interaction data is intended to enhance the accuracy and security of the model's code suggestions. He noted that initial testing with Microsoft's internal data has already shown a significant improvement in suggestion acceptance rates. It is important to note that this policy operates on an "opt-out" basis, meaning affected users must manually adjust their privacy settings to disable data sharing. This approach has sparked considerable debate within the developer community regarding the definitions of private repositories and data ownership.
Currently, Copilot Business, Enterprise, and educational users are exempt from this change due to existing contractual agreements. GitHub stated that this update aligns with standard industry practices observed by other leading technology firms like Anthropic, JetBrains, and Microsoft. However, the inclusion of code from private repositories in training datasets raises fundamental questions about the traditional understanding of "privacy," even as GitHub maintains that the goal is to streamline and improve the development workflow.
Related article
 ChatGPT Gets Major Upgrade to Precisely Clone Individual Writing Styles
AI is evolving from generic utilities into personalized office partners that truly grasp your needs. ChatGPT Work, tailored for enterprise and professional environments, has recently received a major functional overhaul. Its standout feature is the a
Google AI Overview Introduces Hot News Carousel, Embedding Real-Time Breaking News in Summaries
On June 29, 2026, Google rolled out a significant search interface update for select users, introducing a "Top Stories" carousel directly within the "AI Overviews" module.SEO specialist Lily Ray first identified this feature on X, signaling a strateg
How to optimize SEO for Google Japan and Yahoo Japan
As an independent content creator who regularly handles a mix of old archival footage, user-generated clips, and compressed B-roll from various online sources, dealing with visual quality drops has always been a major headache. In fact, a recent repo
Related Special Topic Recommendations
Design & Art
 Top AI Illustration Tools: Create Editorial Scenes and Cover Art Faster
2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
 10 tools
 xix.ai
Education and Learning
Top AI Tutors for Exam Prep: Practice Math, Science, and English
2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai
Finance
AI Budget Planning Tools for Personal Money Management
2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai
Health & Wellness
AI Sleep Tracking Assistants: Improve Recovery with Better Bedtime Habits
2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai
Data Analysis
AI SQL Copilots for Product and Revenue Analytics
2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai
Education and Learning
Best AI Homework Helpers That Teach: Learn Concepts, Not Just Answers
2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai

 Comments (2)
0/500
![JuanMoore]()
Wait, so my code snippets are now training material? 🤔 I use Copilot for work, not to feed the machine. This feels like a betrayal of trust. If I wanted my private logic to be public knowledge, I'd just push to a public repo. The 'default' opt-out is a huge red flag for enterprise users. Hope they add a clear toggle to exclude sensitive data, otherwise I'm switching back to local models. #PrivacyMatters
![BrianWalker]()
Oh great, so now my messy code snippets are going to be used to train the AI without me even knowing? 🙄 Privacy is just a suggestion these days, huh?
GitHub has announced an update to its code repository policy effective April 24, 2026, which will involve using user interaction data to train its AI models. This data collection applies to Copilot Free, Pro, and Pro+ users and includes model inputs and outputs, code snippets, contextual information, repository structures, and chat logs.
Mario Rodriguez, GitHub's Chief Product Officer, explained that leveraging this interaction data is intended to enhance the accuracy and security of the model's code suggestions. He noted that initial testing with Microsoft's internal data has already shown a significant improvement in suggestion acceptance rates. It is important to note that this policy operates on an "opt-out" basis, meaning affected users must manually adjust their privacy settings to disable data sharing. This approach has sparked considerable debate within the developer community regarding the definitions of private repositories and data ownership.
Currently, Copilot Business, Enterprise, and educational users are exempt from this change due to existing contractual agreements. GitHub stated that this update aligns with standard industry practices observed by other leading technology firms like Anthropic, JetBrains, and Microsoft. However, the inclusion of code from private repositories in training datasets raises fundamental questions about the traditional understanding of "privacy," even as GitHub maintains that the goal is to streamline and improve the development workflow.








 ChatGPT Gets Major Upgrade to Precisely Clone Individual Writing Styles
AI is evolving from generic utilities into personalized office partners that truly grasp your needs. ChatGPT Work, tailored for enterprise and professional environments, has recently received a major functional overhaul. Its standout feature is the a
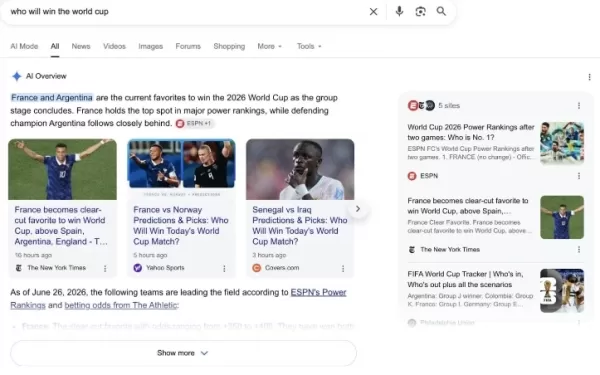 Google AI Overview Introduces Hot News Carousel, Embedding Real-Time Breaking News in Summaries
On June 29, 2026, Google rolled out a significant search interface update for select users, introducing a "Top Stories" carousel directly within the "AI Overviews" module.SEO specialist Lily Ray first identified this feature on X, signaling a strateg
 How to optimize SEO for Google Japan and Yahoo Japan
As an independent content creator who regularly handles a mix of old archival footage, user-generated clips, and compressed B-roll from various online sources, dealing with visual quality drops has always been a major headache. In fact, a recent repo

2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
10 tools
xix.ai

2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai

2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai

2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai

Wait, so my code snippets are now training material? 🤔 I use Copilot for work, not to feed the machine. This feels like a betrayal of trust. If I wanted my private logic to be public knowledge, I'd just push to a public repo. The 'default' opt-out is a huge red flag for enterprise users. Hope they add a clear toggle to exclude sensitive data, otherwise I'm switching back to local models. #PrivacyMatters
Oh great, so now my messy code snippets are going to be used to train the AI without me even knowing? 🙄 Privacy is just a suggestion these days, huh?












