


 Home
Alibaba Tongyi unveils voice model with 'FreeStyle' natural language control
Today, Alibaba Tongyi Lab's Speech Team introduced two groundbreaking voice generation models: Fun-CosyVoice3.5 and Fun-AudioGen-VD. The standout feature of these models is their support for "FreeStyle" commands. Instead of complex parameter adjustments, users can precisely control vocal expression styles or build intricate audio scenes from scratch using simple natural language descriptions.
Each model serves distinct purposes:
Fun-CosyVoice3.5: Multilingual Replication and Fine-Grained Control
This enhanced version of CosyVoice achieves core breakthroughs in understanding speech expression nuances.
Command-Driven Generation: Users can input instructions like "speak more confidently" or "slow down with emotional variation" for real-time vocal adjustments.
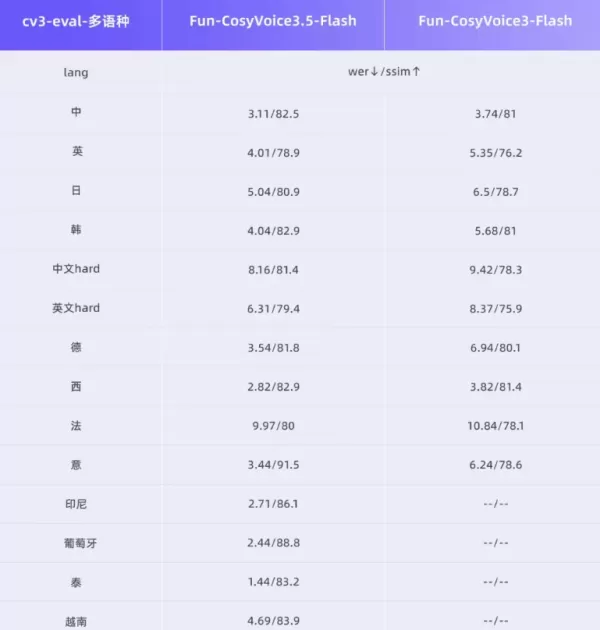
Language Expansion: Added support for Thai, Indonesian, Portuguese, and Vietnamese maintains industry-leading performance in transcription accuracy (WER) and voice similarity across 13 languages.
Rare Character Optimization: Specialized training reduced error rates for uncommon characters from 15.2% to 5.3%.
Performance Boost: First packet latency decreased by 35%, significantly enhancing real-time interaction fluidity.
Fun-AudioGen-VD: Comprehensive Sound Design
This model acts as an "audio director," generating integrated audio combining "characters + environments."
Voice Customization: Specify gender, age, accent, and detailed characteristics like "hoarse, deep, or low-pitched" voices.
Emotion and Role Play: Simulates roles including customer service agents, broadcasters, and children, even conveying complex states like "outward calm with internal tension."
Immersive Environments: Adds background sounds (battlefield chaos, café murmurs) and spatial effects (cathedral reverb, underwater acoustics) for full spatial simulation.
Tongyi Lab notes these models will democratize high-quality voice creation, offering powerful AI support for podcasting, game development, and film post-production.
Related article
 DeepMind CEO Hassabis: I sleep six hours a day, usually feel energetic around 1 a.m.
Fortune recently featured an interview with Demis Hassabis, CEO of Google DeepMind, revealing his unconventional approach to rest and productivity. Hassabis disclosed that he sleeps very little, structuring his waking hours into two distinct work blo
OpenAI, Anthropic Vie for Market Share Despite Revenue Shortfalls
Despite recent reports suggesting OpenAI missed revenue targets, creating pressure on tech stocks this Tuesday, private AI lab investors remain resilient. Seasoned backers have confirmed they will not reduce investment despite negative media coverage
California AV Compliance: A New Era of Tickets, Geofences, and 1M Miles
Guident operates an AuveTech shuttle in South Florida, managing a four-mile route in West Palm Beach and a one-mile route in Boca Raton using its remote monitoring technology. | Credit: GuidentCalifornia is redefining the regulatory landscape for dri
Related Special Topic Recommendations
writing
 AI Article Outline Tools for Long Form Writing
2026 Latest Best Top-Rated AI Article Outline Tools for Long Form Writing! This curated collection features powerful, game-changing tools that deliver accurate, structured outlines with real-world tests to boost writing efficiency significantly. XIX.AI is part of this elite selection. Get a free vs paid comparison to help you choose the perfect tool. Explore now and Unlock your AI edge!
 9 tools
 xix.ai
chatbot
Best AI Roleplay Chat Apps for Language Practice, Interview Prep, and Daily Fluency
2026 Latest Best Top-rated AI Roleplay Chat Apps for Language Practice, Interview Prep, and Daily Fluency! XIX.AI curates a powerful game-changing collection that offers free vs paid comparison, real-world tests, and updated rankings weekly. These must-try tools help you boost writing skills, overcome fluency challenges, and improve communication efficiency across all daily scenarios. Explore now to discover your perfect tool for language growth!
10 tools
xix.ai
Music composition
AI Stem Separation Tools for Remix Production, Sampling Prep, and Karaoke Masters
2026 Latest Best Top-rated AI Stem Separation Tools Curated for Remix Production, Sampling Prep, and Karaoke Masters. These powerful game-changing tools offer real-world tests to deliver precise audio isolation, boosting productivity significantly. XIX.AI provides a weekly updated free vs paid comparison guide to help you find the must-try solution that suits your needs. Explore now to unlock your AI edge.
8 tools
xix.ai
Data Analysis
AI SQL Copilots for Revenue Dashboards, Funnel Analysis, and Product Metrics
2026 Latest Best AI SQL Copilots Ranked Top-Rated! XIX.AI curates a powerful game-changing collection for weekly updated real-world tests. These must-try tools help you generate accurate revenue dashboards, analyze sales funnels, and track product metrics swiftly, boosting productivity massively. Explore now to Discover your perfect tool for data-driven decision making! 238 characters
9 tools
xix.ai
Music composition
Best AI Melody Writing Tools for Song Drafts
2026 Latest Best Top-Rated AI Melody Writing Tools for Song Drafts! XIX.AI has curated a highly powerful game-changing collection that goes through rigorous real-world tests to deliver the best writing experience. You can find detailed free vs paid comparisons, accurate rankings, and must-try options designed to help you create stunning song drafts effortlessly and boost your creative productivity significantly. Explore now to discover your perfect tool!
8 tools
xix.ai
chatbot
Best AI Conversation Trainer Tools for Interview Practice
2026 Latest Best Top-rated AI Conversation Trainer Tools for Interview Practice are here on XIX.AI! This curated collection features powerful, game-changing tools that go through rigorous real-world tests to deliver accurate feedback. You’ll find a free vs paid comparison and detailed rankings to help you choose the must-try option that boosts your confidence and skills. Explore now to Discover your perfect tool for interview success!
12 tools
xix.ai

 Comments (0)
0/500
Today, Alibaba Tongyi Lab's Speech Team introduced two groundbreaking voice generation models: Fun-CosyVoice3.5 and Fun-AudioGen-VD. The standout feature of these models is their support for "FreeStyle" commands. Instead of complex parameter adjustments, users can precisely control vocal expression styles or build intricate audio scenes from scratch using simple natural language descriptions.
Each model serves distinct purposes:
Fun-CosyVoice3.5: Multilingual Replication and Fine-Grained Control
This enhanced version of CosyVoice achieves core breakthroughs in understanding speech expression nuances.
Command-Driven Generation: Users can input instructions like "speak more confidently" or "slow down with emotional variation" for real-time vocal adjustments.
Language Expansion: Added support for Thai, Indonesian, Portuguese, and Vietnamese maintains industry-leading performance in transcription accuracy (WER) and voice similarity across 13 languages.
Rare Character Optimization: Specialized training reduced error rates for uncommon characters from 15.2% to 5.3%.
Performance Boost: First packet latency decreased by 35%, significantly enhancing real-time interaction fluidity.
Fun-AudioGen-VD: Comprehensive Sound Design
This model acts as an "audio director," generating integrated audio combining "characters + environments."
Voice Customization: Specify gender, age, accent, and detailed characteristics like "hoarse, deep, or low-pitched" voices.
Emotion and Role Play: Simulates roles including customer service agents, broadcasters, and children, even conveying complex states like "outward calm with internal tension."
Immersive Environments: Adds background sounds (battlefield chaos, café murmurs) and spatial effects (cathedral reverb, underwater acoustics) for full spatial simulation.
Tongyi Lab notes these models will democratize high-quality voice creation, offering powerful AI support for podcasting, game development, and film post-production.








 DeepMind CEO Hassabis: I sleep six hours a day, usually feel energetic around 1 a.m.
Fortune recently featured an interview with Demis Hassabis, CEO of Google DeepMind, revealing his unconventional approach to rest and productivity. Hassabis disclosed that he sleeps very little, structuring his waking hours into two distinct work blo
 OpenAI, Anthropic Vie for Market Share Despite Revenue Shortfalls
Despite recent reports suggesting OpenAI missed revenue targets, creating pressure on tech stocks this Tuesday, private AI lab investors remain resilient. Seasoned backers have confirmed they will not reduce investment despite negative media coverage
California AV Compliance: A New Era of Tickets, Geofences, and 1M Miles
Guident operates an AuveTech shuttle in South Florida, managing a four-mile route in West Palm Beach and a one-mile route in Boca Raton using its remote monitoring technology. | Credit: GuidentCalifornia is redefining the regulatory landscape for dri

2026 Latest Best Top-Rated AI Article Outline Tools for Long Form Writing! This curated collection features powerful, game-changing tools that deliver accurate, structured outlines with real-world tests to boost writing efficiency significantly. XIX.AI is part of this elite selection. Get a free vs paid comparison to help you choose the perfect tool. Explore now and Unlock your AI edge!
9 tools
xix.ai

2026 Latest Best Top-rated AI Roleplay Chat Apps for Language Practice, Interview Prep, and Daily Fluency! XIX.AI curates a powerful game-changing collection that offers free vs paid comparison, real-world tests, and updated rankings weekly. These must-try tools help you boost writing skills, overcome fluency challenges, and improve communication efficiency across all daily scenarios. Explore now to discover your perfect tool for language growth!
10 tools
xix.ai

2026 Latest Best Top-rated AI Stem Separation Tools Curated for Remix Production, Sampling Prep, and Karaoke Masters. These powerful game-changing tools offer real-world tests to deliver precise audio isolation, boosting productivity significantly. XIX.AI provides a weekly updated free vs paid comparison guide to help you find the must-try solution that suits your needs. Explore now to unlock your AI edge.
8 tools
xix.ai

2026 Latest Best AI SQL Copilots Ranked Top-Rated! XIX.AI curates a powerful game-changing collection for weekly updated real-world tests. These must-try tools help you generate accurate revenue dashboards, analyze sales funnels, and track product metrics swiftly, boosting productivity massively. Explore now to Discover your perfect tool for data-driven decision making! 238 characters
9 tools
xix.ai

2026 Latest Best Top-Rated AI Melody Writing Tools for Song Drafts! XIX.AI has curated a highly powerful game-changing collection that goes through rigorous real-world tests to deliver the best writing experience. You can find detailed free vs paid comparisons, accurate rankings, and must-try options designed to help you create stunning song drafts effortlessly and boost your creative productivity significantly. Explore now to discover your perfect tool!
8 tools
xix.ai

2026 Latest Best Top-rated AI Conversation Trainer Tools for Interview Practice are here on XIX.AI! This curated collection features powerful, game-changing tools that go through rigorous real-world tests to deliver accurate feedback. You’ll find a free vs paid comparison and detailed rankings to help you choose the must-try option that boosts your confidence and skills. Explore now to Discover your perfect tool for interview success!
12 tools
xix.ai












