
option
Home
Flash News
Content
AlbertJones
AlbertJones
May 21, 2026

Zhipu AI and partners implemented the ZCube network architecture in its GLM-5.1 coding production environment, achieving a system-level breakthrough. The new architecture reduced switch and optical module capex by 33%, increased average GPU inference throughput by 15%, and cut first token latency by 40.6%. It solves structural bottlenecks in large-model inference by replacing traditional hierarchical designs with a flat, bipartite graph interconnection for perfect traffic load balancing.
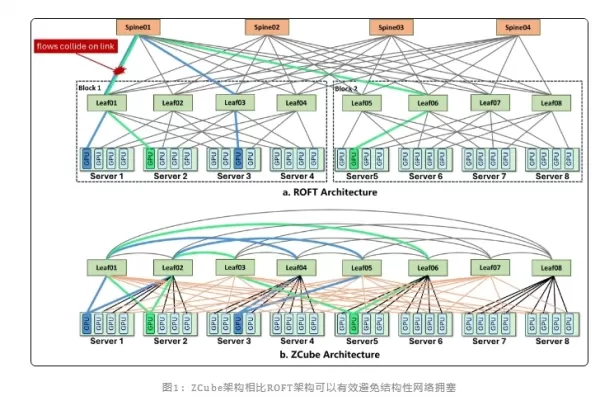
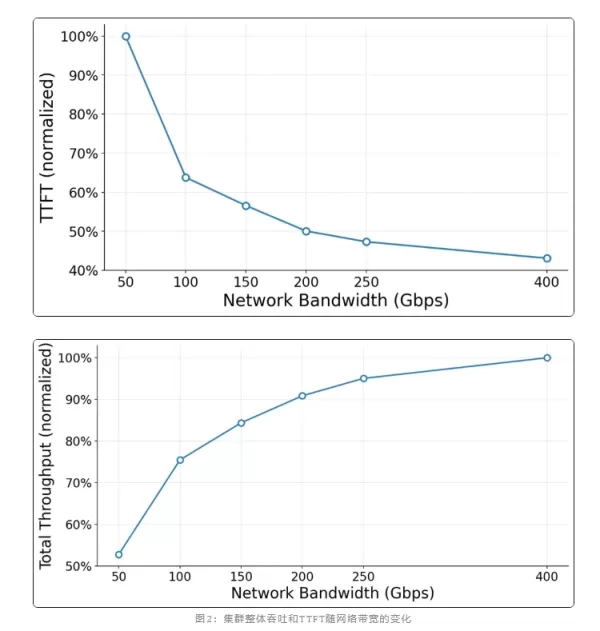
Zhipu AI and partners implemented the ZCube network architecture in its GLM-5.1 coding production environment, achieving a system-level breakthrough. The new architecture reduced switch and optical module capex by 33%, increased average GPU inference throughput by 15%, and cut first token latency by 40.6%. It solves structural bottlenecks in large-model inference by replacing traditional hierarchical designs with a flat, bipartite graph interconnection for perfect traffic load balancing. Zhipu AI and partners implemented the ZCube network architecture in its GLM-5.1 coding production environment, achieving a system-level breakthrough. The new architecture reduced switch and optical module capex by 33%, increased average GPU inference throughput by 15%, and cut first token latency by 40.6%. It solves structural bottlenecks in large-model inference by replacing traditional hierarchical designs with a flat, bipartite graph interconnection for perfect traffic load balancing.
Comments (0)
0/300
OR