


 Home
LPM1.0 Model Generates Real-Time Interactive Digital Human Video from Single Image
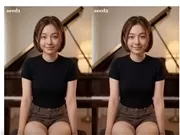
Researchers have officially unveiled the LPM1.0 model, a project designed to generate real-time videos of people speaking, listening, and singing from a single reference image. Its key breakthrough lies in multimodal processing—synchronizing text, audio, and image inputs to produce dynamic scenes with accurate lip sync, nuanced facial expressions, and natural emotional transitions. The model integrates directly with leading voice AI platforms like ChatGPT and Doubao, transforming conventional voice conversations into real-time interactive experiences with visual feedback.
Technically, LPM1.0 employs "multi-granularity identity conditioning" to extract detailed features from reference materials across multiple angles and expressions, eliminating the need for the model to independently generate complex elements like teeth, wrinkles, or side profiles. This greatly boosts cross-style processing—enabling instant drive for photorealistic faces, animations, or 3D game characters without retraining. The model also supports streaming transmission, ensuring system stability even when generating videos up to 45 minutes long.
Regarding interaction logic, LPM1.0 accurately detects three conversational states: while listening, it produces responsive expressions like nodding or shifting gaze; while speaking, it drives body and lip movements based on audio; while idle, it generates natural resting behaviors according to text prompts. Project manager Zeng Ailing noted that LPM1.0 is suitable not only for real-time conversation but also for offline audio-driven video generation, offering technical redundancy for podcasts and film production.
Despite its strong application potential, the development team stresses that LPM1.0 remains a research project with no current plans to release code or weights publicly. Researchers acknowledge a qualitative gap between generated videos and real footage, and the inherent deepfake risks cannot be overlooked. The study's significance lies in charting the future evolution of AI systems—shifting from single logical interaction to multidimensional interaction incorporating emotional responses, eye contact, and visual embodiment.
Related article
 South Korea Breaks Ground on National AI Computing Center, Investing 2.5 Trillion Won with 2028 Target
South Korean outlet EtNews reports that groundbreaking for the Korea AI Computing Center (KOACC) took place on August 3 at the Solar City data center park in Sunan, Jeollanam-do. Backed by a total investment of 2.5 trillion KRW (roughly 11.838 billio
Six Tech Giants Back Linux Foundation With $12.5M to Tackle AI Vulnerability Noise
To tackle the flood of low-quality security reports produced by AI automation tools, six major tech companies—Anthropic, Amazon (AWS), GitHub, Google, Microsoft, and OpenAI—have collectively contributed $12.5 million in funding to Linux Foundation in
Musk Considered Leaving OpenAI to His Kids as Altman Testifies
This morning, OpenAI CEO Sam Altman took the stand to address former co-founder Elon Musk’s lawsuit challenging the company’s corporate structure.When asked about Musk’s claim that other founders “stole a charity” by launching a for-profit subsidiary
Related Special Topic Recommendations
Music composition
 AI Vocal Demo Tools for Songwriters, Hooks, Toplines, and Multilingual Draft Sessions
2026 Latest Best AI Vocal Demo Tools for Songwriters, Hook Creators, and Multi-Language Content Teams! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparison data, comprehensive rankings, and must-try options to help you boost writing efficiency and unlock your creative potential. Explore now to discover your perfect tool for all your content needs!
 9 tools
 xix.ai
Business
Best AI Competitive Research Tools for Small Businesses
2026 Latest Best Top-rated AI Competitive Research Tools for Small Businesses! XIX.AI has curated a highly powerful game-changing collection, updated weekly with rigorous real-world tests and detailed rankings. You can find a comprehensive free vs paid comparison to help you identify the must-try tools that boost your productivity and give you a competitive edge. Explore now to discover your perfect tool!
9 tools
xix.ai
Image editing
Photoshop AI Retouch Tools for Ecommerce Apparel, Skin Cleanup, and Color Consistency
2026 Latest Best Photoshop AI retouch tools for ecommerce apparel, skin cleanup, and color consistency! This top-rated curated list features powerful game-changing solutions that help you boost writing efficiency, streamline content creation, and achieve perfect visual results effortlessly. Each tool has undergone real-world tests through weekly updated rankings, complete with free vs paid comparison details. Backed by XIX.AI, it’s the must-try guide for anyone aiming to unlock your AI edge. Explore now!
10 tools
xix.ai
Prompt
Best AI Prompt Libraries for ChatGPT Workflows
2026 Latest Best Top-Rated AI Prompt Libraries for optimizing all types of ChatGPT workflows. XIX.AI has curated a powerful, game-changing collection that goes through rigorous real-world tests to ensure top performance. You can find detailed free vs paid comparisons and expert rankings to help you choose the must-try tools that boost your productivity and unlock your AI edge. Explore now!
11 tools
xix.ai
Education and Learning
AI Quiz Builder Platforms for Teachers, Tutors, and Cohort-Based Learning Programs
2026 Latest Best AI Quiz Builder Platforms for Teachers, Tutors, and Cohort-Based Learning Programs! XIX.AI has curated a top-rated list of powerful game-changing tools that go through real-world tests to deliver accurate rankings. These must-try platforms help boost writing efficiency, streamline content creation, and simplify quiz design across all learning scenarios. Explore now to discover your perfect tool for unlocking your AI edge in teaching!
13 tools
xix.ai
code
AI Pull Request Review Tools for GitHub Teams Handling Refactors, Bugs, and Security Gaps
2026 Latest Best AI Pull Request Review Tools for GitHub Teams are here on XIX.AI! This top-rated curated list showcases powerful game-changing solutions that streamline refactoring, bug fixing, and security gap detection across all team workflows. Enjoy a free vs paid comparison along with real-world tests and detailed rankings to help you find the perfect tool that boosts productivity significantly. Explore now to unlock your AI edge!
12 tools
xix.ai

 Comments (0)
0/500
Researchers have officially unveiled the LPM1.0 model, a project designed to generate real-time videos of people speaking, listening, and singing from a single reference image. Its key breakthrough lies in multimodal processing—synchronizing text, audio, and image inputs to produce dynamic scenes with accurate lip sync, nuanced facial expressions, and natural emotional transitions. The model integrates directly with leading voice AI platforms like ChatGPT and Doubao, transforming conventional voice conversations into real-time interactive experiences with visual feedback.
Technically, LPM1.0 employs "multi-granularity identity conditioning" to extract detailed features from reference materials across multiple angles and expressions, eliminating the need for the model to independently generate complex elements like teeth, wrinkles, or side profiles. This greatly boosts cross-style processing—enabling instant drive for photorealistic faces, animations, or 3D game characters without retraining. The model also supports streaming transmission, ensuring system stability even when generating videos up to 45 minutes long.
Regarding interaction logic, LPM1.0 accurately detects three conversational states: while listening, it produces responsive expressions like nodding or shifting gaze; while speaking, it drives body and lip movements based on audio; while idle, it generates natural resting behaviors according to text prompts. Project manager Zeng Ailing noted that LPM1.0 is suitable not only for real-time conversation but also for offline audio-driven video generation, offering technical redundancy for podcasts and film production.
Despite its strong application potential, the development team stresses that LPM1.0 remains a research project with no current plans to release code or weights publicly. Researchers acknowledge a qualitative gap between generated videos and real footage, and the inherent deepfake risks cannot be overlooked. The study's significance lies in charting the future evolution of AI systems—shifting from single logical interaction to multidimensional interaction incorporating emotional responses, eye contact, and visual embodiment.








 South Korea Breaks Ground on National AI Computing Center, Investing 2.5 Trillion Won with 2028 Target
South Korean outlet EtNews reports that groundbreaking for the Korea AI Computing Center (KOACC) took place on August 3 at the Solar City data center park in Sunan, Jeollanam-do. Backed by a total investment of 2.5 trillion KRW (roughly 11.838 billio
 Six Tech Giants Back Linux Foundation With $12.5M to Tackle AI Vulnerability Noise
To tackle the flood of low-quality security reports produced by AI automation tools, six major tech companies—Anthropic, Amazon (AWS), GitHub, Google, Microsoft, and OpenAI—have collectively contributed $12.5 million in funding to Linux Foundation in
 Musk Considered Leaving OpenAI to His Kids as Altman Testifies
This morning, OpenAI CEO Sam Altman took the stand to address former co-founder Elon Musk’s lawsuit challenging the company’s corporate structure.When asked about Musk’s claim that other founders “stole a charity” by launching a for-profit subsidiary

2026 Latest Best AI Vocal Demo Tools for Songwriters, Hook Creators, and Multi-Language Content Teams! XIX.AI has curated a top-rated list of powerful game-changing tools that go through rigorous real-world tests. You’ll find detailed free vs paid comparison data, comprehensive rankings, and must-try options to help you boost writing efficiency and unlock your creative potential. Explore now to discover your perfect tool for all your content needs!
9 tools
xix.ai

2026 Latest Best Top-rated AI Competitive Research Tools for Small Businesses! XIX.AI has curated a highly powerful game-changing collection, updated weekly with rigorous real-world tests and detailed rankings. You can find a comprehensive free vs paid comparison to help you identify the must-try tools that boost your productivity and give you a competitive edge. Explore now to discover your perfect tool!
9 tools
xix.ai

2026 Latest Best Photoshop AI retouch tools for ecommerce apparel, skin cleanup, and color consistency! This top-rated curated list features powerful game-changing solutions that help you boost writing efficiency, streamline content creation, and achieve perfect visual results effortlessly. Each tool has undergone real-world tests through weekly updated rankings, complete with free vs paid comparison details. Backed by XIX.AI, it’s the must-try guide for anyone aiming to unlock your AI edge. Explore now!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Prompt Libraries for optimizing all types of ChatGPT workflows. XIX.AI has curated a powerful, game-changing collection that goes through rigorous real-world tests to ensure top performance. You can find detailed free vs paid comparisons and expert rankings to help you choose the must-try tools that boost your productivity and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best AI Quiz Builder Platforms for Teachers, Tutors, and Cohort-Based Learning Programs! XIX.AI has curated a top-rated list of powerful game-changing tools that go through real-world tests to deliver accurate rankings. These must-try platforms help boost writing efficiency, streamline content creation, and simplify quiz design across all learning scenarios. Explore now to discover your perfect tool for unlocking your AI edge in teaching!
13 tools
xix.ai

2026 Latest Best AI Pull Request Review Tools for GitHub Teams are here on XIX.AI! This top-rated curated list showcases powerful game-changing solutions that streamline refactoring, bug fixing, and security gap detection across all team workflows. Enjoy a free vs paid comparison along with real-world tests and detailed rankings to help you find the perfect tool that boosts productivity significantly. Explore now to unlock your AI edge!
12 tools
xix.ai












