


 Home
iPhone 17 Pro Runs 400B Parameter Model Locally at 0.6 Tokens Per Second
What defines the computational ceiling of modern smartphones? Apple’s newest flagship, the iPhone17Pro , has provided an answer that is as impressive as it is humbling.
On March 23, a large language model featuring 400 billion parameters was successfully executed on the iPhone17Pro . Notably, even after quantization, such models typically demand at least 200GB of memory, whereas the iPhone17Pro is equipped with only 12GB of LPDDR5X RAM.
Technical Innovation: Flash Memory Streaming and Mixture of Experts (MoE)
Overcoming severe memory constraints, this "impossible feat" was primarily achieved through two key technical strategies:
SSD as Virtual Memory: Leveraging the open-source Flash-MoE project, the device streams data directly from the solid-state drive (SSD) to the GPU, effectively bypassing physical memory limitations.
MoE Architecture Benefits: "MoE" stands for Mixture of Experts, a design where the system activates only a subset of the 400 billion parameters for each generated word, rather than loading the entire model.
Performance Trade-off: Slow Generation Speed
While the execution was successful, the user experience remains far from practical. Test results indicate:
Generation Rate: The speed is limited to 0.6 Tokens per second, meaning it takes approximately 1.5 to 2 seconds to produce a single word.
Power and Thermal Impact: This intensive local processing rapidly depletes battery life and generates significant heat.
Industry Perspective: Is Local AI Reaching a "Singularity"?
Despite the current generation speed being suboptimal, the symbolic importance of this demonstration outweighs its immediate utility. It proves that running large-scale models locally on smartphones is a viable path.
Enhanced Privacy: Local processing ensures data remains on the device, eliminating the need for cloud uploads and offering superior privacy.
Offline Capability: Accessing advanced AI responses without an internet connection is becoming increasingly feasible.
Related article
 Google updates Gemini app to compete with ChatGPT and Claude at IO 2026
During Tuesday’s annual Google I/O event, Google unveiled a suite of updates for the Gemini app, introducing a “Daily Brief” feature, a revamped interface, access to the new Gemini Omni AI video model, and a personal AI agent named Gemini Spark.These
Qianwen Creation Unveils 7-Day Membership With 200 Points and Fast-Track Tools for Travel Photography
Qwen Create has officially launched a 7-day membership plan designed for immediate, lightweight AI creation tasks, including travel photography, event marketing, and social media content. Upon purchase, users receive 200 points, access to exclusive f
iOS 27.2 Beta Brings Major Health App Overhaul and Siri Expands to Five Languages
Apple has just released the first iOS 27.2 beta for developers. Skipping the expected iOS 27.1 test phase, Apple launched the 27.2 testing cycle directly on September 16, pushing initial betas for iOS, iPadOS, macOS, watchOS, tvOS, and visionOS simul
Related Special Topic Recommendations
Design & Art
 Top AI Illustration Tools: Create Editorial Scenes and Cover Art Faster
2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
 10 tools
 xix.ai
Education and Learning
Top AI Tutors for Exam Prep: Practice Math, Science, and English
2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai
Finance
AI Budget Planning Tools for Personal Money Management
2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai
Health & Wellness
AI Sleep Tracking Assistants: Improve Recovery with Better Bedtime Habits
2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai
Data Analysis
AI SQL Copilots for Product and Revenue Analytics
2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai
Education and Learning
Best AI Homework Helpers That Teach: Learn Concepts, Not Just Answers
2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai

 Comments (0)
0/500
What defines the computational ceiling of modern smartphones? Apple’s newest flagship, the
On March 23, a large language model featuring 400 billion parameters was successfully executed on the
Technical Innovation: Flash Memory Streaming and Mixture of Experts (MoE)
Overcoming severe memory constraints, this "impossible feat" was primarily achieved through two key technical strategies:
SSD as Virtual Memory: Leveraging the open-source Flash-MoE project, the device streams data directly from the solid-state drive (SSD) to the GPU, effectively bypassing physical memory limitations.
MoE Architecture Benefits: "MoE" stands for Mixture of Experts, a design where the system activates only a subset of the 400 billion parameters for each generated word, rather than loading the entire model.
Performance Trade-off: Slow Generation Speed
While the execution was successful, the user experience remains far from practical. Test results indicate:
Generation Rate: The speed is limited to 0.6 Tokens per second, meaning it takes approximately 1.5 to 2 seconds to produce a single word.
Power and Thermal Impact: This intensive local processing rapidly depletes battery life and generates significant heat.
Industry Perspective: Is Local AI Reaching a "Singularity"?
Despite the current generation speed being suboptimal, the symbolic importance of this demonstration outweighs its immediate utility. It proves that running large-scale models locally on smartphones is a viable path.
Enhanced Privacy: Local processing ensures data remains on the device, eliminating the need for cloud uploads and offering superior privacy.
Offline Capability: Accessing advanced AI responses without an internet connection is becoming increasingly feasible.








 Google updates Gemini app to compete with ChatGPT and Claude at IO 2026
During Tuesday’s annual Google I/O event, Google unveiled a suite of updates for the Gemini app, introducing a “Daily Brief” feature, a revamped interface, access to the new Gemini Omni AI video model, and a personal AI agent named Gemini Spark.These
 Qianwen Creation Unveils 7-Day Membership With 200 Points and Fast-Track Tools for Travel Photography
Qwen Create has officially launched a 7-day membership plan designed for immediate, lightweight AI creation tasks, including travel photography, event marketing, and social media content. Upon purchase, users receive 200 points, access to exclusive f
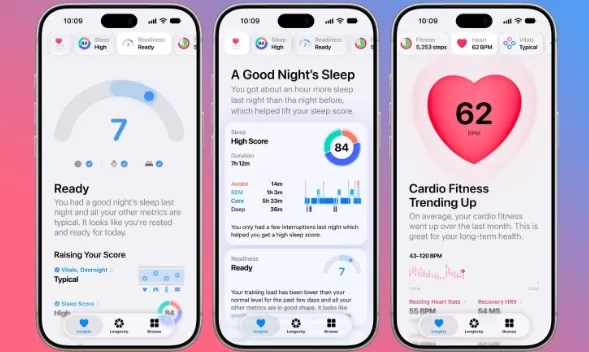 iOS 27.2 Beta Brings Major Health App Overhaul and Siri Expands to Five Languages
Apple has just released the first iOS 27.2 beta for developers. Skipping the expected iOS 27.1 test phase, Apple launched the 27.2 testing cycle directly on September 16, pushing initial betas for iOS, iPadOS, macOS, watchOS, tvOS, and visionOS simul

2026 Latest Top-rated AI Illustration Tools: Our curated list features the best powerfully designed tools for creating stunning editorial scenes and eye-catching cover art quickly. Each option has gone through rigorous real-world tests, offering a free vs paid comparison to help you find the perfect match for your workflow. Try these must-try solutions today to unlock your AI edge and boost your creative productivity. Explore now at XIX.AI.
10 tools
xix.ai

2026 Latest Top-Rated Best AI Tutors for Exam Prep are here on XIX.AI! Our curated list features powerful game-changing tools that offer free vs paid comparison, real-world tests, and weekly updated rankings. They help boost your writing efficiency, simplify complex topic learning, and unlock your academic potential. Explore now to Discover your perfect exam prep tool and Start creating today to Unlock your AI edge!
10 tools
xix.ai

2026 Latest Best Top-Rated AI Budget Planning Tools for Personal Money Management are here on XIX.AI! This curated collection features powerful, game-changing solutions that help you conduct real-world tests, understand spending habits, and create personalized plans to boost productivity. Enjoy a free vs paid comparison along with detailed rankings. Must-try tools designed to simplify money management and unlock your AI edge. Explore now!
11 tools
xix.ai

2026 Latest Best Top-Rated AI Sleep Tracking Assistants curated for ultimate recovery. This fully updated weekly guide features powerful tools that deliver real-world tests, free vs paid comparison, and detailed rankings to help you find the must-try solution that boosts sleep quality and supports better bedtime habits. Explore now at XIX.AI to Unlock your AI edge.
10 tools
xix.ai

2026 Latest Best Top-Rated AI SQL Copilots for Product and Revenue Analytics! XIX.AI has curated a powerful, game-changing collection of must-try tools that undergo real-world tests through weekly updated rankings. These tools help users boost productivity significantly by accelerating data analysis, streamlining complex queries, and generating accurate insights to drive smarter business decisions. Explore now to Discover your perfect tool for unlocking your AI edge!
14 tools
xix.ai

2026 Latest Best Top-Rated AI Homework Helpers That Teach Core Concepts Not Just Answers Powerful Tools for Students Must-Try Curated List Weekly Updated Free vs Paid Comparison Real-World Tests Accurate Rankings to Help You Unlock Your Full Learning Potential Explore now to Discover your perfect tool for smarter studying.
10 tools
xix.ai












