option
Home
Flash News
Content
RonaldRoberts
RonaldRoberts
July 20, 2026

Meituan's LongCat launched LoHoSearch, a tougher benchmark replacing BrowseComp. It auto-generates questions from 7.62M Wikipedia entities, removing difficulty ceilings. Top models scored only 34.74% vs 90% on BrowseComp, exposing search agents' true weaknesses. Context strategies yield minimal gains. The 544-question benchmark is open-sourced.
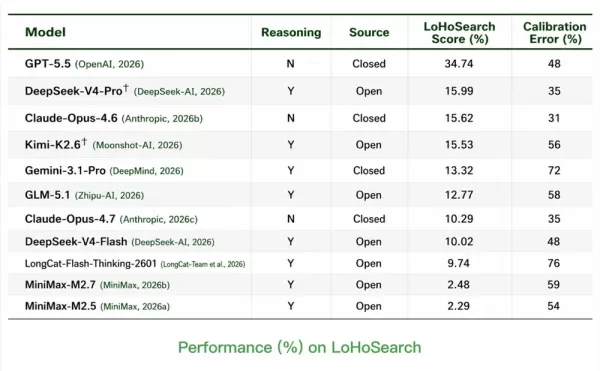
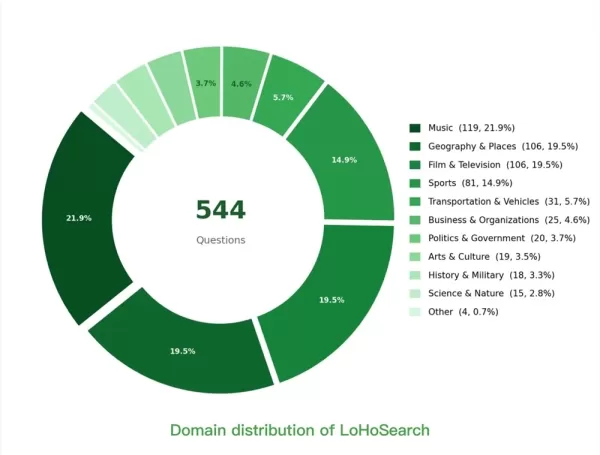
Meituan's LongCat launched LoHoSearch, a tougher benchmark replacing BrowseComp. It auto-generates questions from 7.62M Wikipedia entities, removing difficulty ceilings. Top models scored only 34.74% vs 90% on BrowseComp, exposing search agents' true weaknesses. Context strategies yield minimal gains. The 544-question benchmark is open-sourced. Meituan's LongCat launched LoHoSearch, a tougher benchmark replacing BrowseComp. It auto-generates questions from 7.62M Wikipedia entities, removing difficulty ceilings. Top models scored only 34.74% vs 90% on BrowseComp, exposing search agents' true weaknesses. Context strategies yield minimal gains. The 544-question benchmark is open-sourced.
Comments (0)
0/300
OR