Home

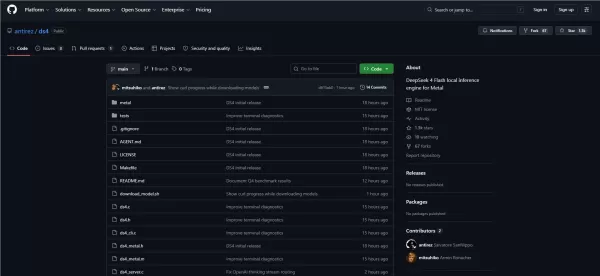
DeepSeek V4Flash launches as a specialized local AI inference engine for Apples Metal platform It features a smaller parameter count for faster processing a thinking mode that is five times quicker than other models and supports a 1 million token context window The engine can run 2bit quantization on a 128GB MacBook and provides a full local solution including HTTP API and GGUF models The current version is in Alpha stage
Comments (0)
0/300