option
Home
Flash News
Content
LawrencePerez
LawrencePerez
May 7, 2026

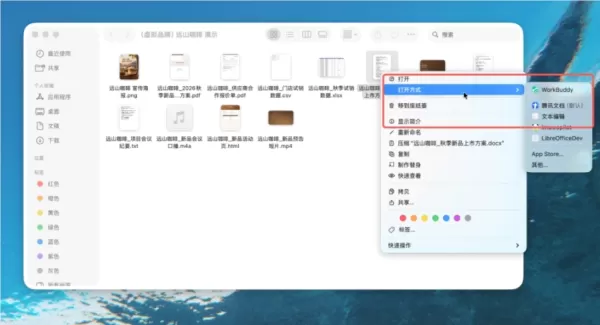
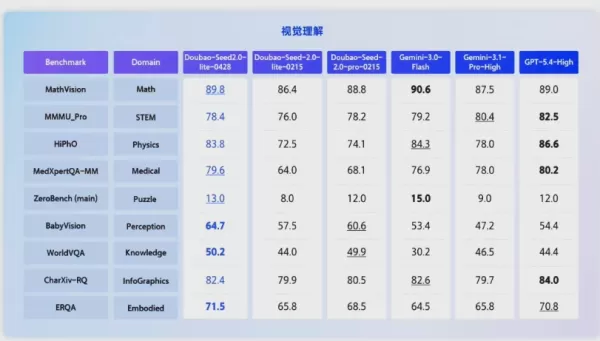
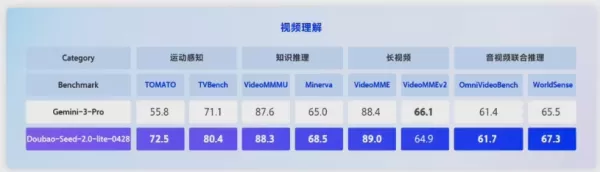
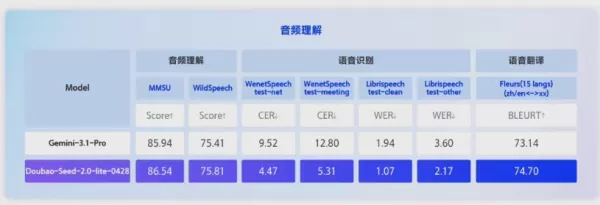
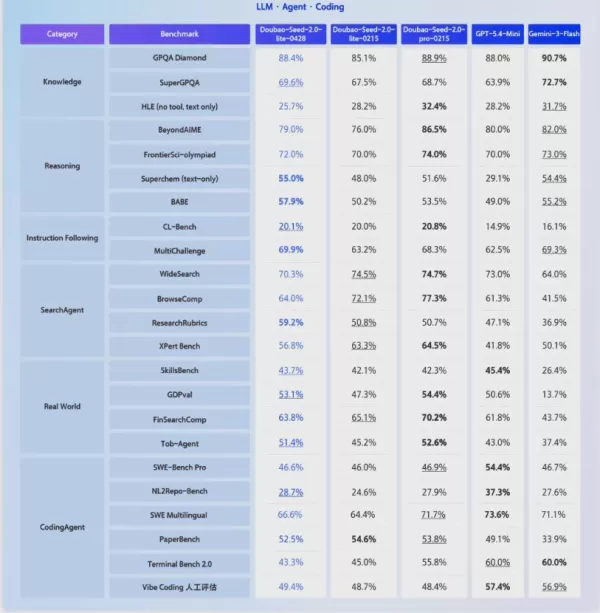
ByteDance's Volcano Engine launched Doubao-Seed-2.0-lite, its first full-modal AI model. It natively understands video, image, audio, and text, excelling in complex reasoning and fine-grained perception. The model features synchronized audio-visual reasoning, multilingual transcription, and enhanced Agent and Coding capabilities. It also achieves integrated GUI understanding and operation. The technology is already applied in e-sports, education, and e-commerce.
ByteDance's Volcano Engine launched Doubao-Seed-2.0-lite, its first full-modal AI model. It natively understands video, image, audio, and text, excelling in complex reasoning and fine-grained perception. The model features synchronized audio-visual reasoning, multilingual transcription, and enhanced Agent and Coding capabilities. It also achieves integrated GUI understanding and operation. The technology is already applied in e-sports, education, and e-commerce. ByteDance's Volcano Engine launched Doubao-Seed-2.0-lite, its first full-modal AI model. It natively understands video, image, audio, and text, excelling in complex reasoning and fine-grained perception. The model features synchronized audio-visual reasoning, multilingual transcription, and enhanced Agent and Coding capabilities. It also achieves integrated GUI understanding and operation. The technology is already applied in e-sports, education, and e-commerce. ByteDance's Volcano Engine launched Doubao-Seed-2.0-lite, its first full-modal AI model. It natively understands video, image, audio, and text, excelling in complex reasoning and fine-grained perception. The model features synchronized audio-visual reasoning, multilingual transcription, and enhanced Agent and Coding capabilities. It also achieves integrated GUI understanding and operation. The technology is already applied in e-sports, education, and e-commerce. ByteDance's Volcano Engine launched Doubao-Seed-2.0-lite, its first full-modal AI model. It natively understands video, image, audio, and text, excelling in complex reasoning and fine-grained perception. The model features synchronized audio-visual reasoning, multilingual transcription, and enhanced Agent and Coding capabilities. It also achieves integrated GUI understanding and operation. The technology is already applied in e-sports, education, and e-commerce.
Comments (0)
0/300
OR